MiniCPM-OCR 1.0 ships with Jev checker for region-level scoring
The 1.3B MiniCPM-OCR 1.0 leads real-world document benchmarks, and the 2B MiniCPM-OCR Jev checker scores each region to flag what still needs human review.
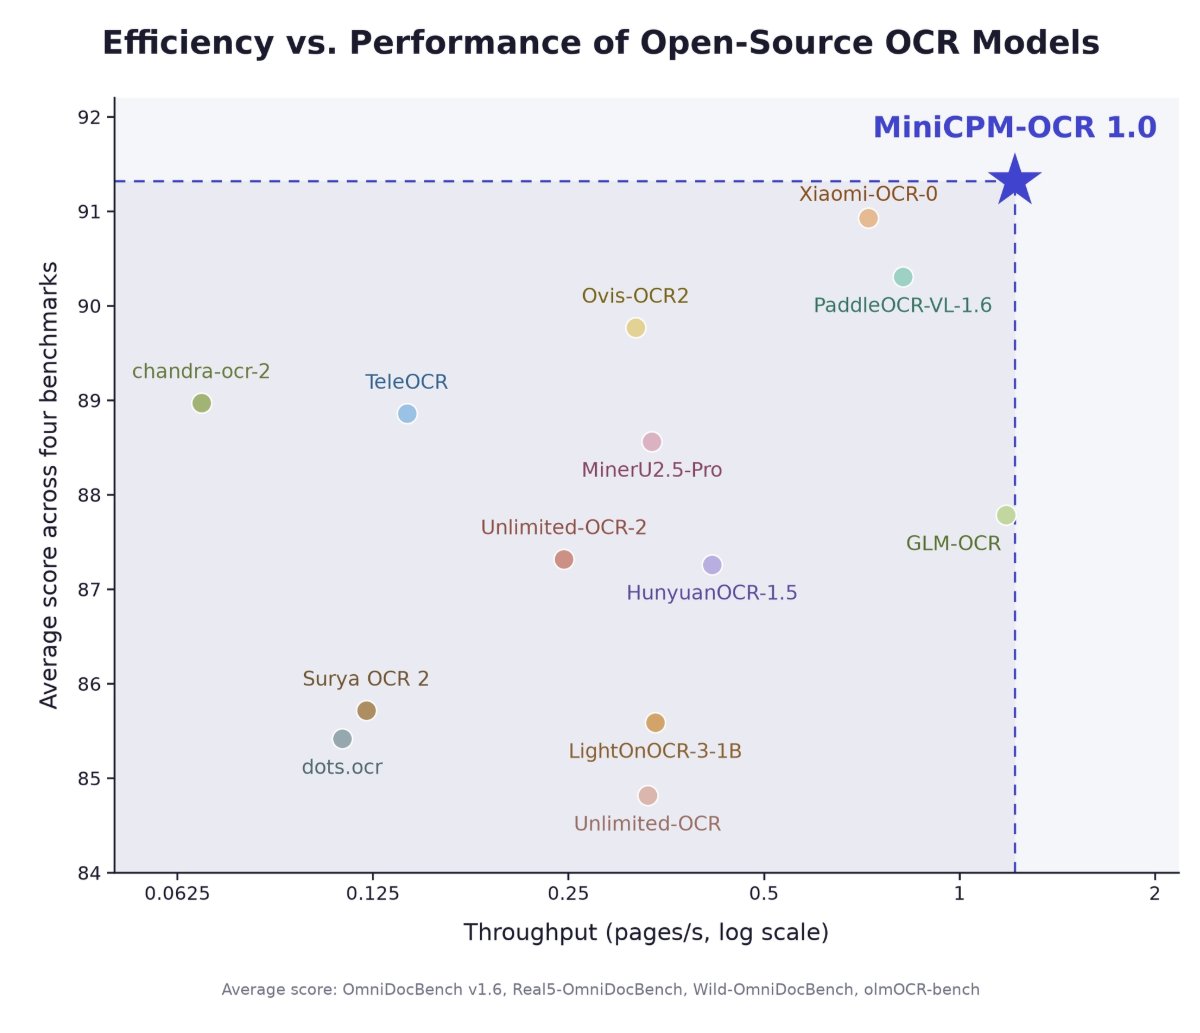
i can't stop looking at this chart MiniCPM-OCR 1.0 is a 1.3B model built only for reading documents, and it's the one dot in the top right, the highest average score across four document benchmarks and the most pages per second their numbers: > 93.68 on Real5-OmniDocBench > 92.39 on Wild-OmniDocBench > 54.7 on OCRBench v2 > 1.217 pages/s on one rtx 5090 > 1.49x PaddleOCR-VL-1.6 throughput > 3.62x MinerU2.5 Pro throughput the real-world scores are the ones i care about, real documents reach a model as a phone photo of a contract at an angle or a curved page out of a book, and that's where it leads, on the standard OmniDocBench v1.6 it sits 0.4 behind the top ocr is the input for everything after it, agents and rag pipelines are only as good as the text they pull out of a pdf, and one wrong digit on an invoice makes the whole chain confidently wrong that's why the companion model got my attention, MiniCPM-OCR Jev is a 2B checker that reads the page next to any ocr model's output and scores each region, so you know which parts a human still has to check > AUROC 0.936 on JevOCRBench > Qwen3.5-397B-A17B gets 0.938 the parser and the checker are small enough to run on your own gpu, so contracts and receipts never leave your machine, with llama.cpp, vllm, sglang and ollama supported on day one weights and code from @OpenBMB: Hugging Face: MiniCPM-OCR 1.0: https://huggingface.co/openbmb/MiniCPM-OCR-1.0 MiniCPM-OCR Jev: https://huggingface.co/openbmb/MiniCPM-OCR-Jev GitHub: https://github.com/OpenBMB/MiniCPM-OCR
This post quotes another post: “MiniCPM-OCR suite: 1B parser plus 2B Jev checker”