DeepSeek V4.1 Flash on 4x 3090: 57 tok/s and 256K context after tuning
Using the Project Maya engine and Maya-XS 1.6-bit quant on 4x 3090, a user raised decode from 33 to 57 tok/s and prefill from 1626 to 2642 tok/s, cutting a 128K prompt from 114s to 49s while enabling 256K context and image input.
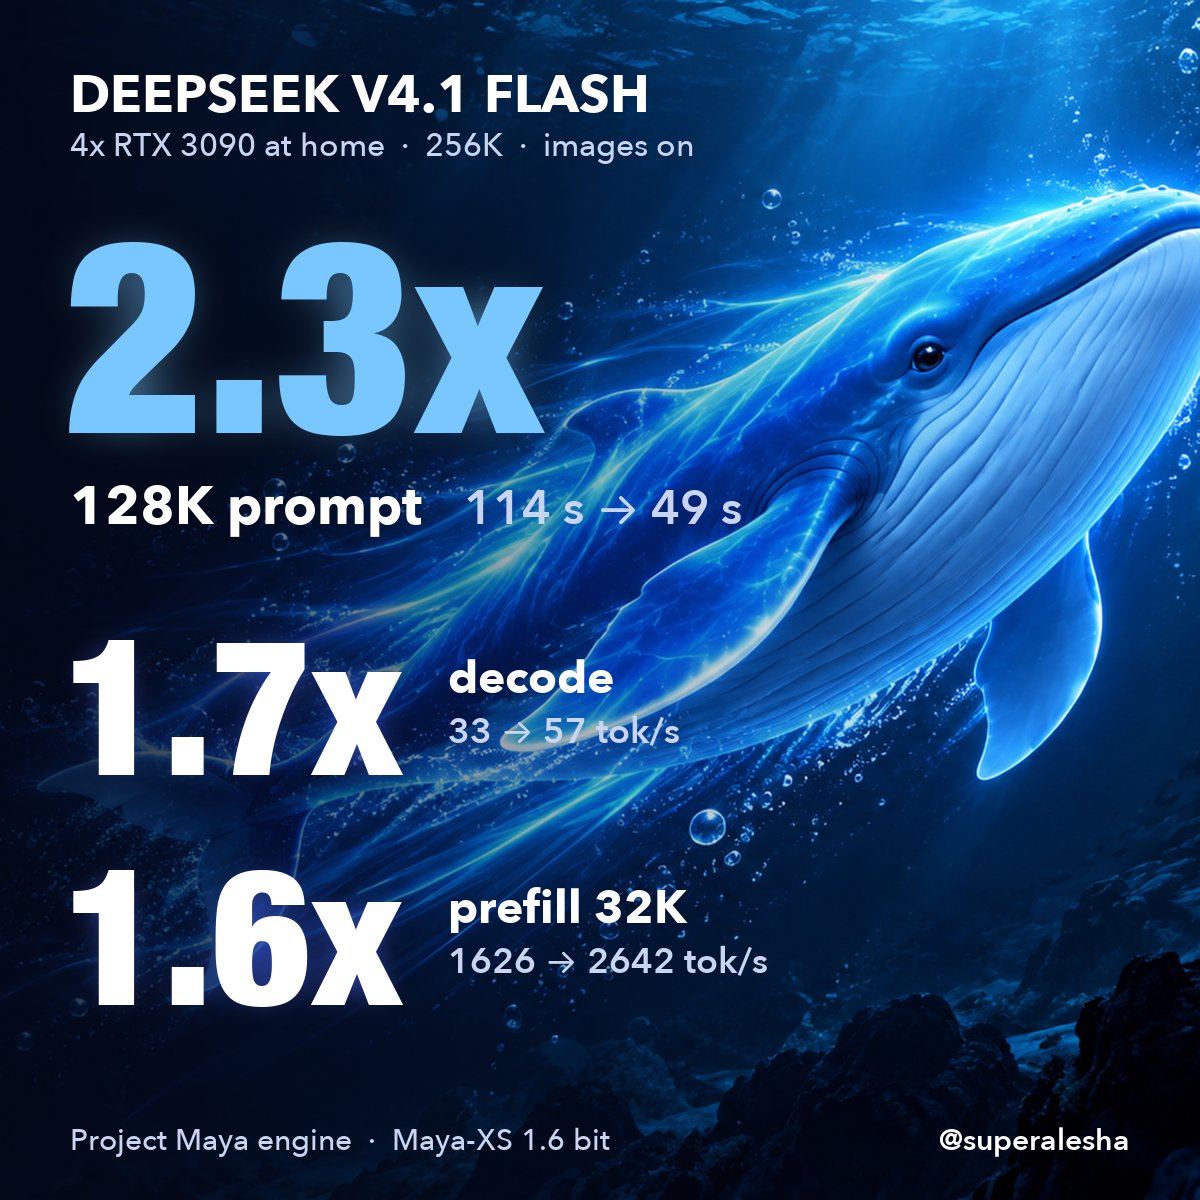
DeepSeek V4.1 Flash runs at 57 tok/s on my 4x 3090. Stock was 33. Prefill went from 1626 to 2642 tok/s at 32K. A 128K prompt now reads in 49s instead of 114s. And I did it with 256K context and images on. The stock setup was 64K, text only. The engine is Project Maya by @PeasantSmith , with the Maya-XS quant. It fits DeepSeek V4.1 Flash into ~107GB at ~1.6 bit. That still doesnt fit in 96GB of VRAM, so ~30% of the experts stay in RAM and run on my EPYC. That CPU part was the problem. ggml's IQ1_S kernel uses the pdep instruction. On Zen 2 pdep is microcoded and VERY slow. Every expert on the CPU took 1.6ms. Without pdep it takes 0.44ms, and the output is bit for bit the same. After that the PCIe lane that copies experts to the GPUs became slower than the CPU itself, so I turned it off. Another +17% decode. For prefill: pinned RAM, so experts go to the GPUs by DMA without an extra copy prompt split into smaller chunks, so all 4 GPUs work even on a 4K prompt (910 to 1543 tok/s) layers 20 to 39 skip most of a long prompt, the model only needs them on the last ~2.7K tokens The DSpark drafter that ships with the model finally pays off now: code from scratch went 21.6 to 49 tok/s. I also added prompt lookup drafts for agent edits, a file rewrite runs at 97 tok/s. Perplexity is the same as stock within run to run noise. Image input works, a picture prompt answers in 1.5s. I didnt expect a 1.6 bit DeepSeek to be usable at home with 256K context. Maya made it possible, I tuned it for my hardware. Huge respect to @PeasantSmith This one is a big deal for me