Running 428B MiniMax M3.1 Flash locally on 4x 3090: custom engine 5x faster prefill than llama.cpp
Using Unsloth's 2-bit GGUF (144GB) across 96GB VRAM plus system RAM, a custom forked engine hit 23–31 tok/s decode and 1120 tok/s prefill at 16K versus llama.cpp's 6.7 and 219 tok/s, with identical NLL and RAM bandwidth as the bottleneck.
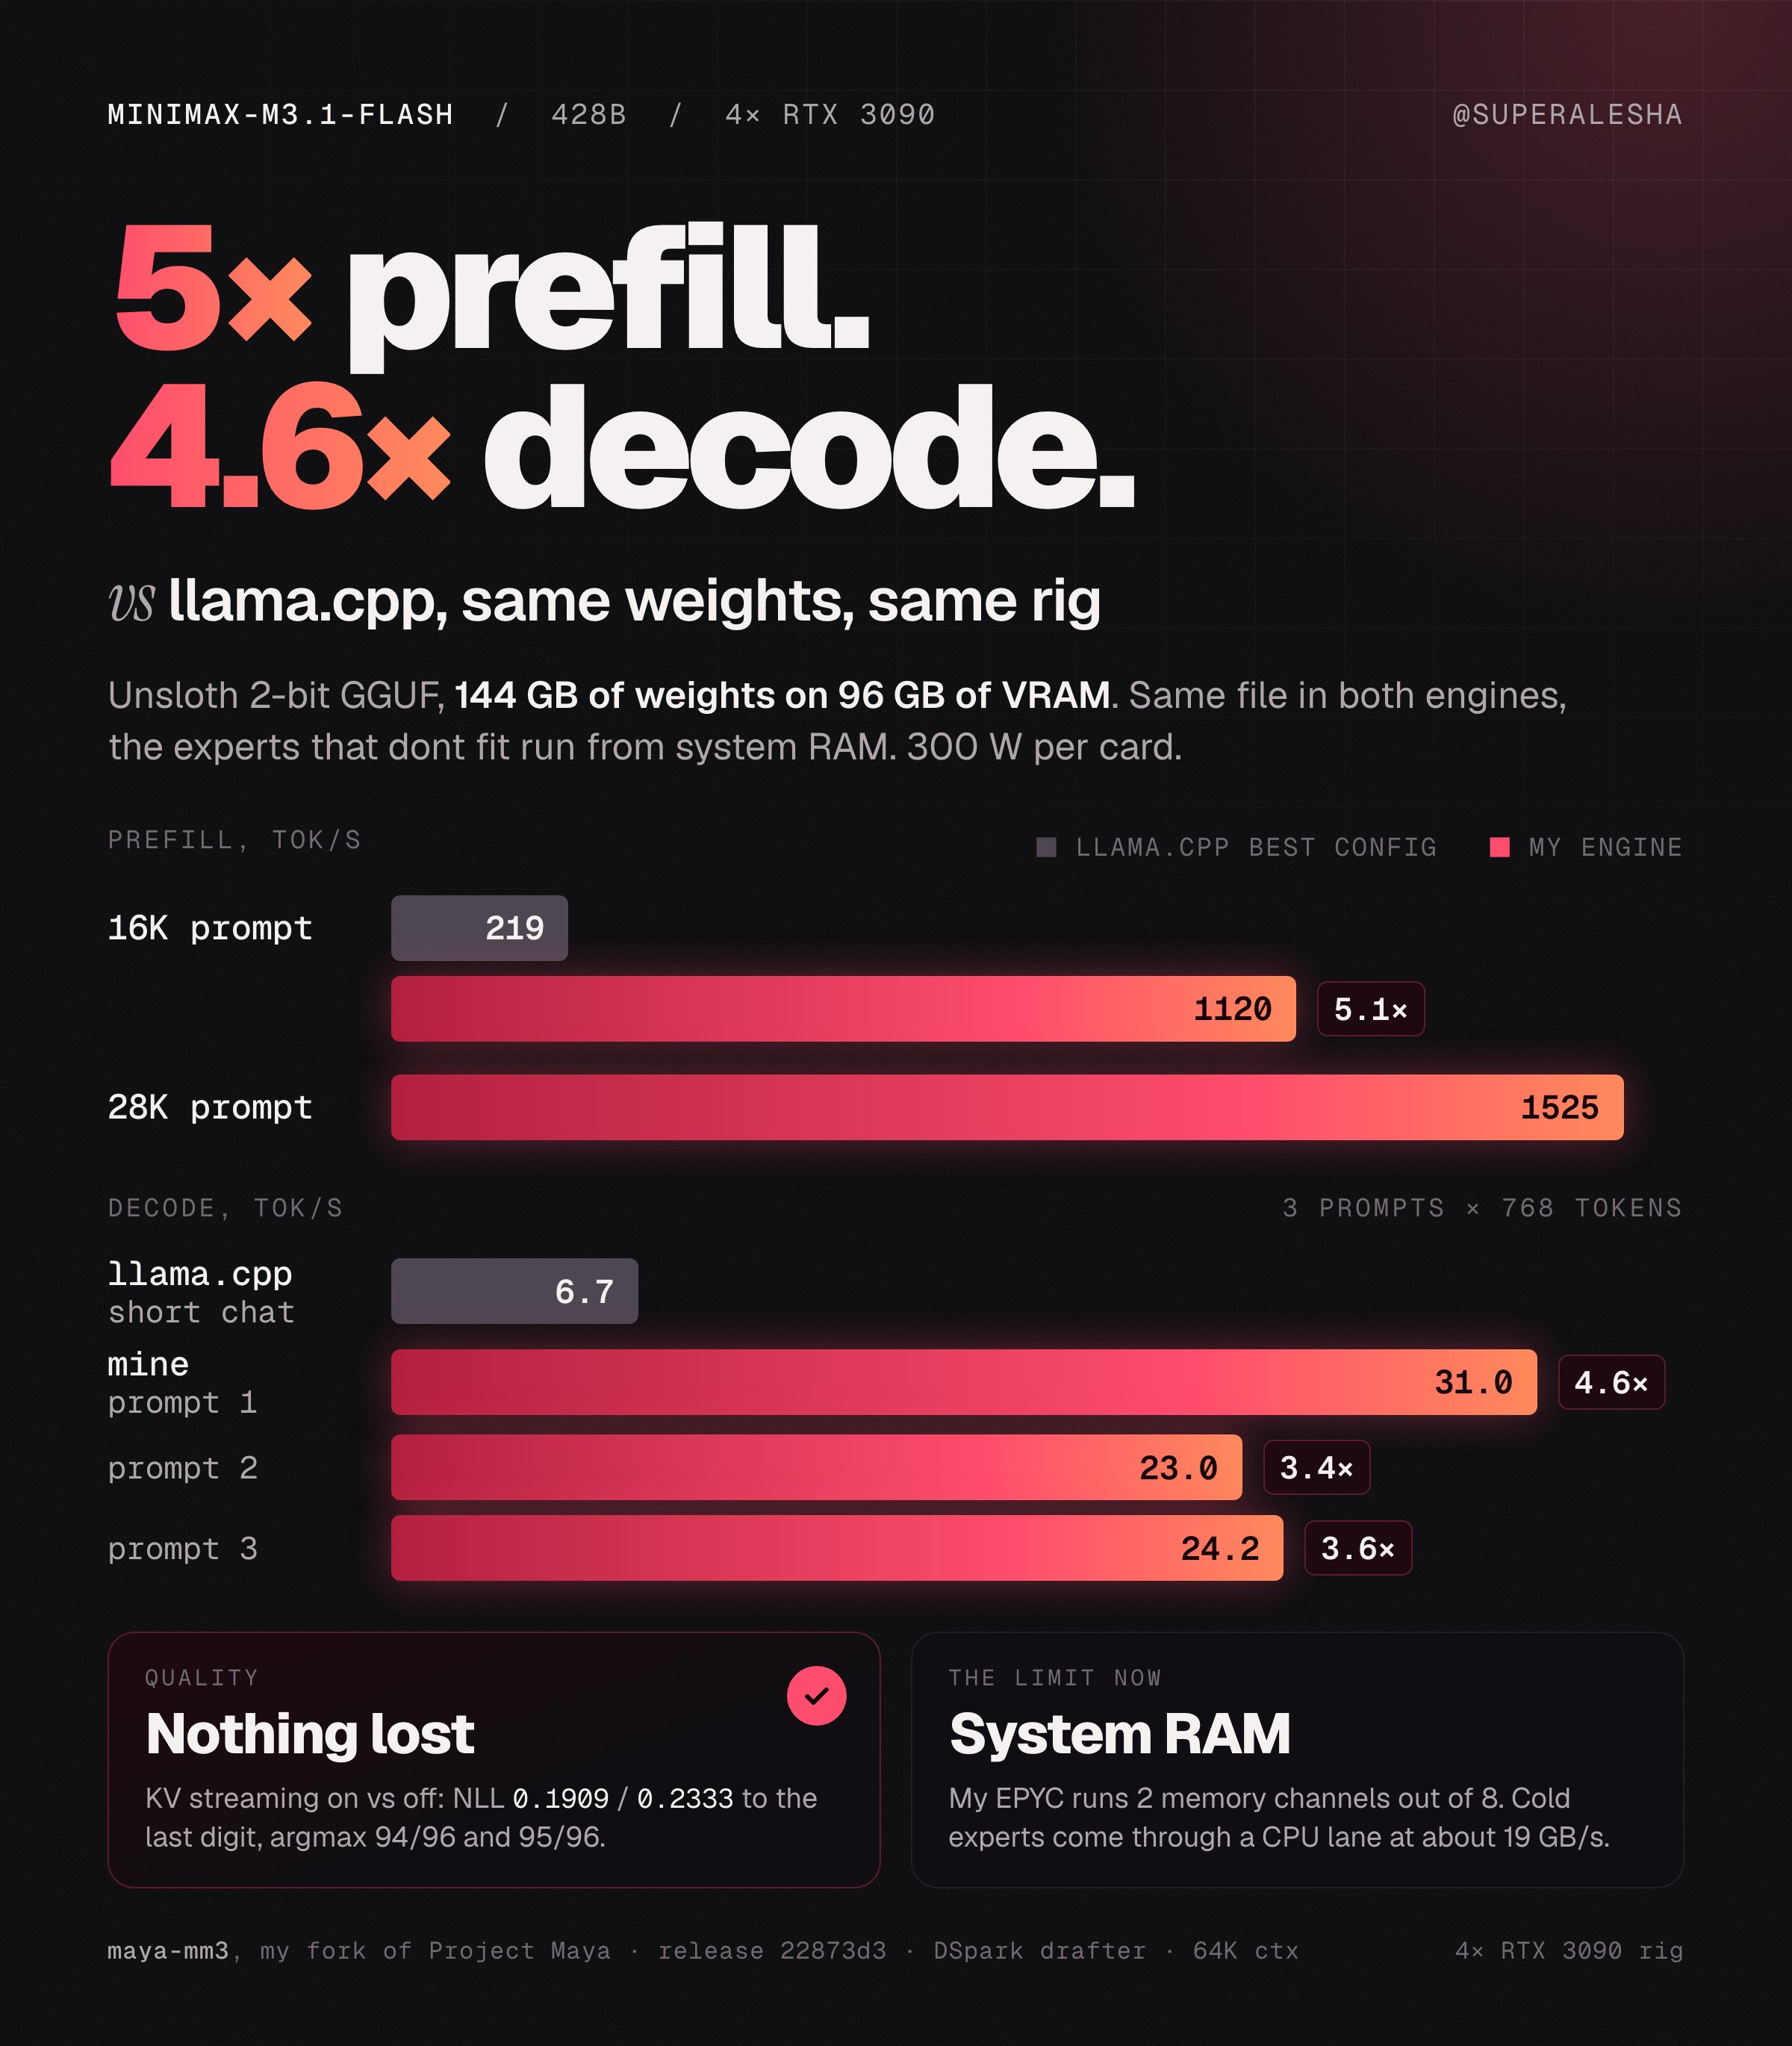
I made MiniMax-M3.1-Flash 5x faster at prefill than llama.cpp on my 4x 3090. Decode up to 4.6x. A 428B model, at home. Its the Unsloth 2-bit GGUF, 144 GB. My cards have 96 GB of VRAM, so the experts that dont fit run from system RAM. llama.cpp, best config I found: decode 6.7 tok/s, prefill 219 tok/s at 16K. My engine: decode 23 to 31 tok/s, prefill 1120 tok/s at 16K and 1525 at 28K. Nobody gave me this engine. I forked Maya, wrote the MiniMax path myself and keep the hot experts in VRAM with a cache that moves them during the answer. Then I added a DSpark drafter, and then I moved the long KV cache out to system RAM in blocks, so more experts fit on the cards. Quality didnt move at all, NLL is the same to the last digit. The limit now is RAM. My EPYC runs 2 memory channels out of 8, and cold experts come through the CPU at about 19 GB/s. 1M context, 428B params, 6 year old gaming cards. Show me someone else running this model locally at these numbers. Ill wait. Thanks @MiniMax_AI for the weights and @UnslothAI for the GGUF.