DeepSeek V4.1 Flash on 2x DGX Spark: 73 tok/s and full 1M context
TensorFold's two-node engine with an EXL3 2.9 bpw pack runs DeepSeek V4.1 Flash 1017 on two DGX Sparks at 73 tok/s single-user, 136 tok/s for four, reading a 93K prompt in 43.7s.
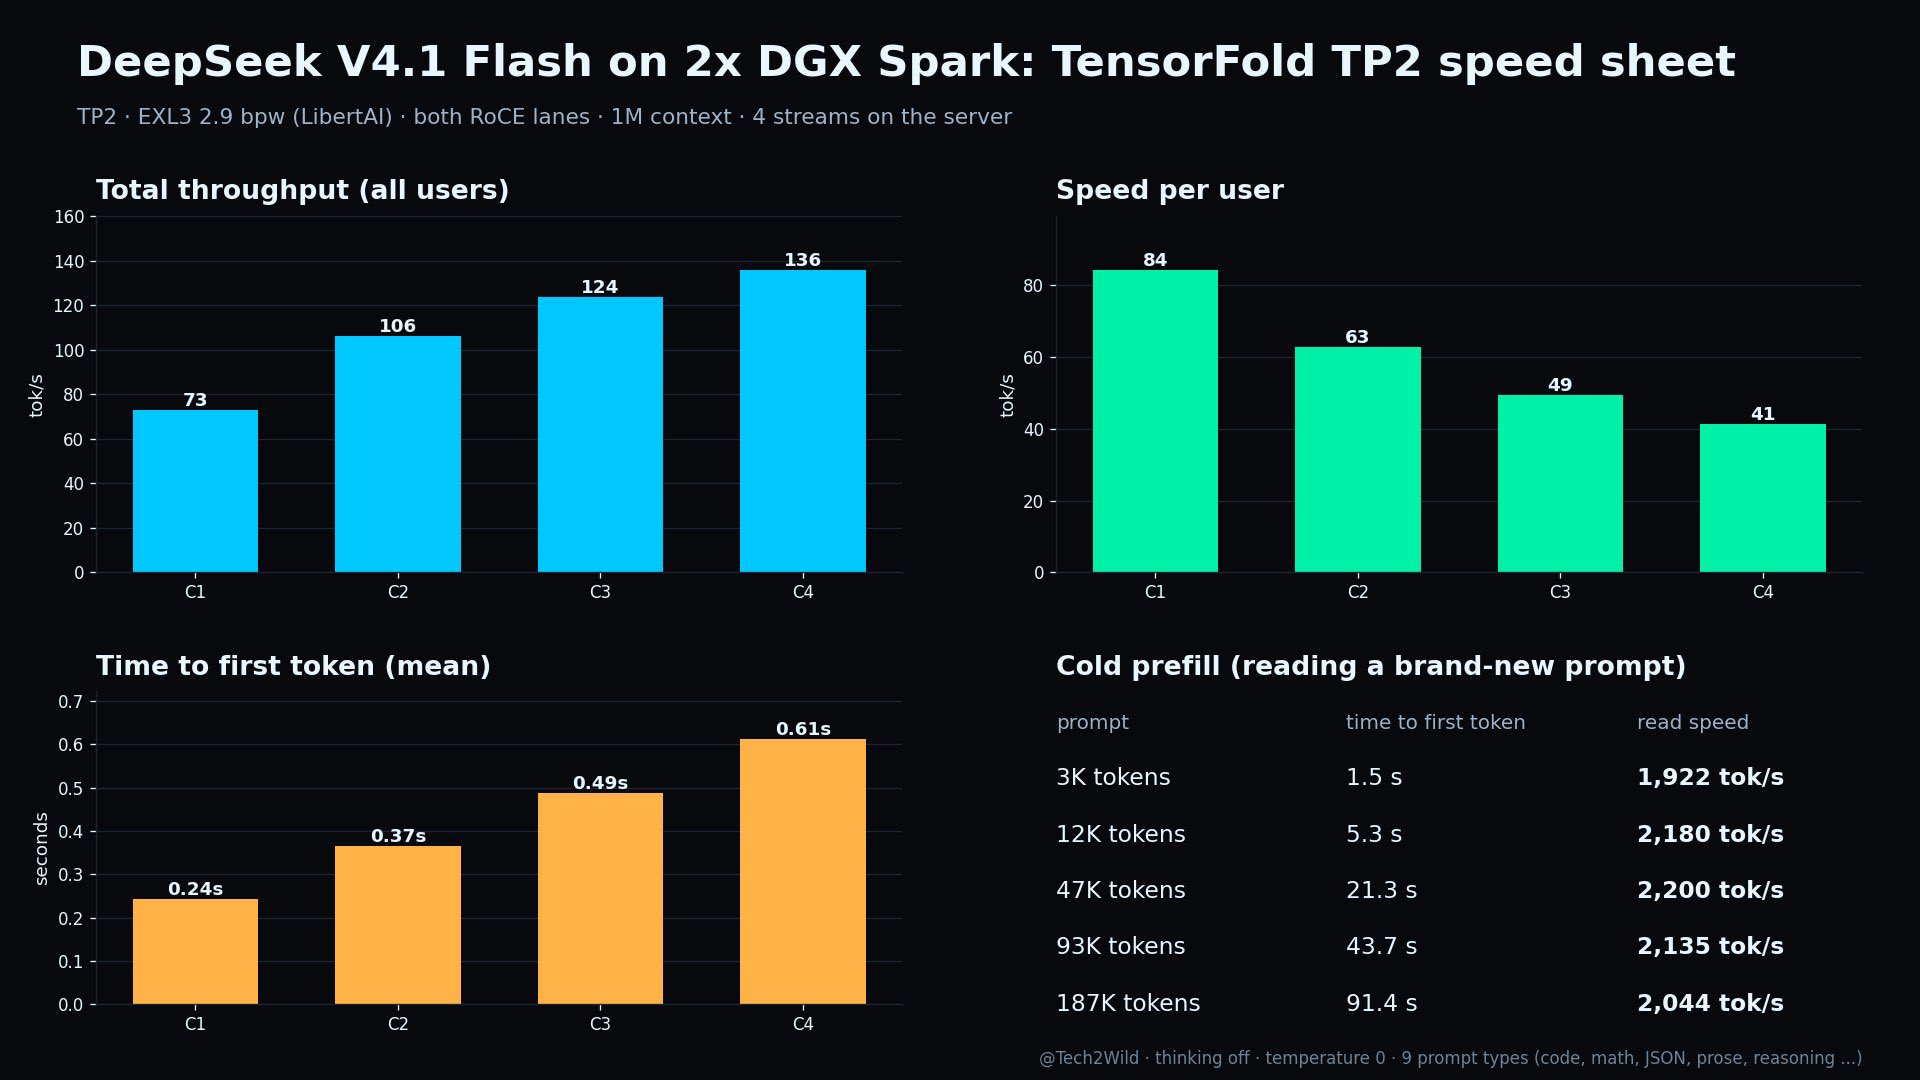
🚀 DeepSeek V4.1 Flash 1017 now runs on just 2x DGX Sparks 🔥 TensorFold's 2-node engine + LibertAI's EXL3 2.9 bpw pack: ⚡ 73 tok/s for 1 user, 136 tok/s total at 4 users 👤 84 tok/s per user solo 📥 93K-token prompt read in 43.7s (2,135 tok/s) 🧠 Full 1M context, loads in 27s 2 Sparks now beat our old 4-Spark vLLM setup (48.5 tok/s) 😤 Full recipe, scripts + every number 👇 http://github.com/tonyd2wild/DeepSeek-V4.1-Flash-vLLM-DGX-Spark Big thanks to bertholomus for the TP2 engine 🙏
This post quotes another post: “DeepSeek V4.1 Flash on 2× DGX Spark: 27s load, 2,059 tok/s on a 131K prompt”