Bespoke Labs open-sources Nimble, a 9B decision model benchmarked against Jev
Bespoke Labs built Nimble, a 9B scoring-based decision model, from Qwen3.5-9B with LoRA and 2,676 examples in one day; it scores 90.12% on a 324-example test, below Jev's 93.21%.
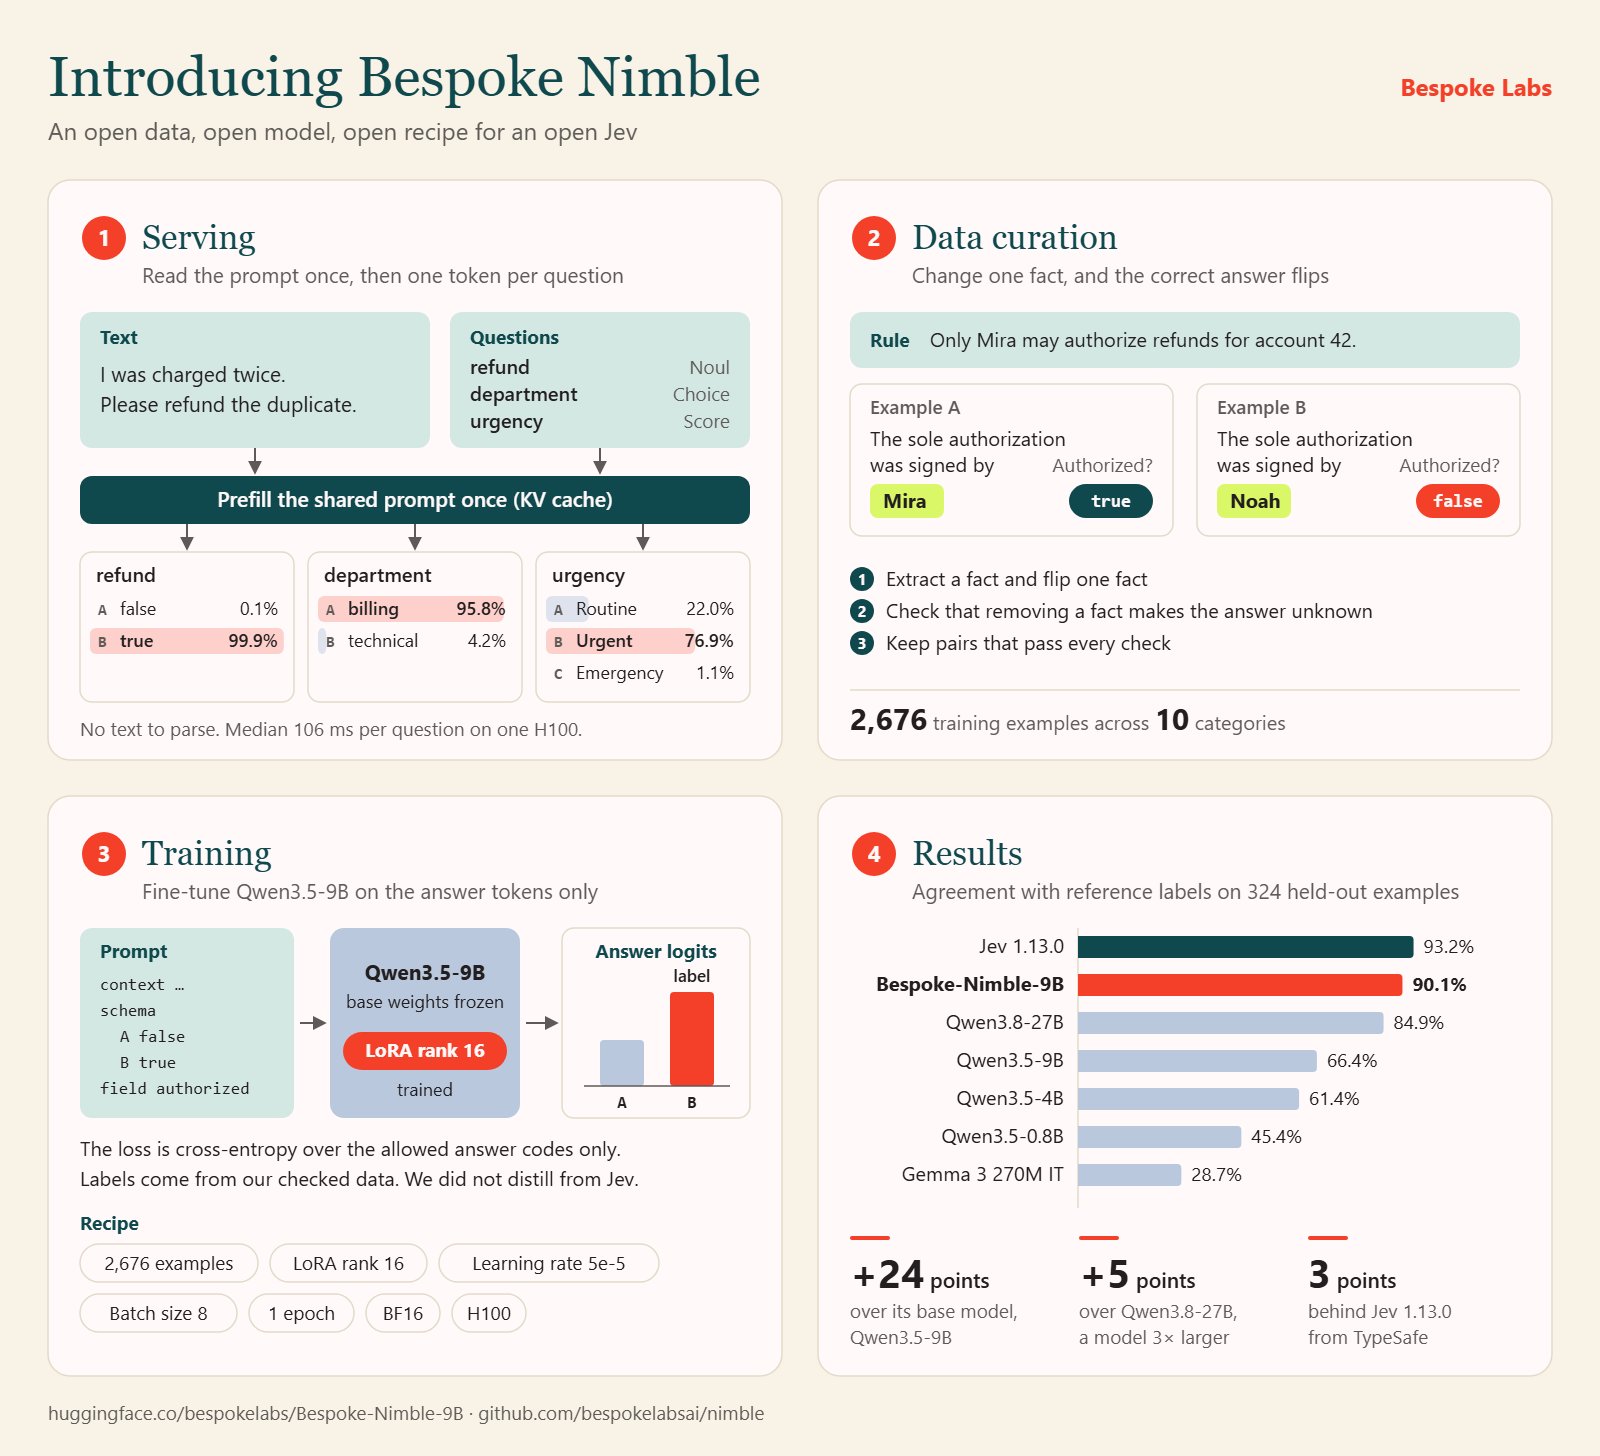
Okay, so specialized decision models are becoming the rage. Bespoke Labs just released Nimble, an open 9B decision model built from Qwen3.5-9B. And apparently they built it in ONE DAY. The recipe: 🧠 Qwen3.5-9B 🎯 LoRA fine-tune 📚 only 2,676 training examples ❌ no Jev distillation ❌ no RL ✅ open model ✅ open data ✅ open training recipe Instead of generating explanations or JSON, Nimble scores the allowed answers: YES / NO → A / B / C → route 1 / 2 / 3 → severity 1–5 Then returns the choice + probabilities. Example of Bespoke's 324-example held-out test: Qwen3.5-9B → 66.36% Qwen3.8-27B → 84.88% 🔥 Nimble-9B → 90.12% Jev → 93.21% And because it isn't generating a bunch of tokens: ⚡ ~106 ms median on H100 🍎 ~444 ms median on an M5 Pro 64GB 👈 👀 🎯 So this is the key, giant reasoning model doesn't need to answer every tiny agent decision. Let the big model think, then let a small local model handle the ... 🛠️ tool selection 🧭 routing ✅ verification 🚨 policy decisions 📊 scoring 🔄 retry / stop Fast. Local. No API call. ⚠️ Bespoke says this is a narrow synthetic 324-example evaluation, NOT a standardized System One benchmark. 🔗 GH: /bespokelabsai/nimble