Magnitude: an open-source inference engine over 2x faster than Ollama
Magnitude is an open-source inference engine that tunes kernels for your chip, running 2.19x faster decode on Mac M4 Pro and supporting Apple Silicon, NVIDIA, AMD and CPU with one-click agent connections.
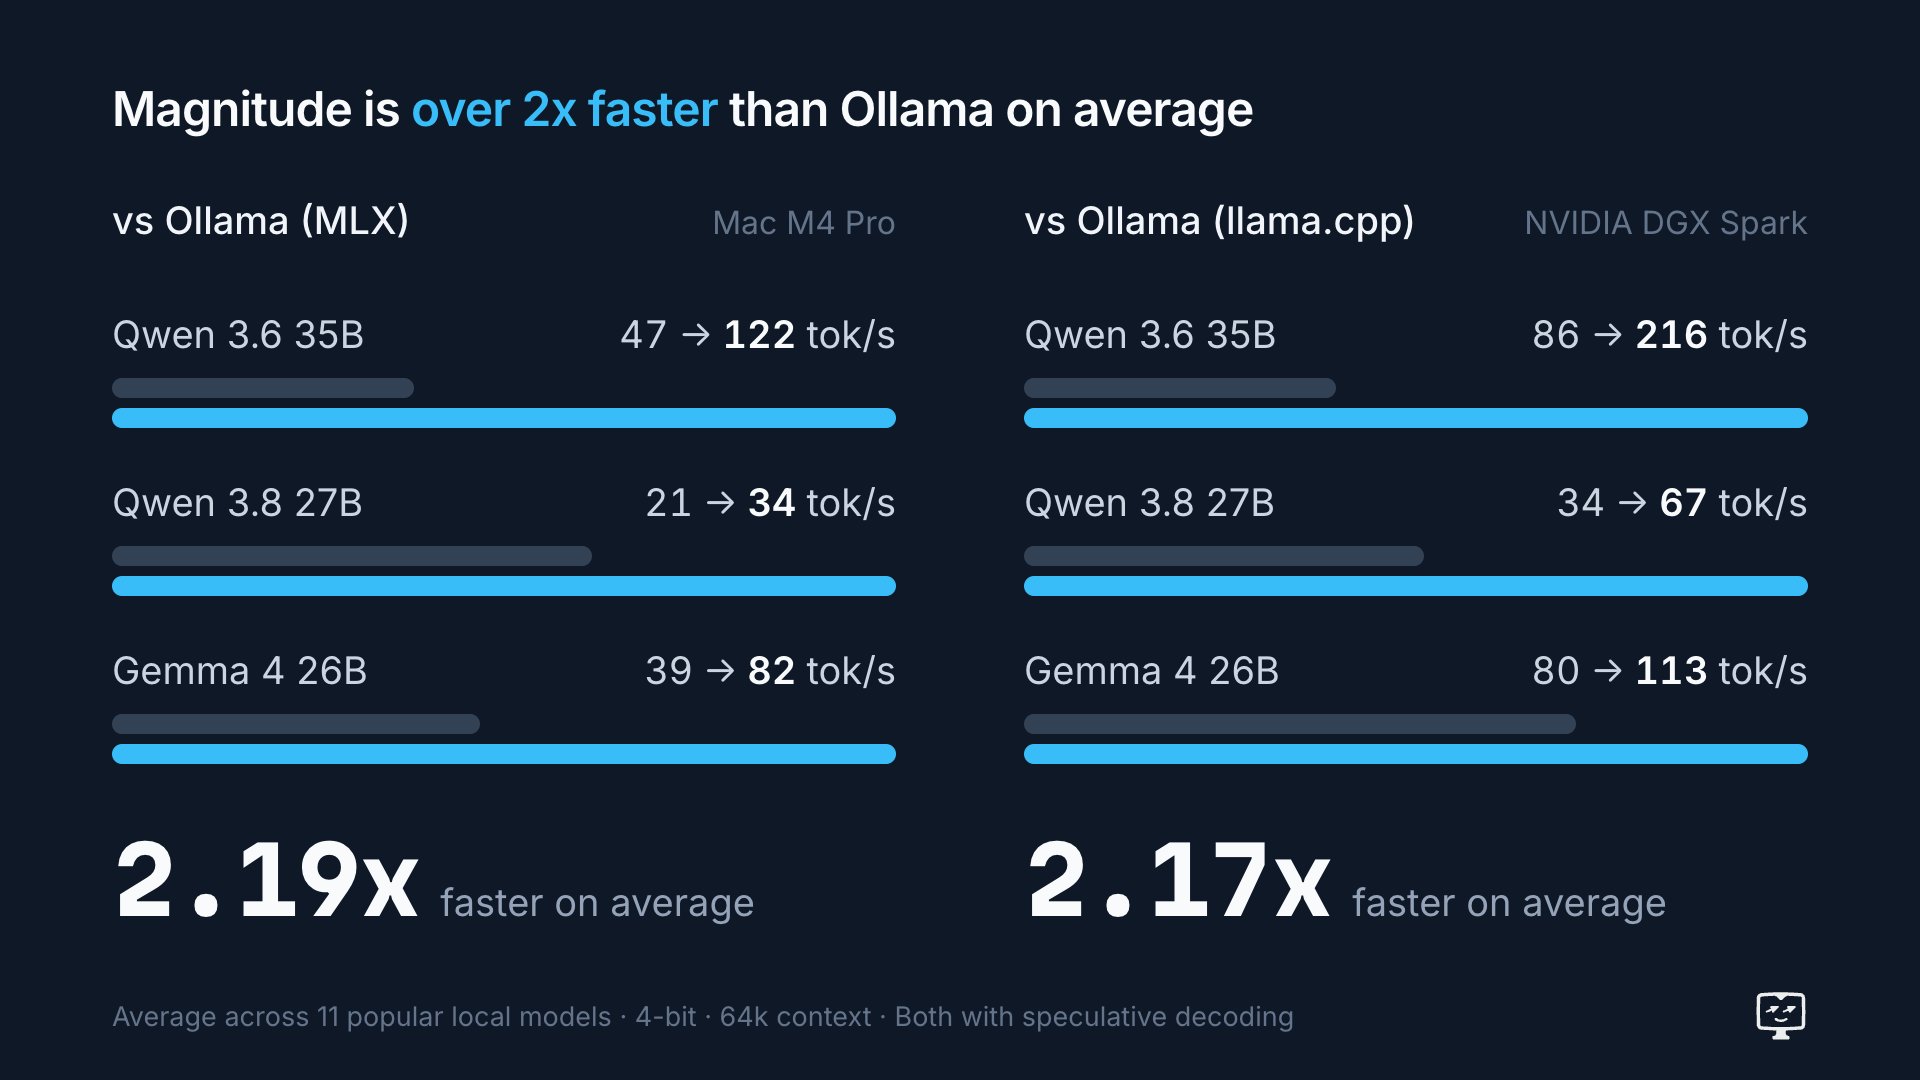
We made open models run over 2x faster than Ollama, without any new hardware Introducing Magnitude, an open source inference engine that runs open models as fast as your hardware allows. It tunes its kernels on your machine to find the fastest way to run each model Works on Apple Silicon, NVIDIA, AMD, or just a CPU On average across 11 popular local models: Mac M4 Pro vs Ollama (MLX) 1.32x faster prefill, 2.19x faster decode DGX Spark vs Ollama (llama.cpp) 1.34x faster prefill, 2.17x faster decode Ollama, LM Studio, and llama.cpp ship one-size-fits-all kernels, because tuning each model for each chip by hand would take forever Magnitude tunes them automatically. When you download a model, it spends up to a minute on your actual chip trying different ways to split up the math (how many GPU threads team up, how big a chunk each one takes, how far ahead to load data) and keeps the fastest combination that doesn't change the model's output Each model also comes paired with the best speculative decoding drafter, for even more speed One click connects Magnitude to the agent you already use (Pi, OpenCode, Hermes, Codex, and more). It's also built specifically for agents: • Each agent uses about half the memory, thanks to a quantized KV cache • Memory grows and shrinks with your sessions, so your computer stays usable • Agents share prefix caches, so several can run at once without slowing down Next, we're working on getting even more out of your hardware: • Expert streaming from RAM or disk, to run models bigger than your GPU allows • Splitting one model across all your GPUs and CPU so nothing sits idle • Attention pruning that skips low-impact math, for much faster prefill Ships as a desktop app on Mac, Windows, and Linux 100% free and open source Download → http://magnitude.dev/download GitHub → http://github.com/magnitudedev/magnitude