MiniCPM-OCR 1.0 ships with a Jev variant that scores each result 0–1
OpenBMB released the 1.3B MiniCPM-OCR 1.0 for documents, tables, formulas and charts, plus MiniCPM-OCR Jev, which scores every extraction from 0 to 1 so only questionable results need review.
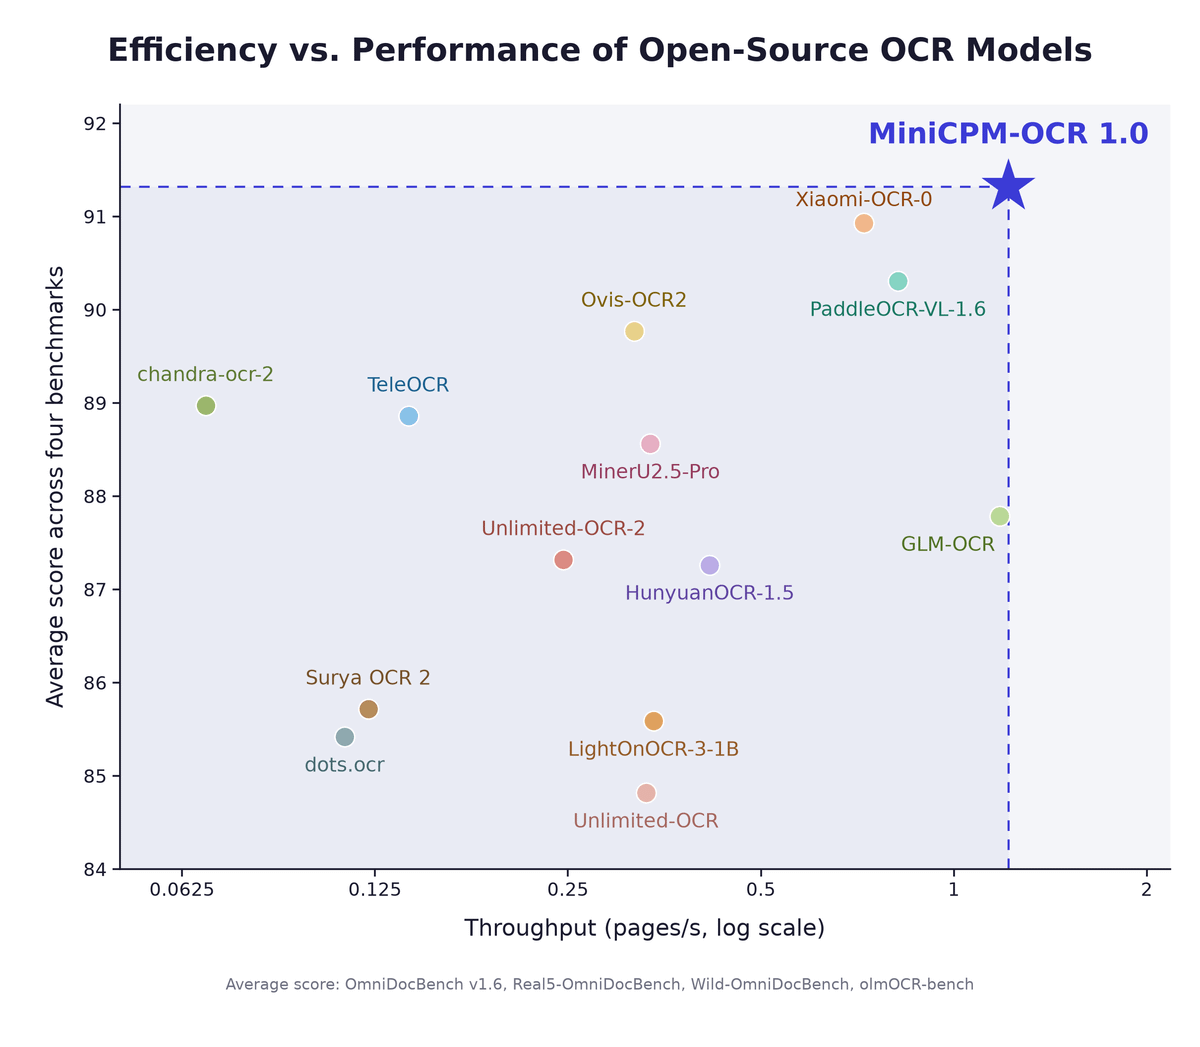
you can now pull clean text from a messy phone photo of any document with a 1.3B model OpenBMB just dropped MiniCPM-OCR 1.0, a small open model that reads documents, tables, formulas and charts: > it tops the average score across four document benchmarks, including 93.68 on Real5-OmniDocBench > and it's the fastest on the chart: about 1.49× the throughput of PaddleOCR-VL-1.6 and 3.62× of MinerU2.5 Pro > MiniCPM-OCR Jev scores every result from 0 to 1, so you only check the parts that look off tiny models are getting scary good Hugging Face: MiniCPM-OCR 1.0: https://huggingface.co/openbmb/MiniCPM-OCR-1.0 MiniCPM-OCR Jev: https://huggingface.co/openbmb/MiniCPM-OCR-Jev GitHub: https://github.com/OpenBMB/MiniCPM-OCR @OpenBMB
This post quotes another post: “MiniCPM-OCR suite: 1B parser plus 2B Jev checker”