jevIMAGE
jev-use replaces coordinate clicks with a list of screen regions
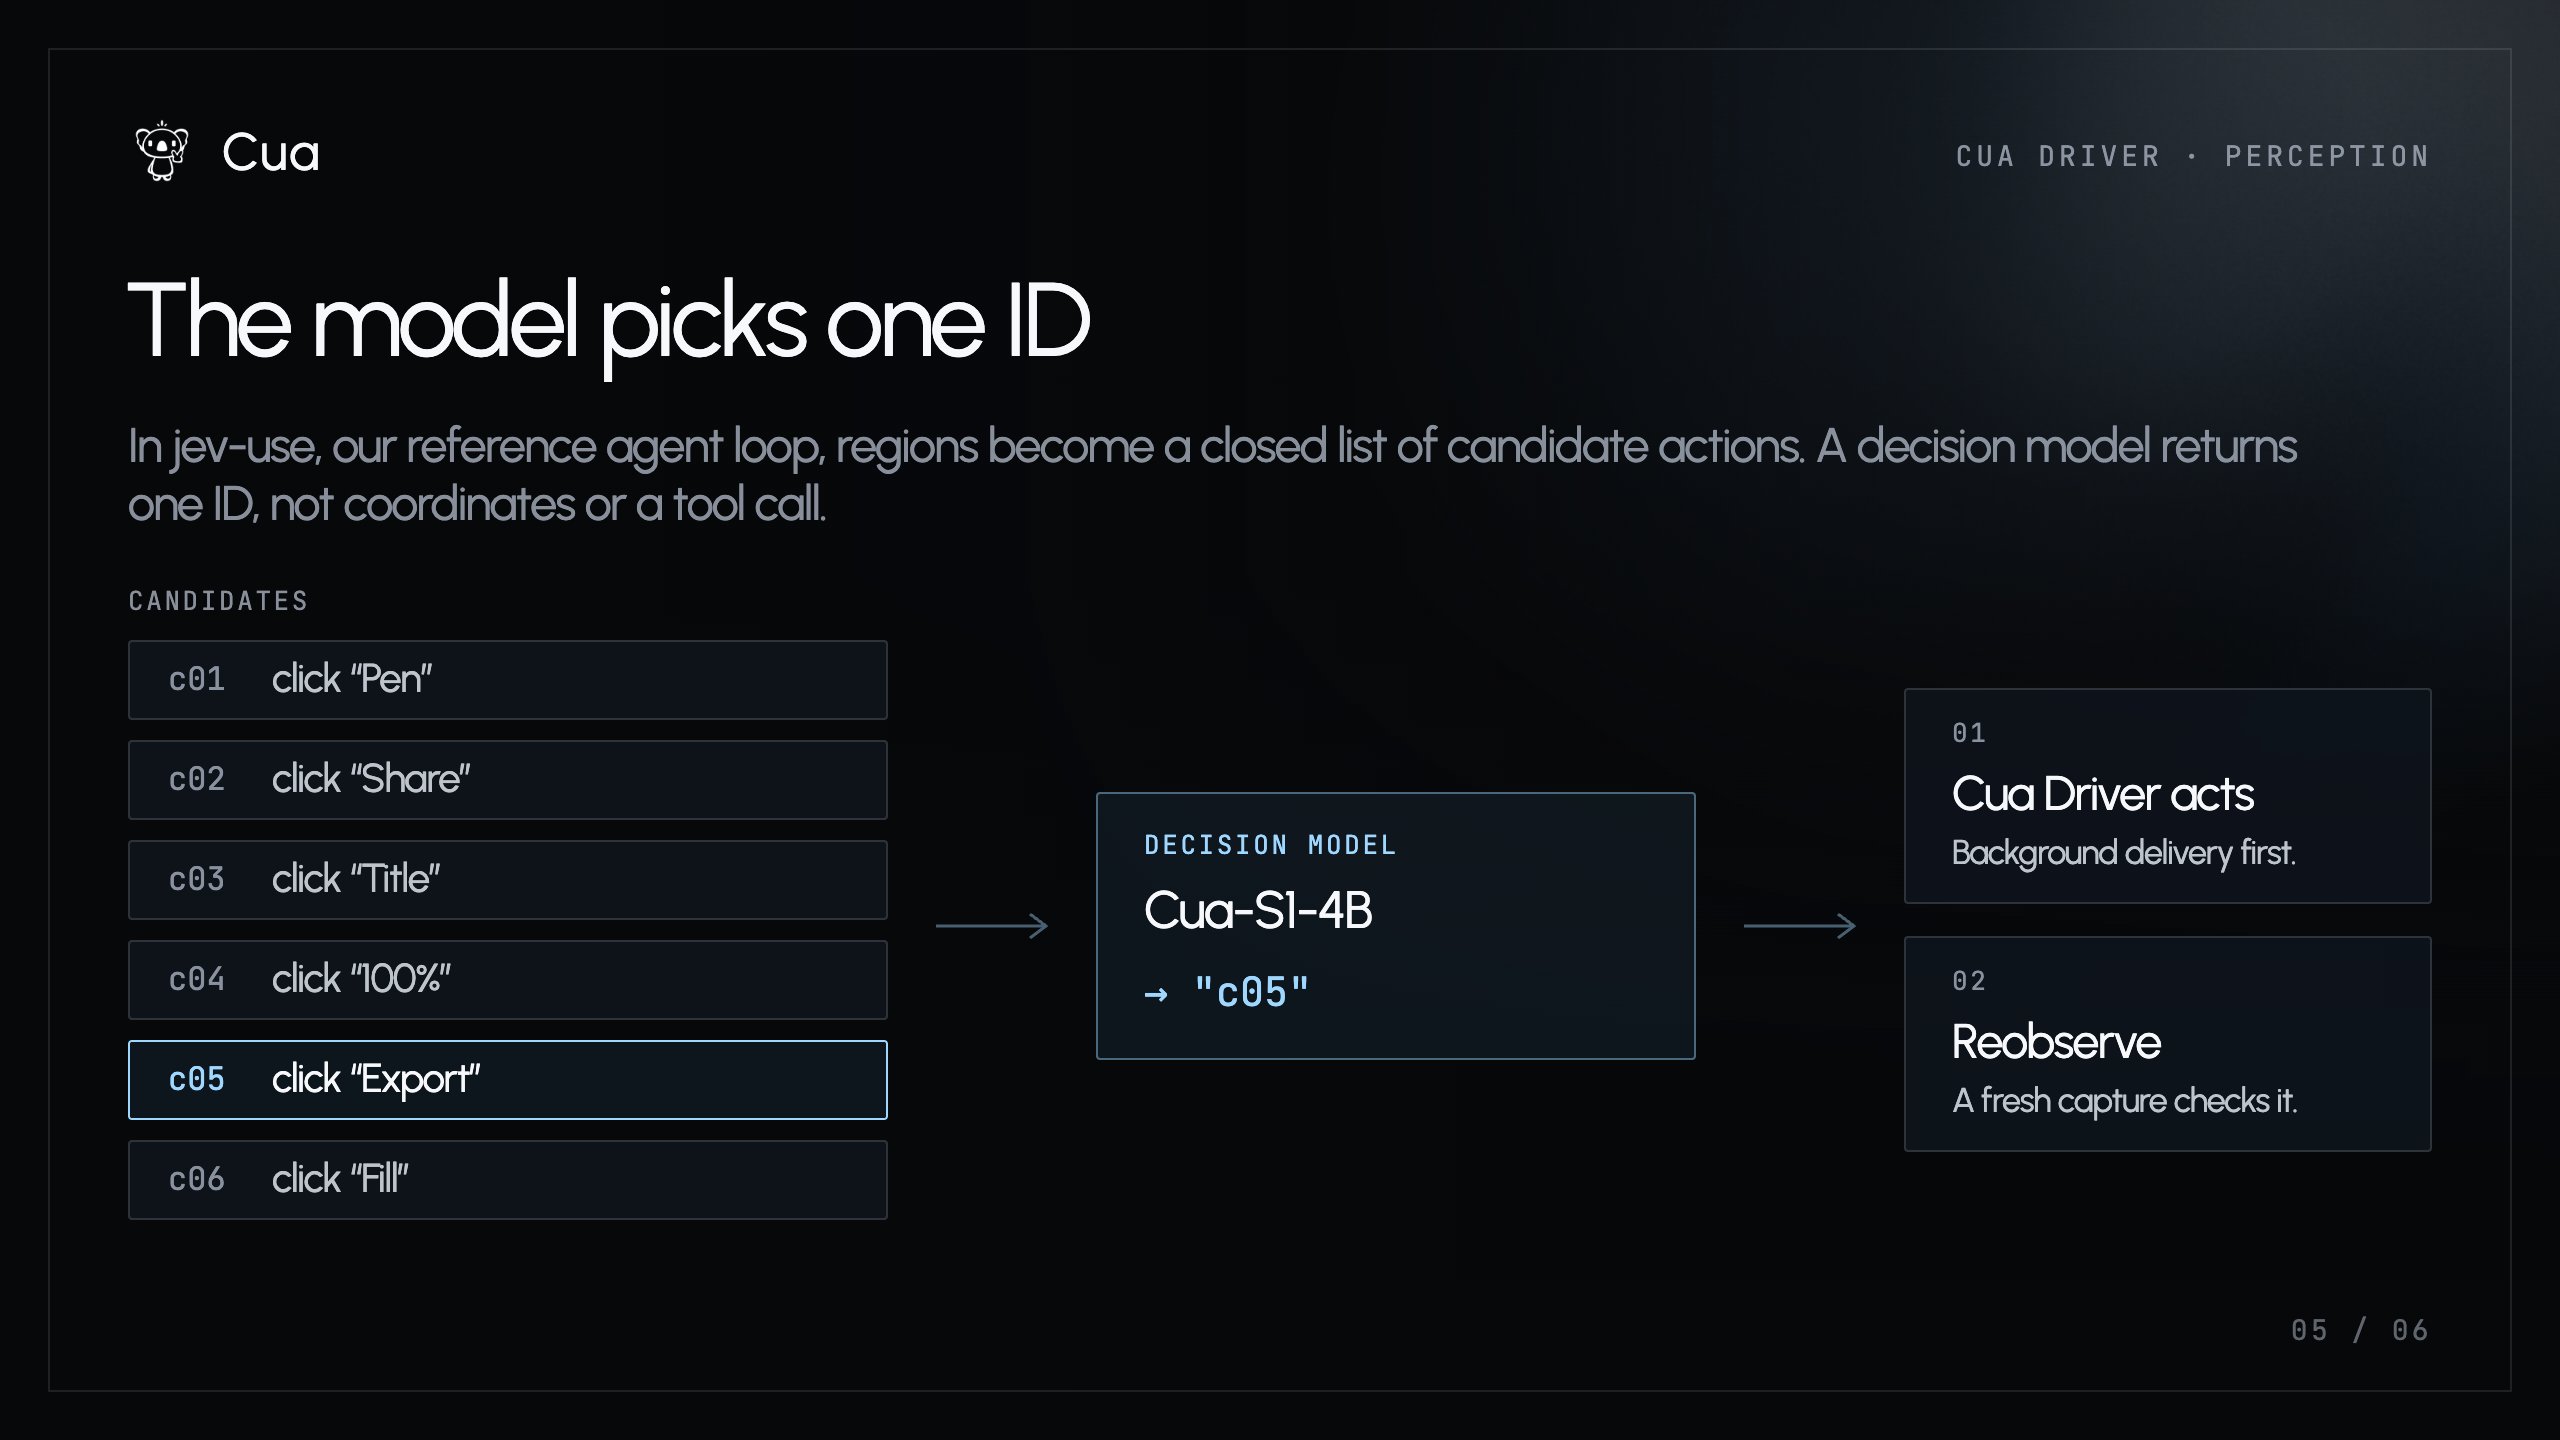
Cua's reference agent loop jev-use divides the screen into regions so the decision model only picks an ID, letting text-only models operate interfaces.
Cua
@trycuaArchived 2026.09.29Originally posted 2026.09.28
Cua @trycuaOriginally posted 2026.09.28
5/ In jev-use, our reference agent loop, regions become a closed list of candidate actions. A decision model such as Cua-S1-4B picks one ID, not coordinates. Real-time and text-only models were never trained to point at pixels. With regions, they can still act on the screen.
x.com/trycua/status/2104592035919376498Archived 2026.09.29 10:03