jevIMAGE
Typesafe shares Jev results on repeat-question matching and other tasks
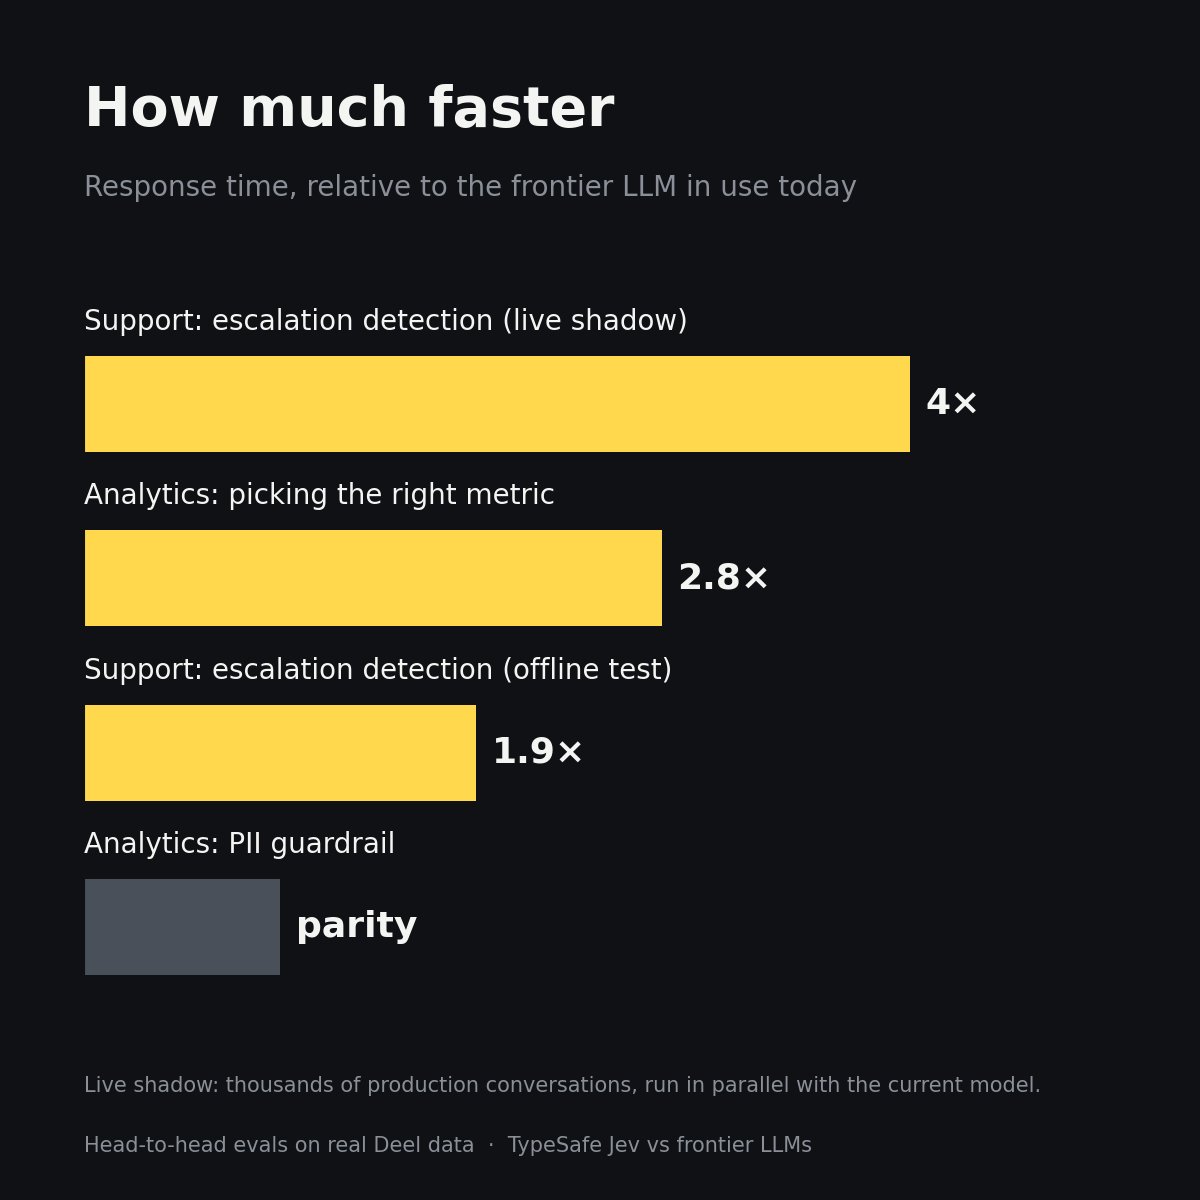
Typesafe says Jev outperformed frontier LLMs at a fraction of the price, with repeat-question matching rising from 70% to 97%, expense categorization from 50% to 86%, and fewer false alarms on escalations.
TypeSafe AI
@typesafeaiArchived 2026.09.26Originally posted 2026.09.25
TypeSafe AI @typesafeaiOriginally posted 2026.09.25
Jev generally out-performed frontier LLMs at a fraction of the price: Repeat-question matching: 70% → 97% Expense categorization: 50% → 86% (vs human reviewers) Escalation: same catches, fewer false alarms
x.com/typesafeai/status/2103321894661595551Archived 2026.09.26 10:13