Argon vs GPT-6 Astra: better at labeling, weaker at next-action prediction
The author says OpenAI's Astra beats Gemini 4 Argon on a next-action prediction benchmark, while Argon crushes Astra on long-horizon understanding and labeling.
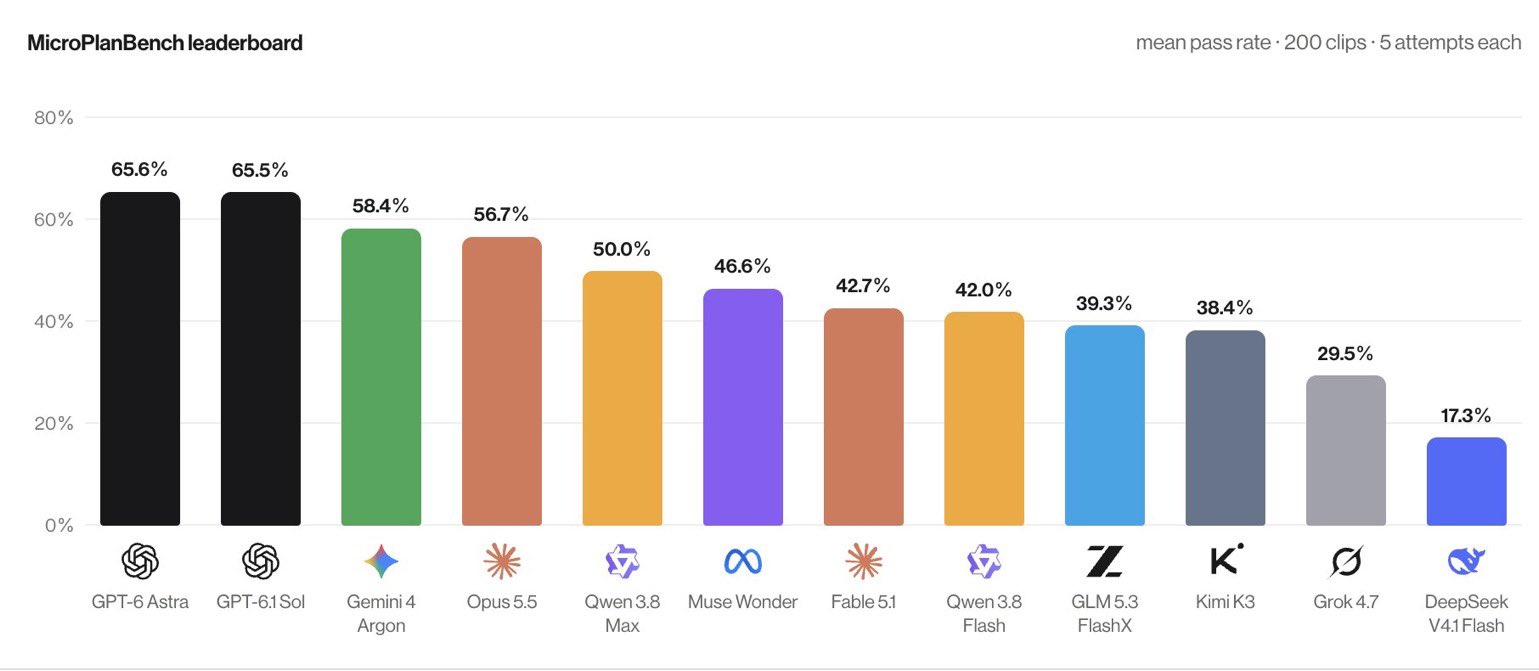
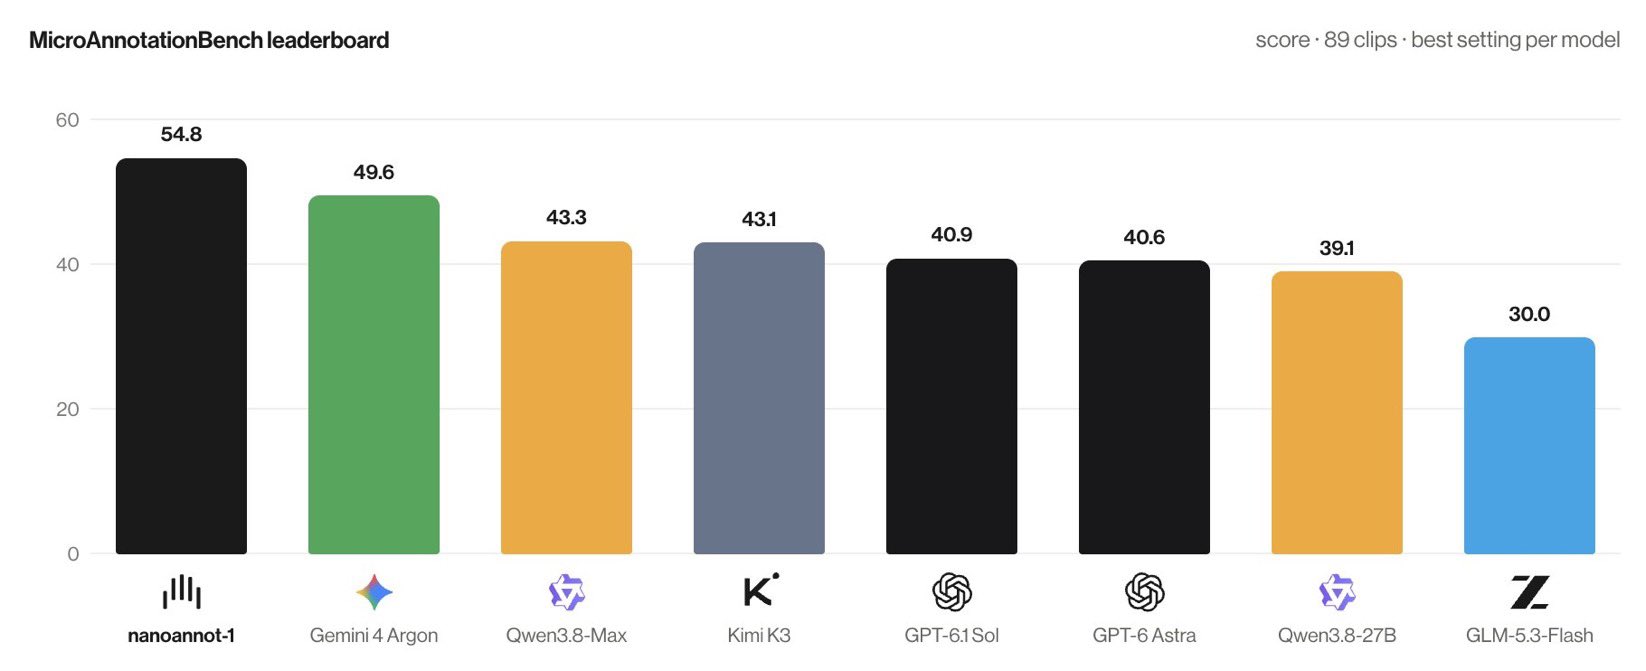
Foundational Models and Annotation Models are different. Former makes the robot work and the latter understands the data to feed into the formers training. Among frontier lab models. @OpenAI’s Astra is the superior foundational model beating @GeminiApp Argon on the next-action prediction benchmark (the foundational model benchmark) But Argon destroys Astra on truly understanding and labeling across a long horizon. Hence comparatively is a better annotation model. The takeaway here is that there isn’t just one generalizable omni-model that wins both on prediction and labeling, use cases are differentiated. Safe to say @microagi nanoannot ended up leading MicroAnnotationBench
This post quotes another post: “New benchmarks: nanoannot-1 beats Gemini 4 Argon at 1/10 cost”