vLLM: DeepSeek V4.1 Flash hits 1.3B tokens per dollar on AgentX
vLLM reports DeepSeek-V4.1-Flash serving 830K tok/s per GPU and 1.3B tokens per dollar TCO on SemiAnalysis AgentX, with 5x agentic throughput since day one.
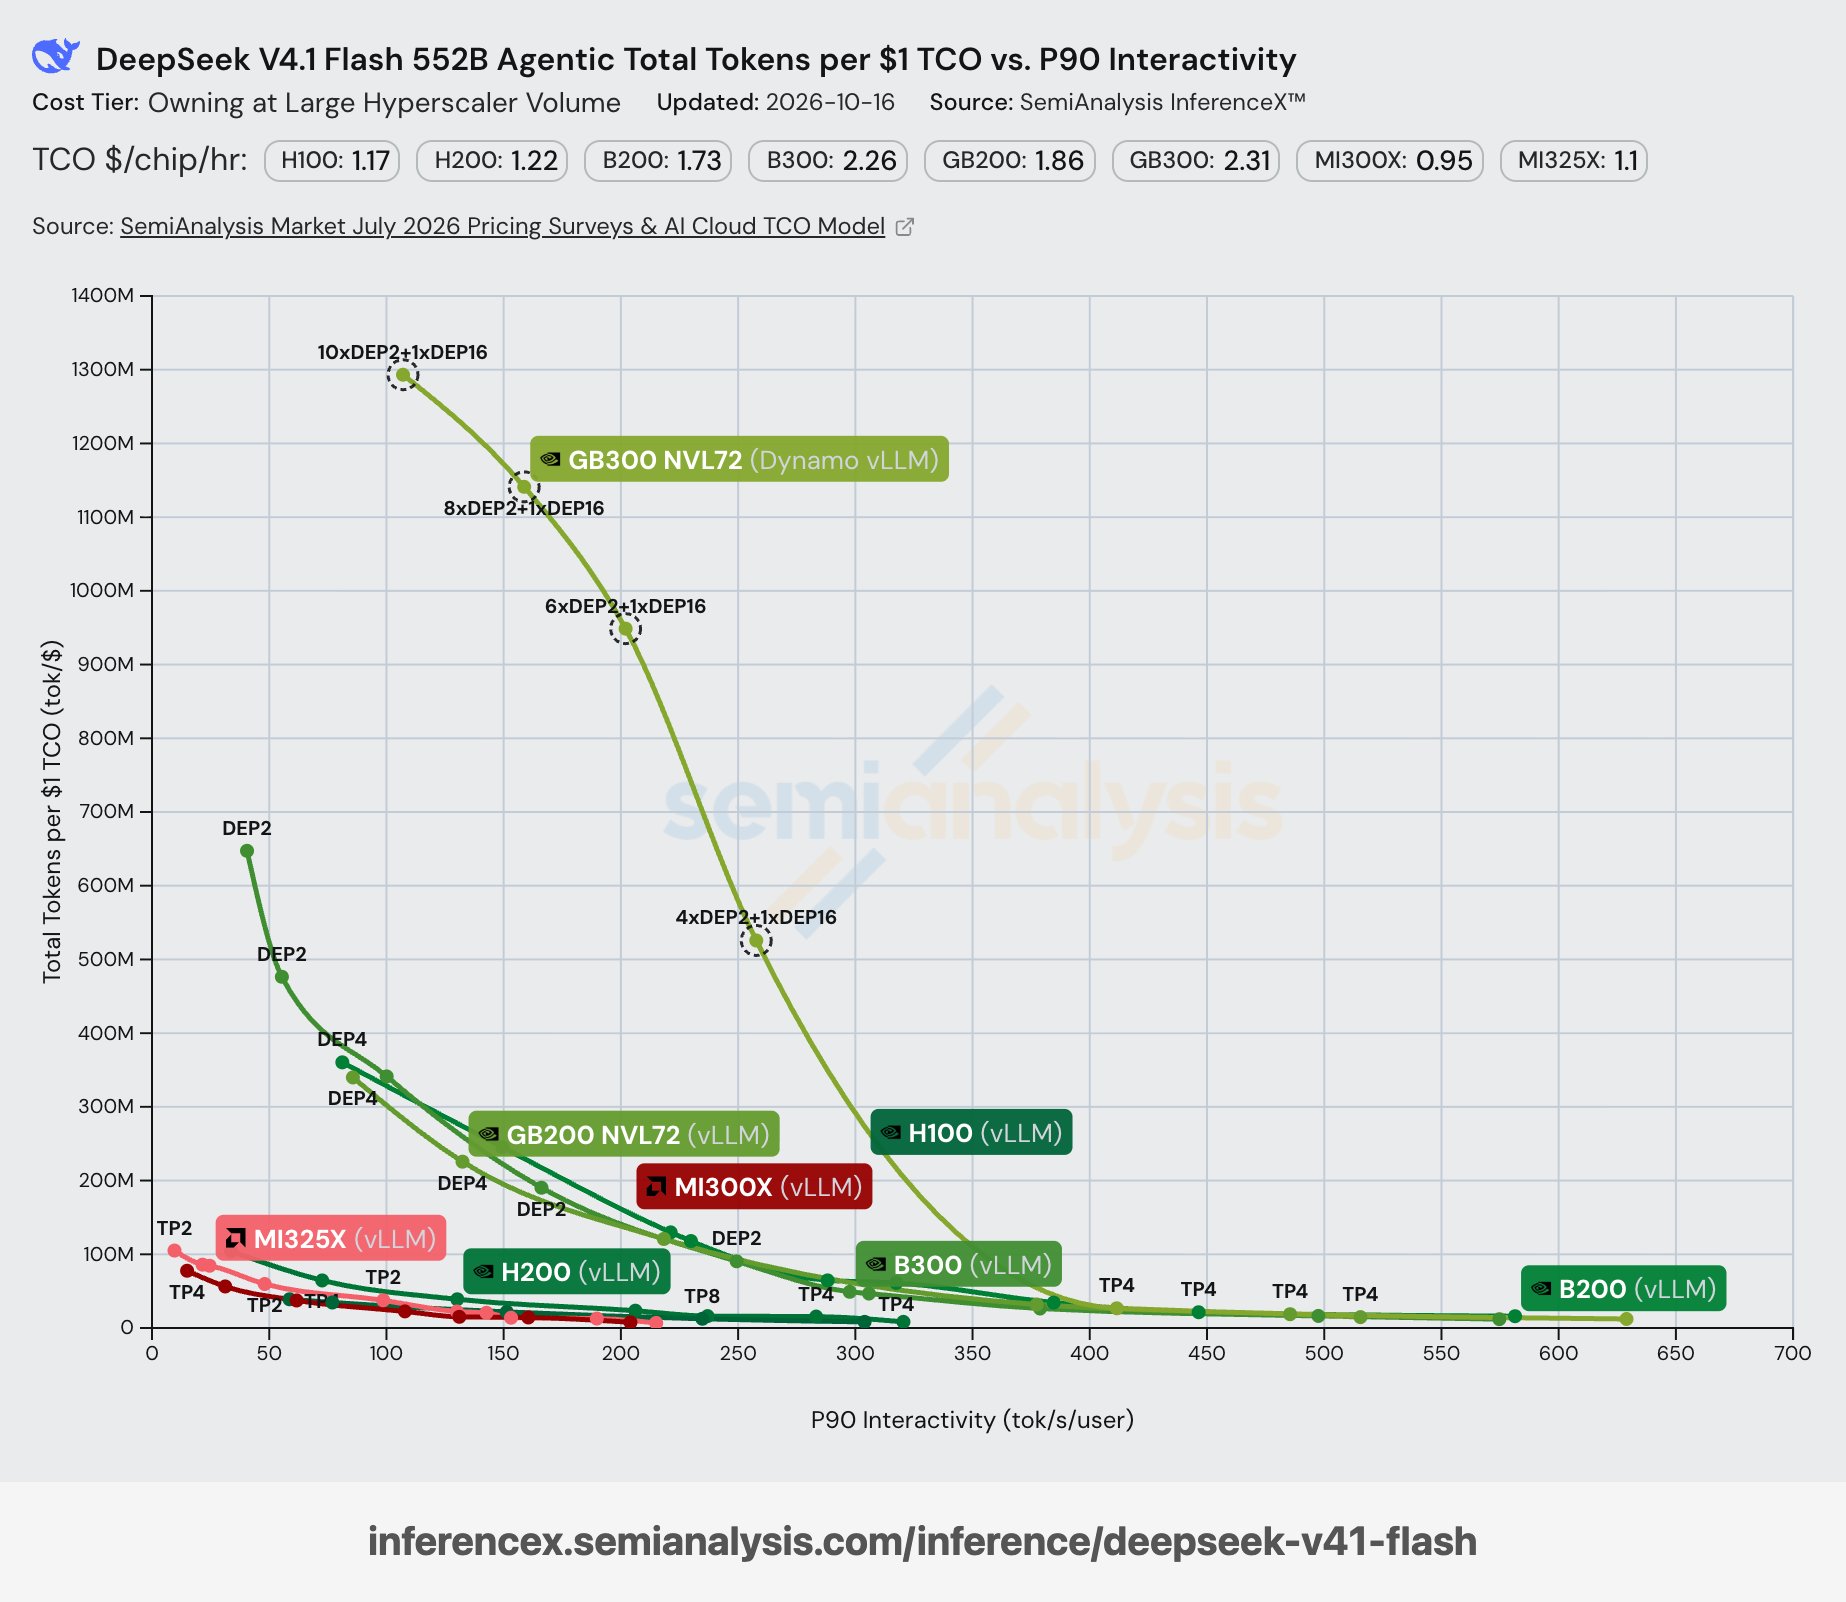
🎉 Congrats @deepseek_ai on DeepSeek-V4.1-Flash-1017! Better scores and shorter outputs make it a great fit for long agent loops. Making each step fast is the serving side's job. On DeepSeek-V4.1-Flash, vLLM delivers 1.3B tokens per dollar TCO on SemiAnalysis AgentX: 830K tok/s per GPU (cached + input + output) at 100 tok/s per user. 🚀 It's been a fun few weeks building with the community. Chapter one, 5x agentic throughput since day 0: 🔗 https://vllm.ai/blog/2026-10-07-deepseek-v41-flash Next chapter coming soon. 👀
This post quotes another post: x.com/deepseek_ai/status/2111375640717033777