vLLM serves DeepSeek V4.1 Flash on GB300 NVL72 at 954K tokens/s per GPU
Using P/D disaggregation and Wide-EP on a GB300 NVL72 rack, vLLM serves V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU with 196 tokens/s P90 per user, 7.9x its single-node result.
Scaled out with P/D disaggregation and Wide-EP on a GB300 NVL72 rack, vLLM serves V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU with 196 tokens/s P90 per user, 7.9× our single-node result. Our engineering blog covers the work behind it: https://vllm.ai/blog/2026-10-23-deepseek-v41-flash-pd-wide-ep
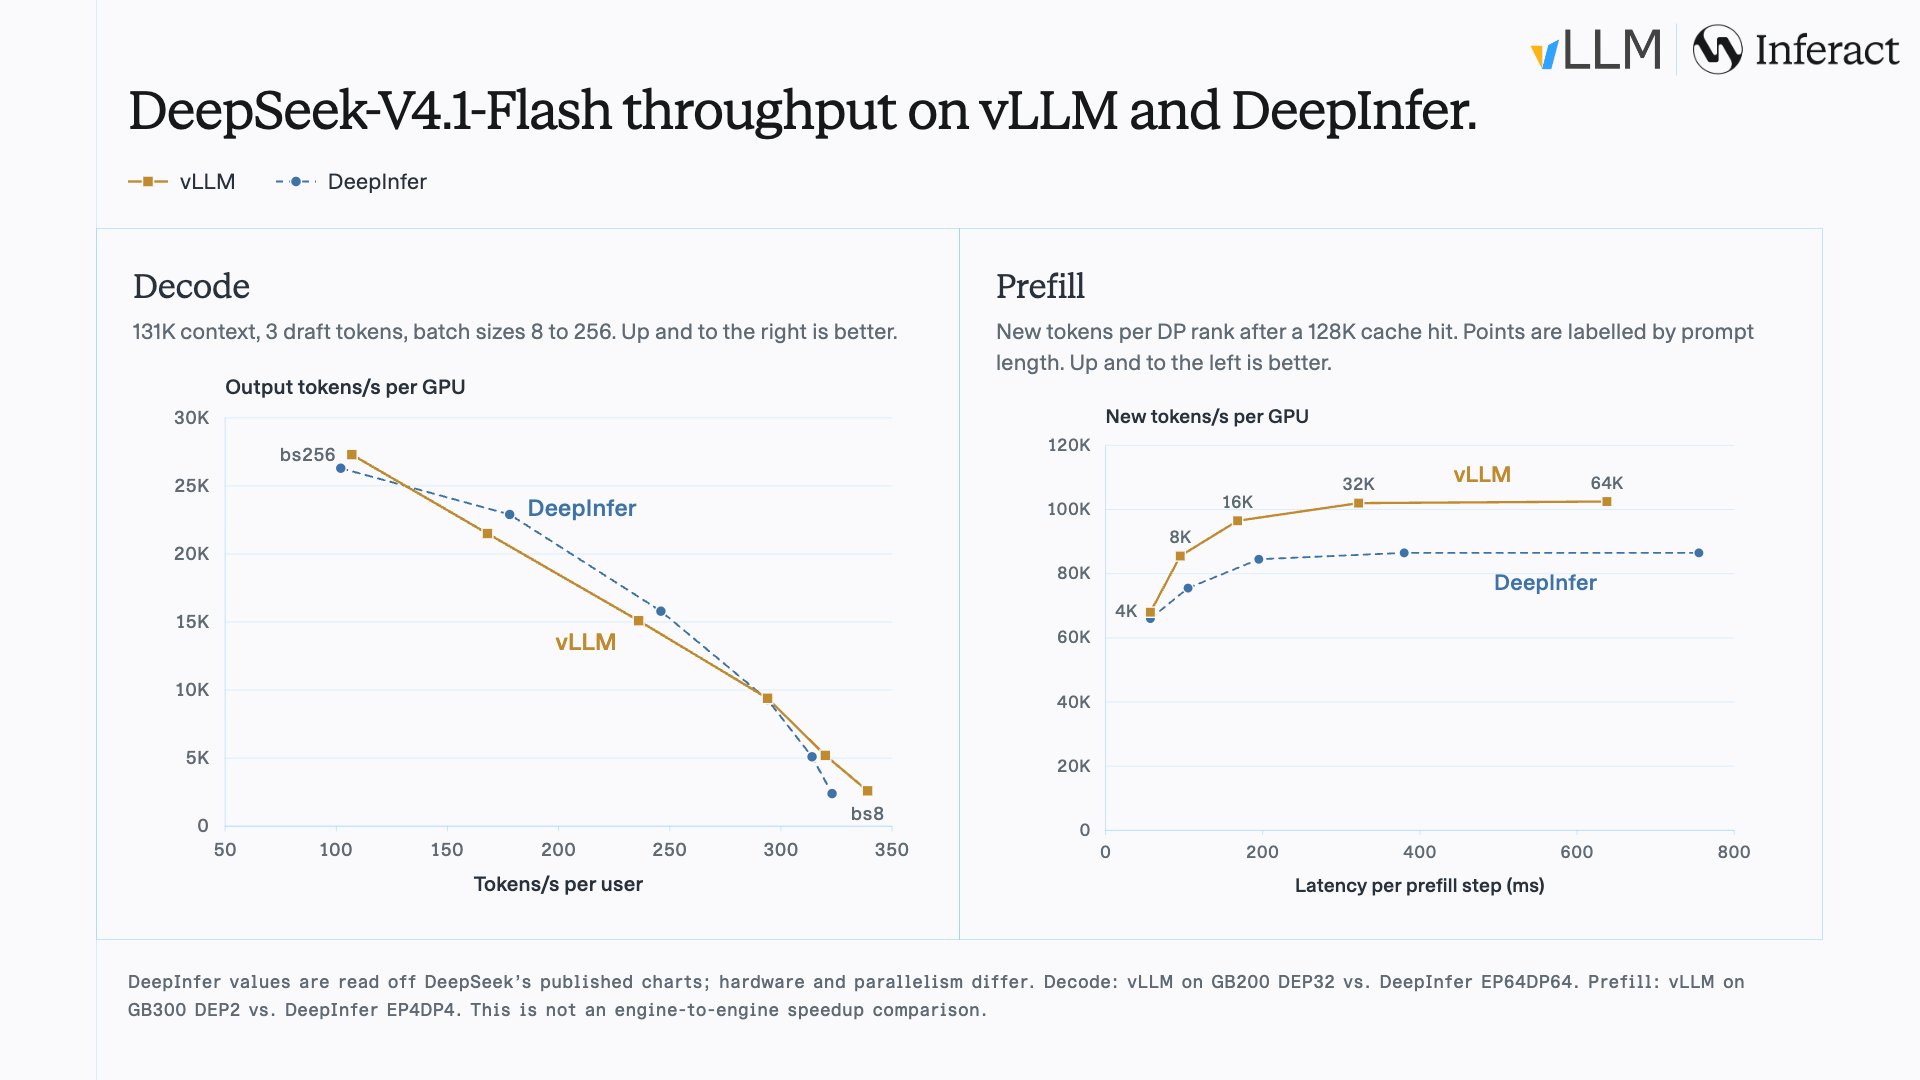
vLLM matches DeepInfer, DeepSeek's own engine for DeepSeek-V4.1-Flash, on DeepSeek's decode configuration across batch sizes 8 to 256, and does it at DEP32 against DeepInfer’s EP64DP64. DeepInfer was originally built on vLLM. By integrating DeepSeek's open-source kernels and extensively optimizing prefill and decode, vLLM now matches DeepInfer's performance curves.