gemini-4IMAGE
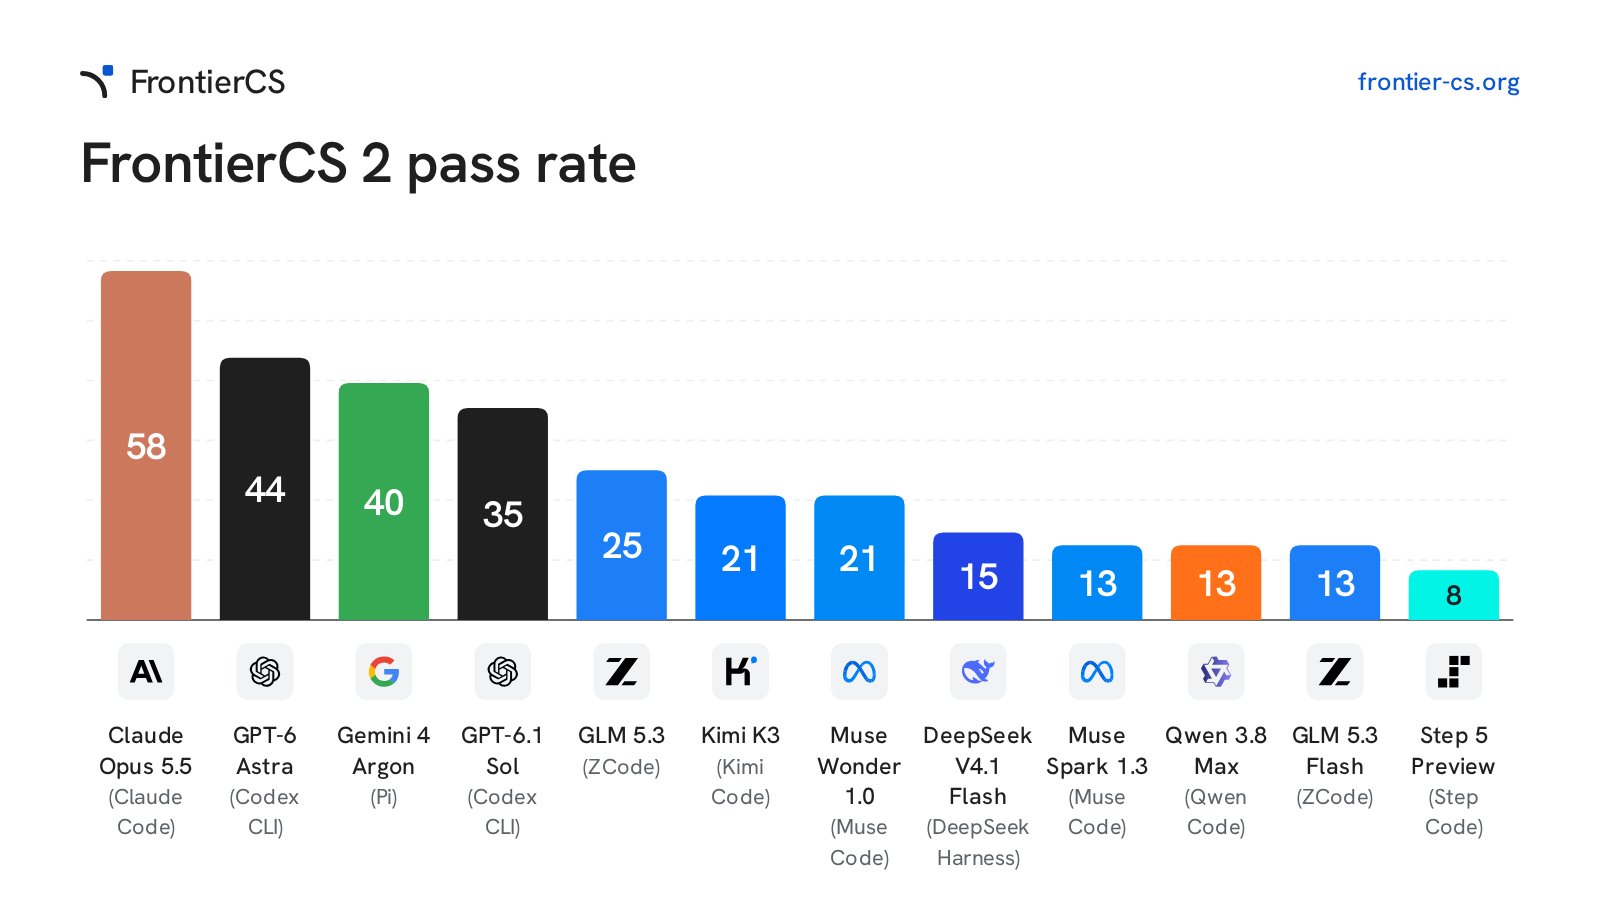
FrontierCS 2: Gemini 4 Argon hits 40% vs Opus 5.5's 58%
On the new FrontierCS 2 benchmark, where agents fix real CS research code without seeing the paper, Opus 5.5 passes 58%, GPT-6 Astra 44% and Gemini 4 Argon 40%, with Argon nearly catching Opus under a different harness.
vorpal
@vorpal_onchainArchived 4 days agoOriginally posted 2026.10.26
vorpal @vorpal_onchainOriginally posted 2026.10.26
Opus 5.5 is still the best researcher on earth the new FrontierCS 2 benchmark makes agents beat real CS research code without seeing the paper Opus 5.5 leads the new FrontierCS 2 benchmark Opus 5.5 passed 58% of runs. no other agent reached 50%, Astra 44% and Gemini 4 Argon 40% swap Argon into Antigravity and it almost catches Opus the harness matters as much as the model Terra has a lot to prove this week is your harness holding your model back?
x.com/vorpal_onchain/status/2114634678359457938Archived 2026.10.27 09:52