Kapa benchmark: Jev nearly tops reranking despite not being built for it
Voyage cites Kapa's test on 1,000 production queries where Jev, used as a reranker, came within a hair of first place on retrieval quality.
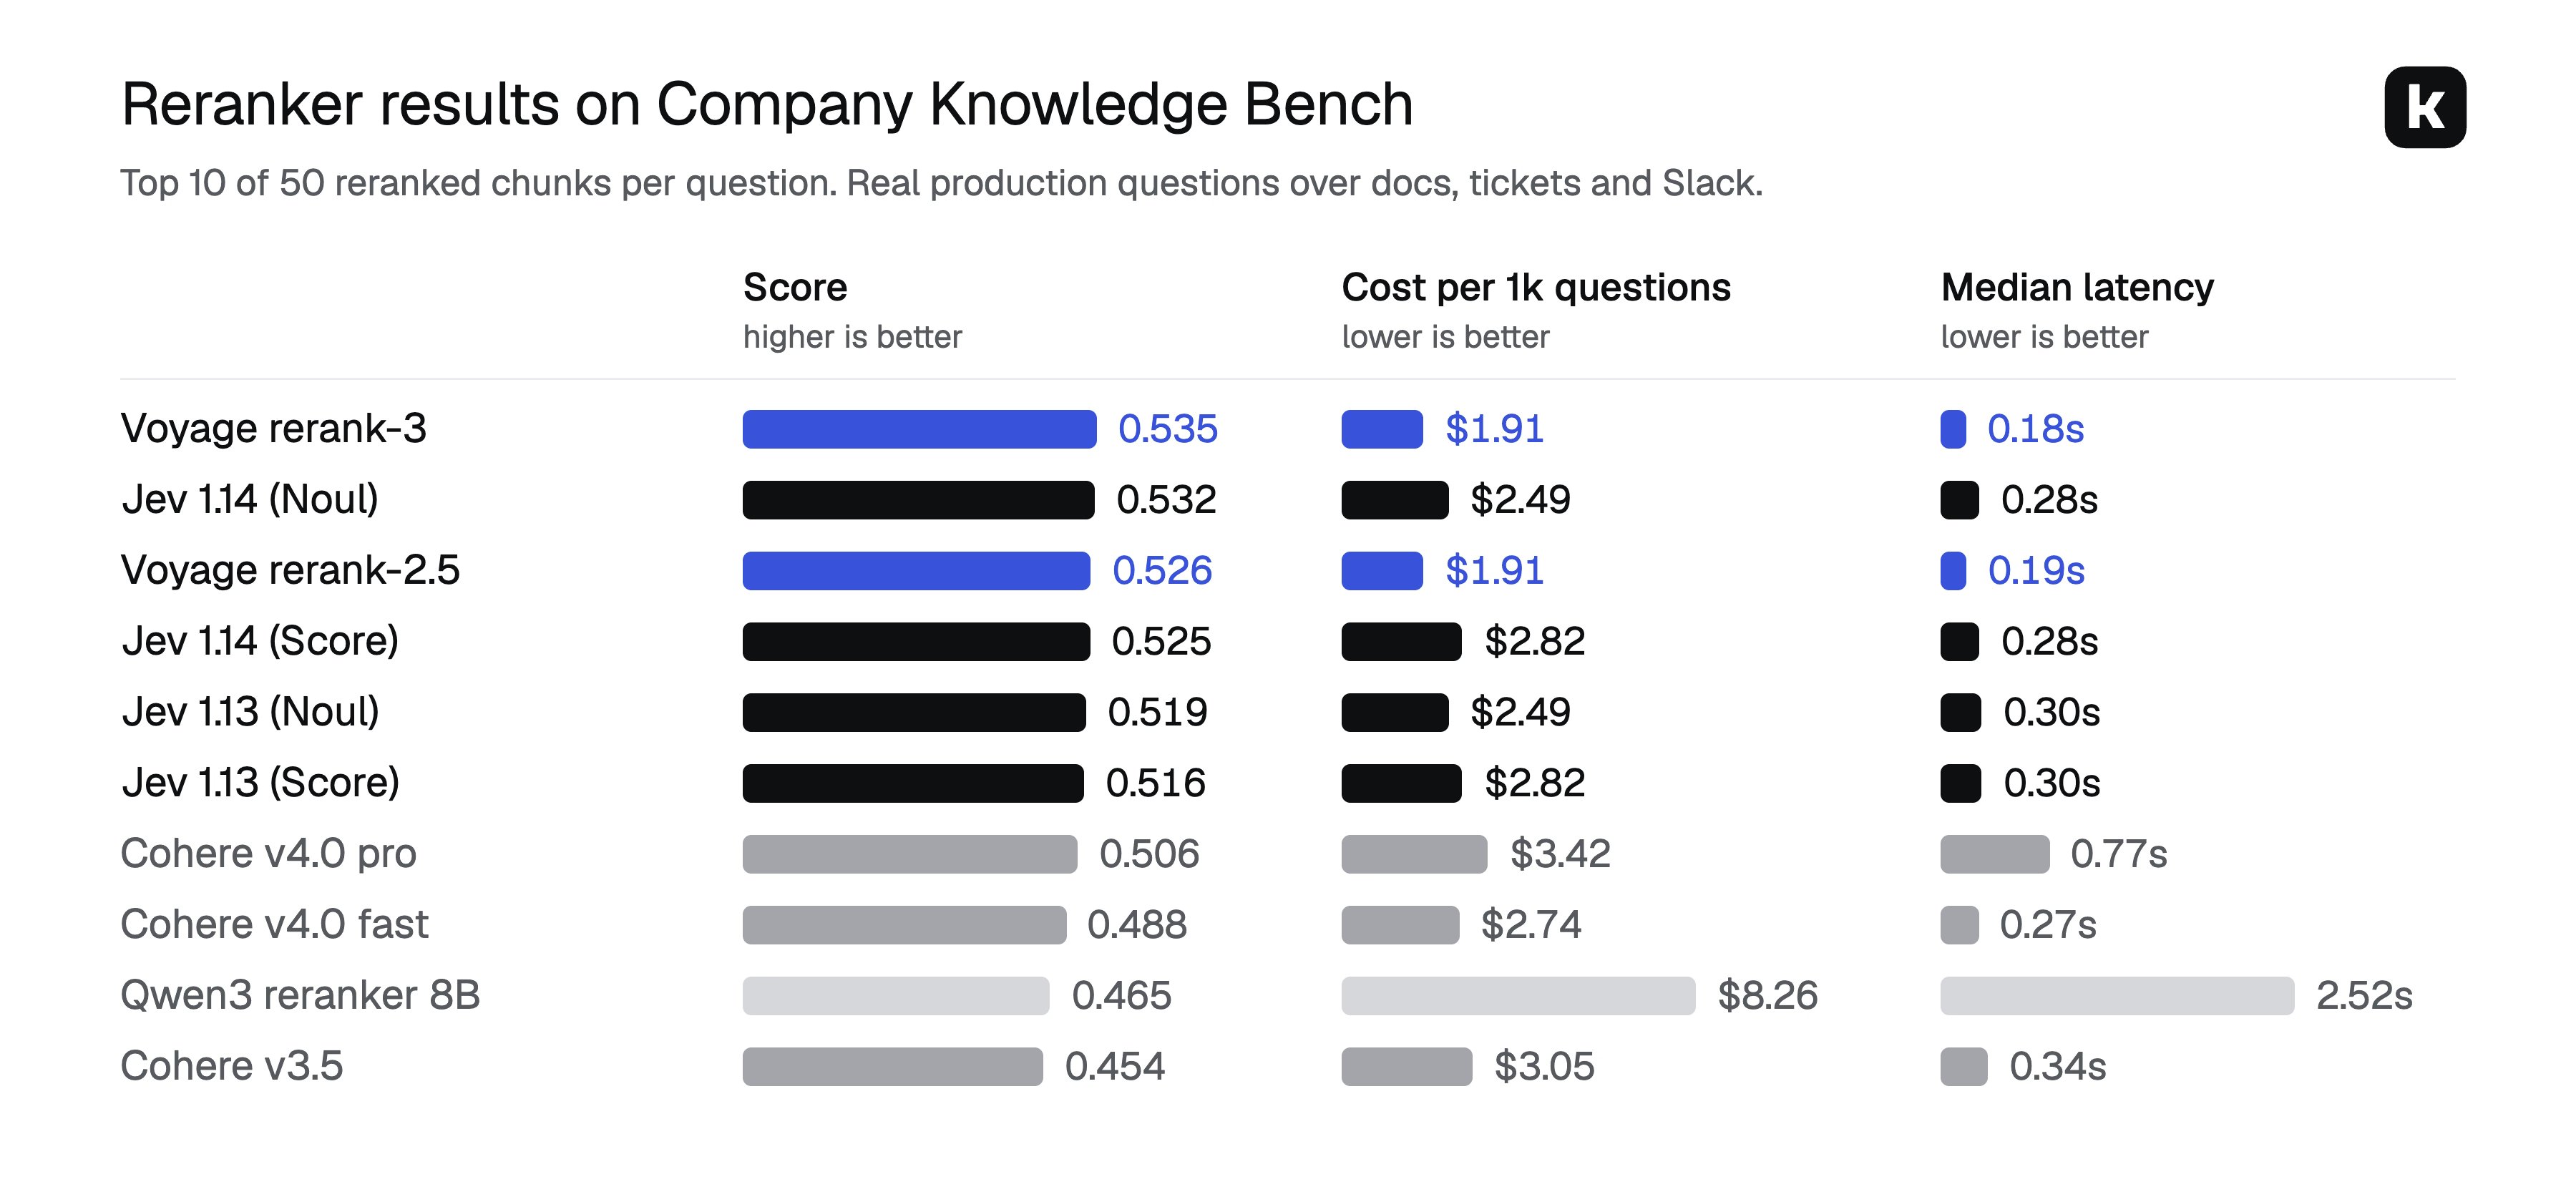
“Voyage wins on score, cost, and latency.” Don’t believe us? Check out the latest benchmark from @kapa_ai. Frontier models keep getting better, but they aren’t the whole stack. Agentic systems constantly make smaller decisions: what to retrieve, where to route a query, and which results matter. Specialized models are often better suited to that work. Jev, @typesafeai’s general-purpose decision model, is a great example. Give it context, a question, and a set of labels, and it returns a probability for each label, allowing you to steer it with a rubric for routing, labeling, or ranking. @kapa_ai tested Jev as a reranker on 1,000 real-world evaluation cases built from production queries over company knowledge bases, including product docs, Slack threads, support tickets, wikis, and code. Jev wasn’t built for reranking, yet it came within a hair of first place on retrieval quality, while also beating several dedicated rerankers. Which model finished first? The rerank-3 model from Voyage AI by MongoDB topped the benchmark for retrieval quality while also being the cheapest and fastest model that Kapa measured. Read the post for the full setup and results: https://mongodb.social/6016BHno7j