Jev's second-order effects: data as the bottleneck and real-time trace monitoring
The author lists three points after Jev's launch: data is the bottleneck, ultra-cheap always-on trace monitoring is rising, and the Jevons paradox means usage will only grow.
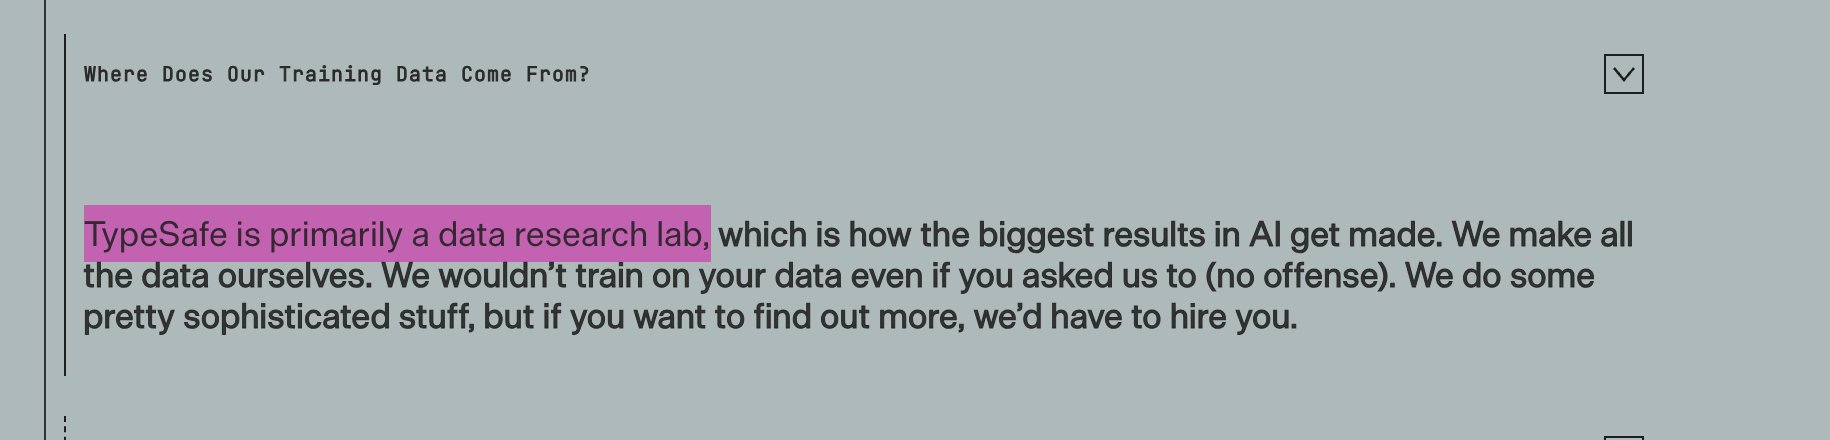
some underrated points + important second order effects of the wildly successful Jev launch 1. Data is the bottleneck! TypeSafe calls themselves a “data research lab”. To build a general purpose classifier or actor of any kind, you need to painstakingly curate and create tons of high-quality data (Traces, Examples, Evals/Environments/Worlds, Simulations). This helps the model learn these distributions so it can do good work for users. This is especially true for building domain specific, vertical agents. Look at the data. Every team looking to build better agents will need help + tooling to help them with this. If teams can spend more time building good data, then they will build better models & agents. 2. The explosion of ultra-cheap, always-on Monitoring + Data Mining of Agent Traces at scale To build better agents, we need to understand them at scale. We also saw the large need to real-time monitor and flag bad behavior during the OpenAI-HuggingFace Incident. Models like Jev help us do this because they’re very fast and cheap for classification. There’s a simple pipeline here: Gather Traces —> Label Them aggressively —> Make Evals/Environments from them (optional) -> Fine-Tune Cheaper Model. Part of data hygiene is understanding data at scale. We sort of had the tooling to do this before by fine-tuning small models or sending smart agents to read lots of traces. We’ll still use agents to mine traces because Jev has limitations like context window length, but this is a great tool for: - humans to define dimensions up front on what they care - using Jev to triage data across important dimensions for further review. 3. We are never escaping Jevon’s paradox Models like Jev just help us do more. Classify more traces, monitor more actions in real-time. This is all net-new addition of compute and will happen at massive-scale over every piece of data agents create. This is all very exciting because though we’ll use more compute, we’ll understand much more to build better systems.
This post quotes another post: “ChatGPT co-inventor releases Jev, a model built for decisions rather than text”