Using Jev as a judge to grade RL environments
Treating RL verification as a classification problem, Jev can replace LLM-as-Judge scoring of outputs and trajectories, cutting verification cost and time at scale, though it still needs calibration.
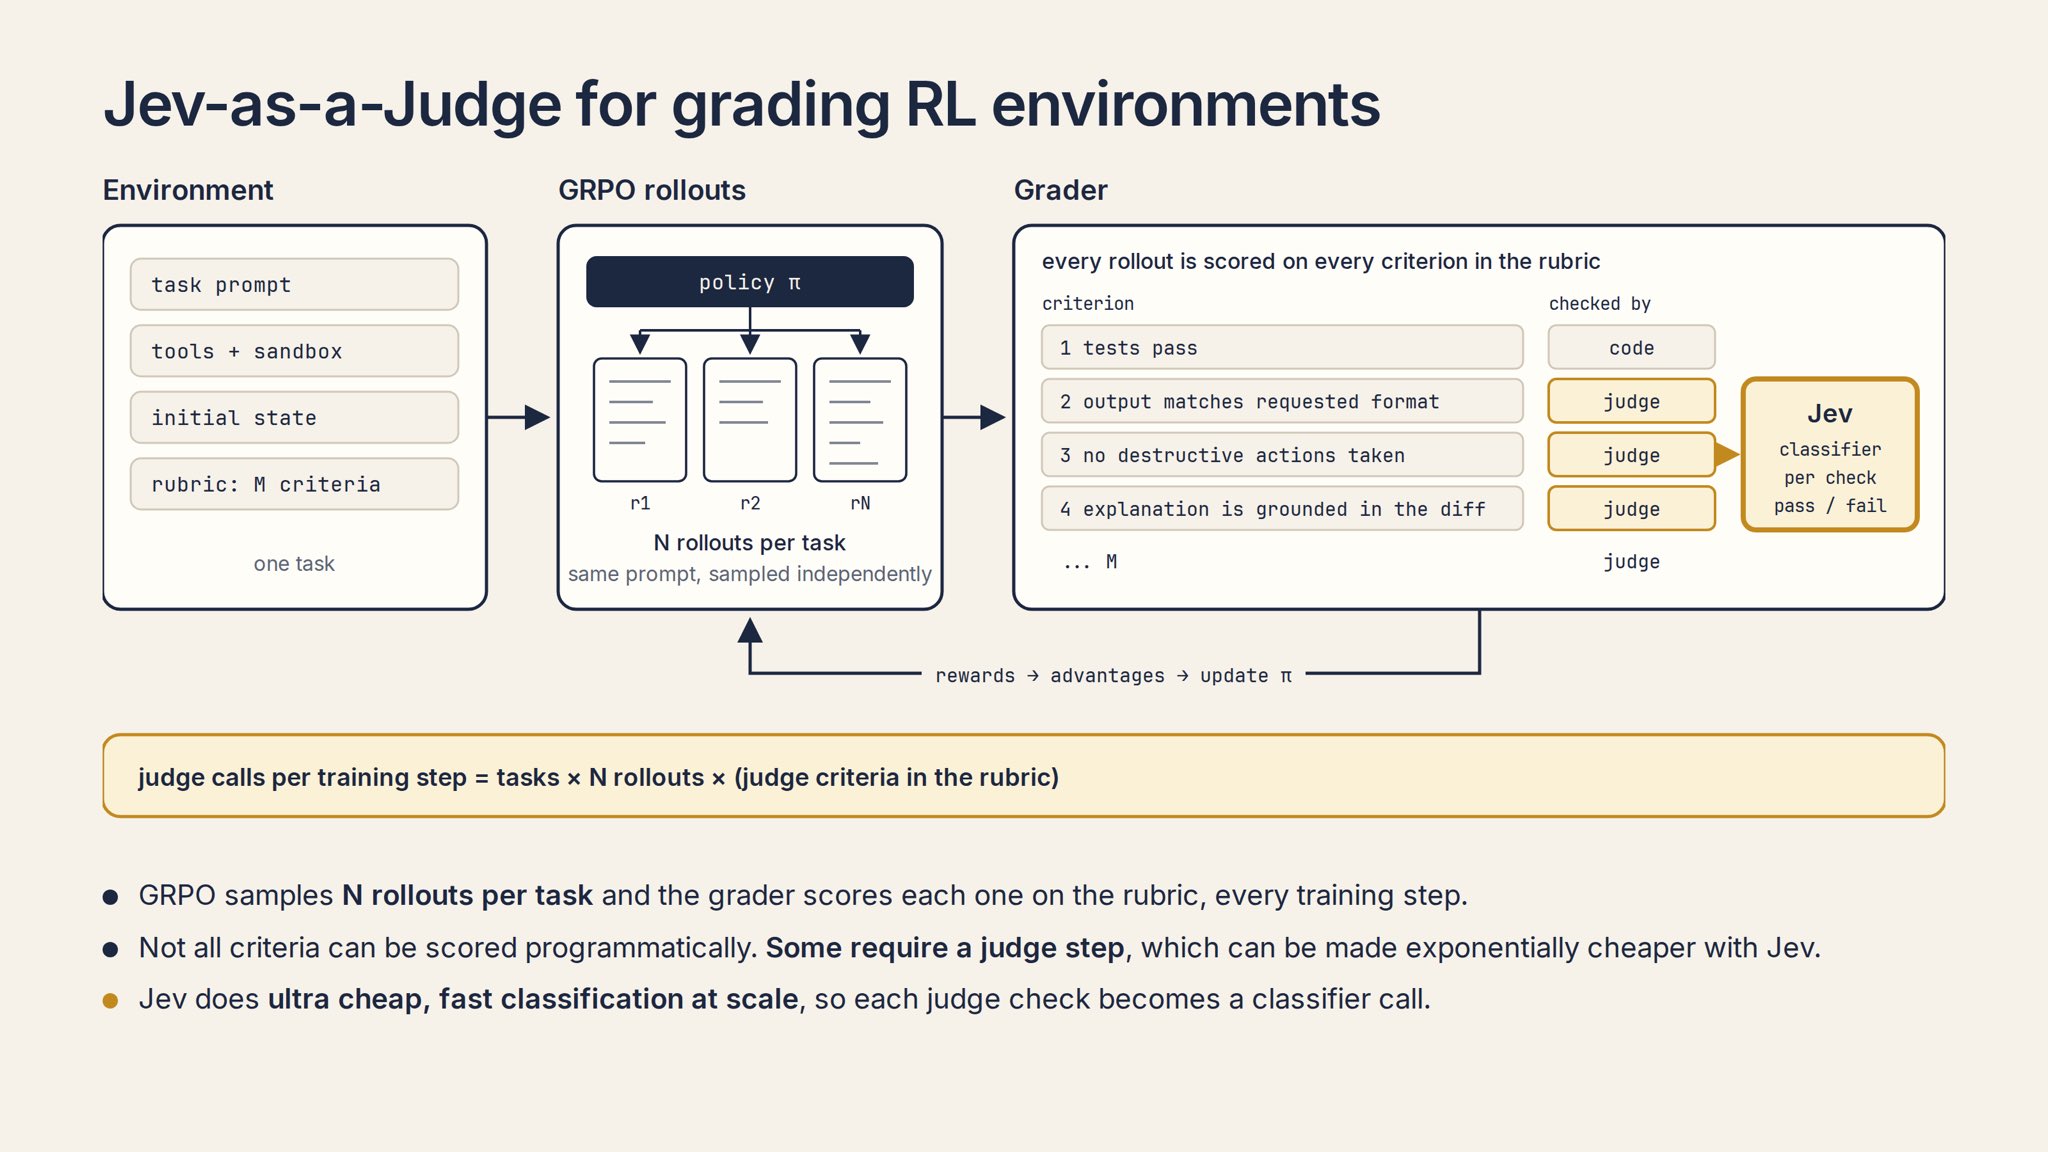
Jev-as-a-judge🤝 RL Environment Verifiers 🤝 way cheaper + faster RL a lot of things in Agent World look like classification problems…including grading RL - many RL Tasks need a judge to verify pieces of outputs or trajectories - at scale this can be very expensive and slow with tons of rollouts to score - Jev is incredibly fast and cheap meaning, can potentially remove the verification bottleneck for many tasks we previously worked with @harvey on their LAB benchmark which used LLM-as-Judge for tens of criteria per task we found that Harness/Prompt Engineering + Open Models meant we could judge tasks orders of magnitude cheaper like any verifier, it needs to be calibrated to make you’re giving back a good signal but Jev has the opportunity to massively bring down verification costs (and tuning friction) for many tasks which means more teams will do RL, which is great!
This post quotes another post: “LangChain tests Jev against LLM judges for agent evaluation”