gpt-6IMAGE
Astra trails Muse on AutomationBench, but scores aren't comparable
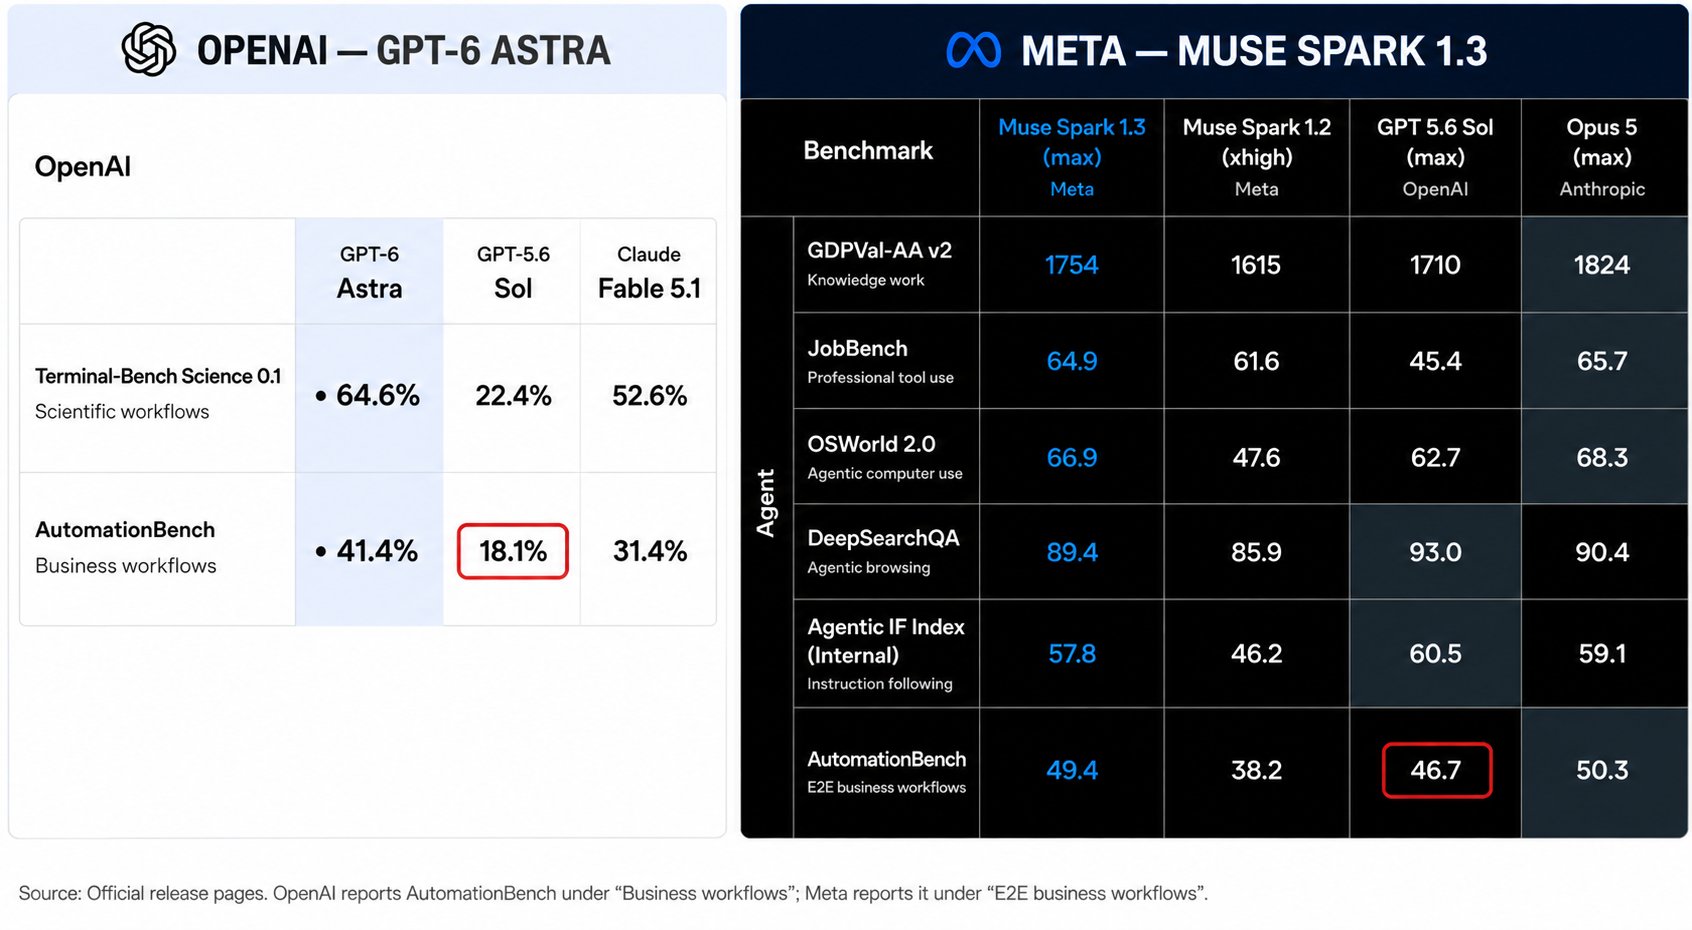
Muse scores 49.4% versus Astra's 41.4% on the same benchmark, but the shared GPT-5.6 Sol baseline differs by 28 points between the two evaluations, so the scores can't be compared directly.
Xinya Du
@Xinya16Archived 2026.09.14Originally posted 2026.09.04
Xinya Du @Xinya16Originally posted 2026.09.04
AutomationBench is the only overlapping benchmark in the Muse Spark 1.3 and GPT-6 Astra release tables: Muse: 49.4% Astra: 41.4% Looks like Muse wins—but the shared GPT-5.6 Sol baseline scores 46.7% in Meta’s eval vs. 18.1% in OpenAI’s. Meta specifies the public v3 task set. I couldn't find the corresponding detail for GPT-6, its evaluation is clearly much harder on the shared baseline. Same benchmark name ≠ comparable scores. Model leaderboards need eval provenance.
x.com/xinya16/status/2095742003959263553Archived 2026.09.14 16:18