DeepSeek V4.1 Flash on 4x RTX 6000: 340 tok/s single stream in NVFP4
A user's revised inference recipe runs DeepSeek V4.1 1017 in NVFP4 on four RTX 6000 GPUs at 340 tok/s single stream, up from 160 tok/s with an incomplete config.
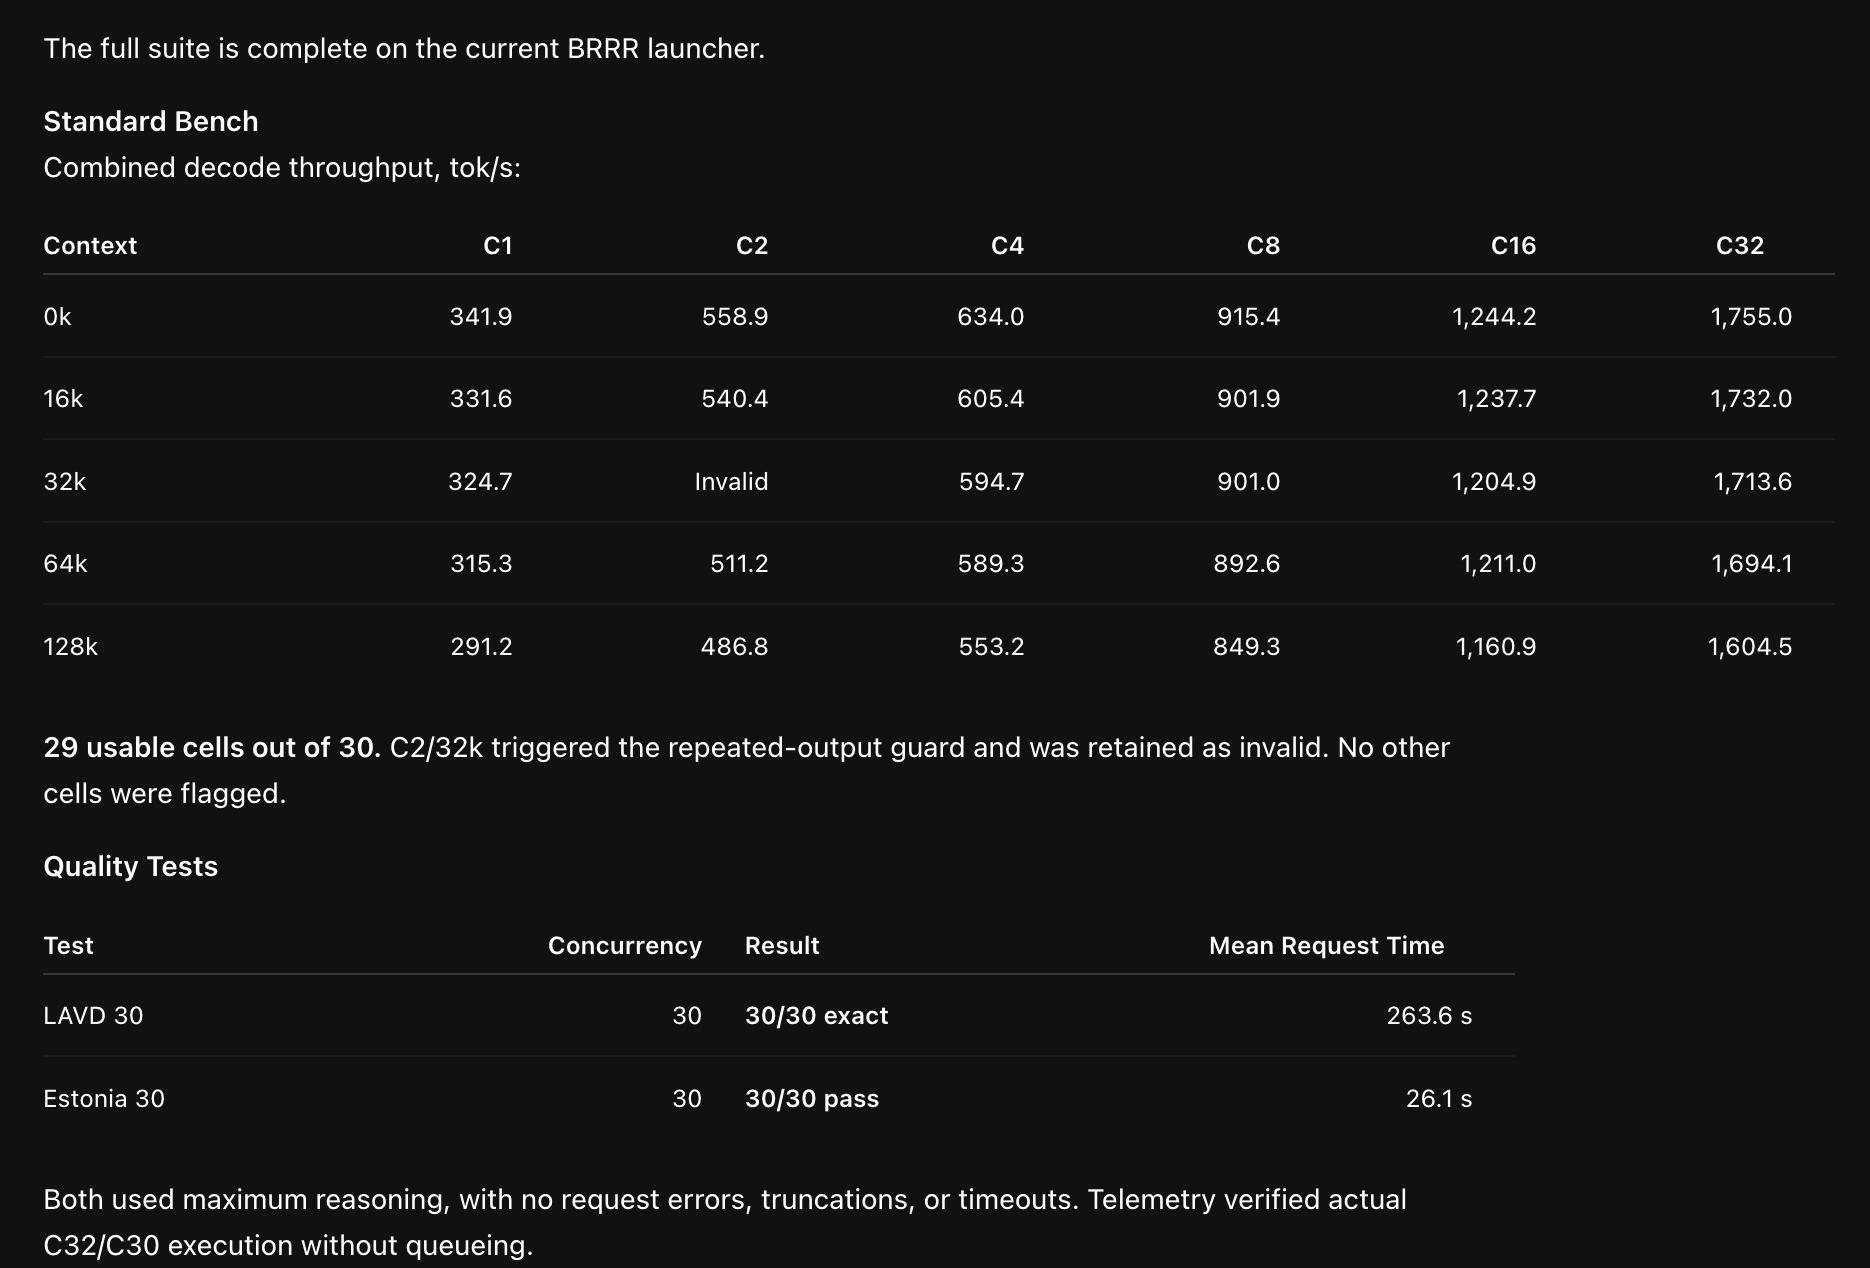
Modified version of @fraserpricee 's recipe is printing deepseek v4.1 1017 tokens at 340 tok/s single stream which is the fastest I've experienced on my own hardware for NVFP4. Turns out previous 160 tok/s results were largely because fraser's recipe was incomplete and didn't contain all configs needed. Fraser was helpful (and had a much lower boast/receipt ratio) in DM communication. 😅 The claimed 700+ tok/s is still largely based on measurement yardstick optimization. Wasn't easy getting the man to acknowledge that standardized measurement is just basic intellectual honesty, but the stack is real. Below C8 this is the fastest I'm aware of for serving ds41f on tp4 rtx6k. llm-inference-bench image below shows a modified version of BRRR. I'm calling it BRRR/B12X hybrid as it uses native B12X above 8 scheduled tokens which leads to some gains at higher concurrency. Recipe in 🧵
This post quotes another post: x.com/zenmagnets/status/2114768356339568829