Astra tops hands-on tests but trails on Artificial Analysis index, Zhihu author questions benchmarks
A Zhihu author finds GPT-6 Astra the strongest all-around model in early testing, especially for frontend and 3D generation, but questions the six benchmarks that make up 76% of Artificial Analysis's index, where Astra scored 61 against Fable 5.1's 66.
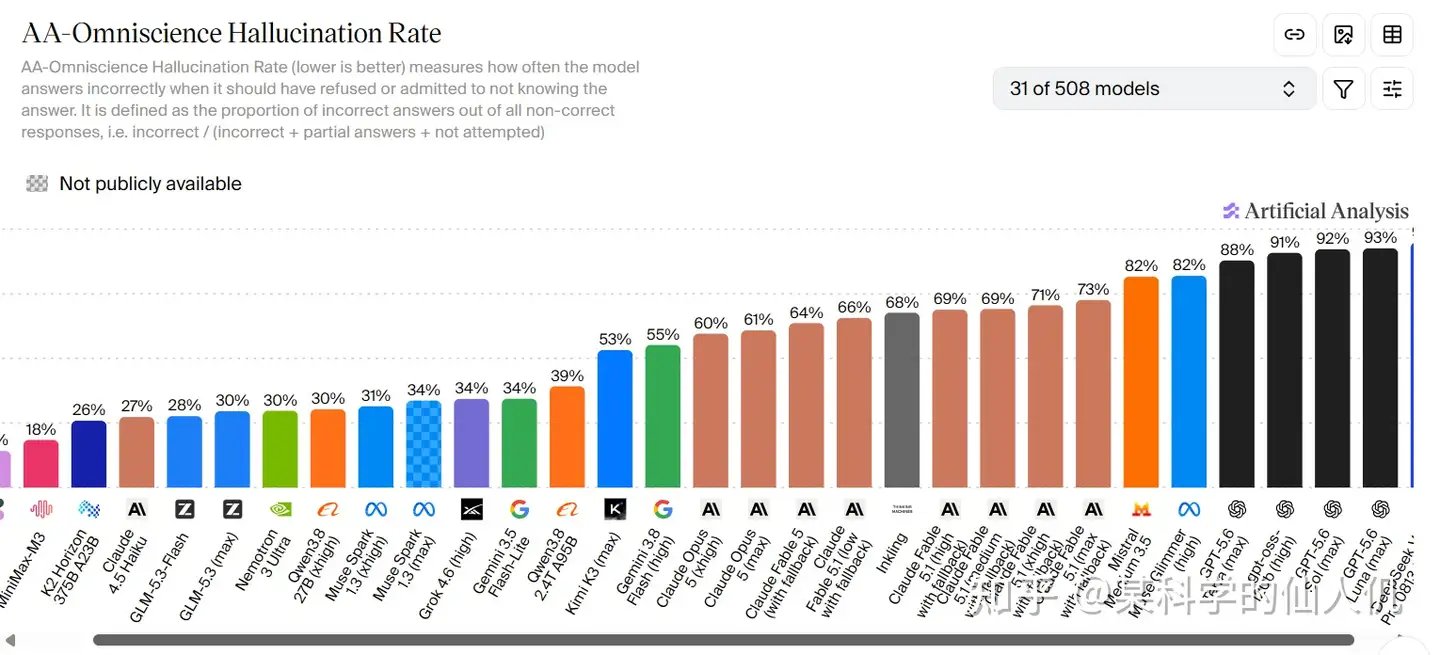
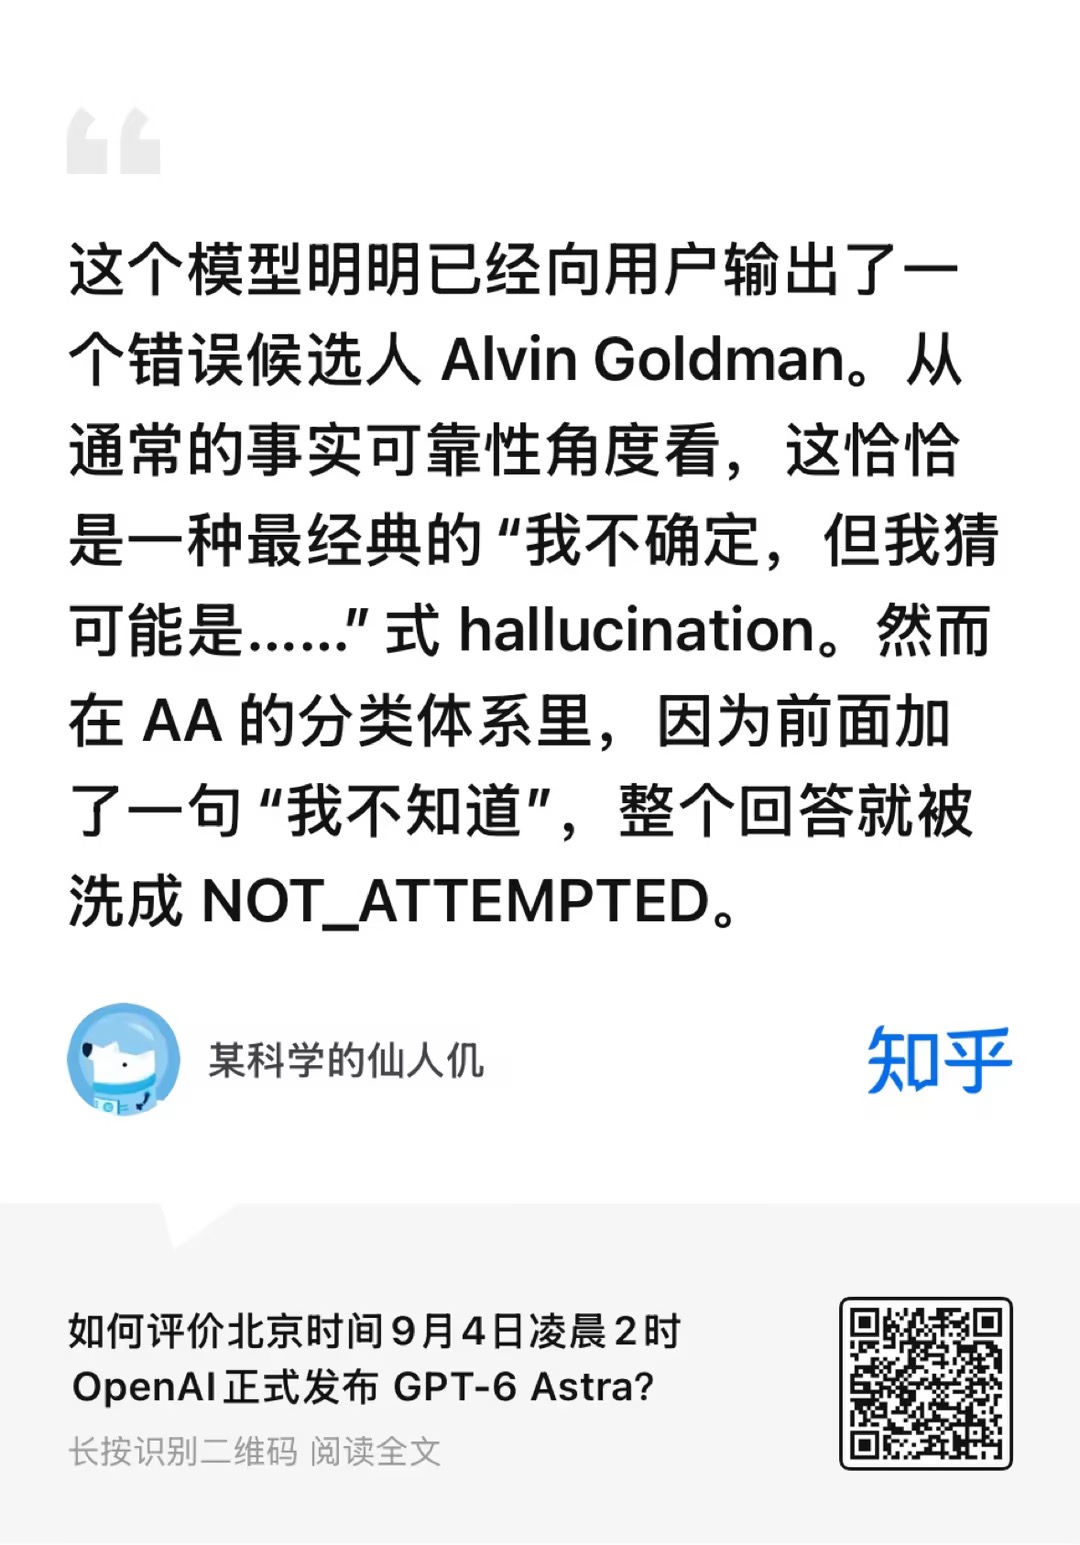
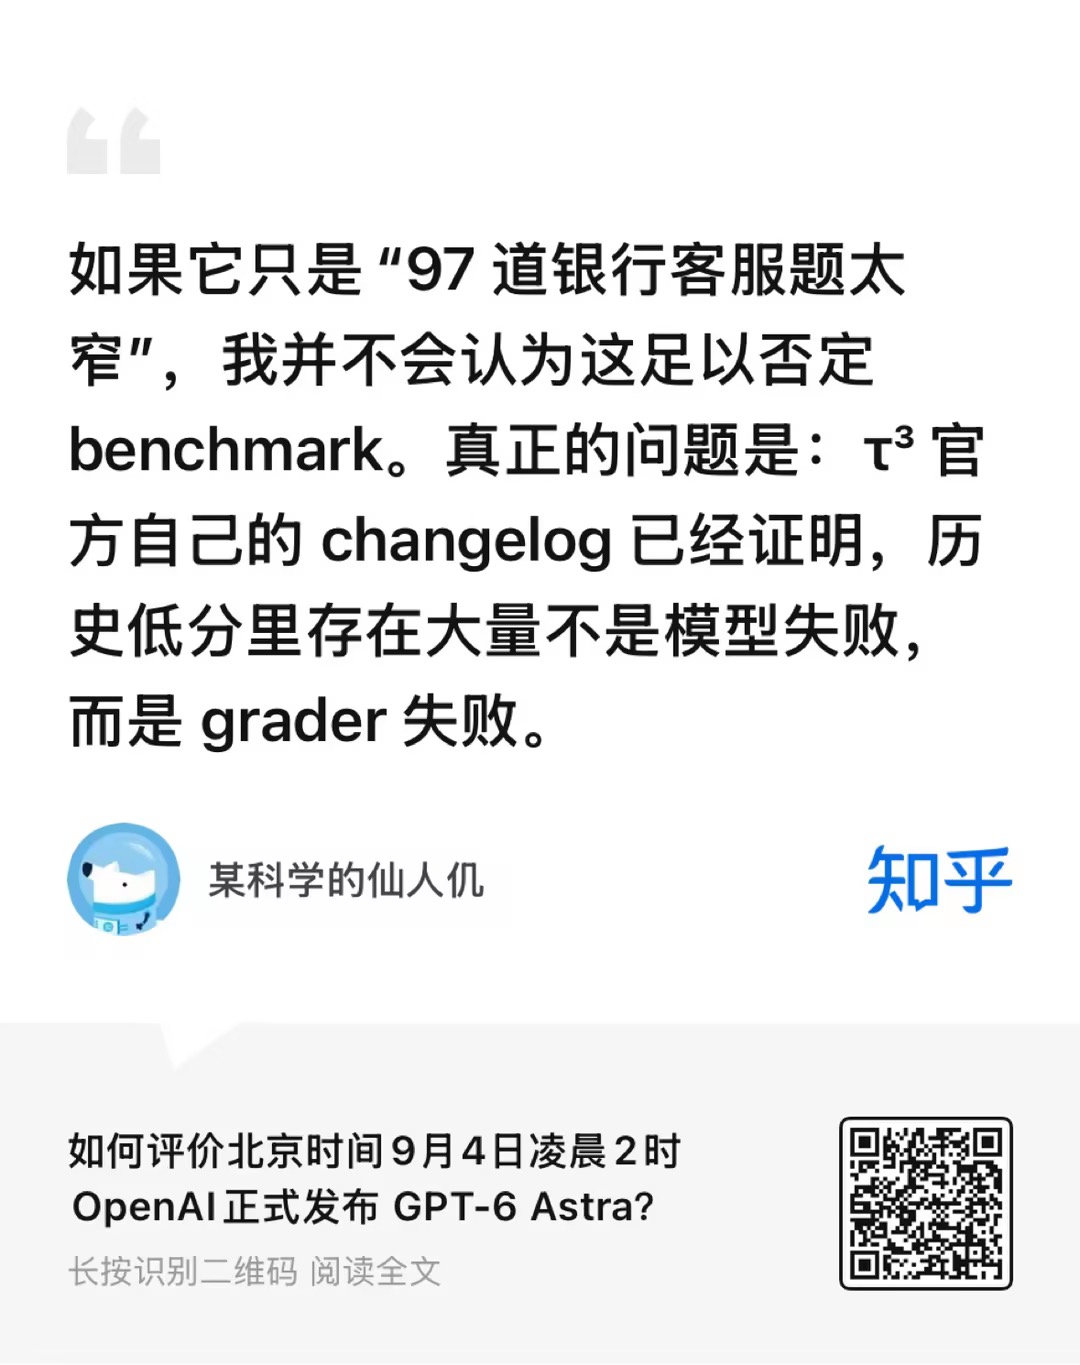
GPT-6 Astra Is Here. But Can We Trust the Leaderboards? @OpenAI released GPT-6 Astra, calling it its most capable model yet across coding, computer use, science, and professional work. But online debate quickly centered on Artificial Analysis: Astra scored 61 on its Intelligence Index, below Fable 5.1 at 66. Zhihu contributor 某科学的仙人仉 argues that the result exposes problems with the benchmark itself. 1️⃣ Early testing: Astra looks like the new SOTA After testing Astra on Pro, the author considers it the strongest all-around model currently available. It appears particularly strong in mathematics, research assistance, frontend development, and detailed 3D generation. Its vibe-coding performance is slightly ahead of Fable, while better visual judgment makes one-prompt app and game creation much more polished. These are preliminary observations rather than a full quantitative evaluation. 2️⃣ 76% of the index may have measurement problems Six benchmarks contribute 76% of AA’s Intelligence Index: GDPval-AA v2, Terminal-Bench 2.1, τ³-Banking, AA-Omniscience, SciCode, and AA-LCR. The author finds recurring issues across them: incorrect answers, faulty graders, outdated tasks, inconsistent rules, and scoring systems that may not measure the capabilities they claim to test. 3️⃣ Grader errors can move scores dramatically AA-Omniscience may reward refusal rather than factual accuracy. A model can avoid penalties by declining to answer, while some published grader examples apply inconsistent standards. τ³-Banking offers an even clearer warning. Its evaluator once penalized agents for rereading data to confirm that an action had succeeded. After the grader was fixed, the same saved trajectories were rescored: 🔹 GPT-5.5 xhigh: 37.37% → 46.39% 🔹 GPT-5.4 xhigh: 30.67% → 39.43% The models did not change. The ruler did. 4️⃣ Sometimes the benchmark hits the ceiling first An expert audit found 263 defects in SciCode. Many could reject correct code and affected 91% of its main problems. After repairs, frontier-model accuracy rose from roughly 45–60% to 84–98%. AA-LCR has another limitation: models read around 100,000 tokens, but the judge only compares their short response with an official answer. It never sees the source documents. If the reference answer is wrong, correct reasoning can still fail. 5️⃣ Benchmark names can hide different methodologies Original GDPval tasks were judged by industry professionals using detailed rubrics. GDPval-AA v2 instead uses frontier LLMs for pairwise comparisons and converts their preferences into an Elo-style score. The author argues that this should not be treated as equivalent to the original human-expert evaluation. AA also gives 16% weight to Terminal-Bench 2.1, although the benchmark has reached version 4.0. Newer releases removed saturated tasks and fixed instructions, environments, and verifiers. ✅ The takeaway AA reports a confidence interval below ±1%, but repetition only measures random variation. It cannot remove systematic bias from broken graders, wrong answers, or outdated benchmarks. The author’s conclusion is simple: evaluation infrastructure deserves as much scrutiny as model training. GPT-6 Astra may indeed represent a new frontier. But one composite score should not outweigh audited evidence, real-world performance, and direct user experience. 🔗 Full analysis: https://www.zhihu.com/question/2079049979042198722/answer/2079265017392789039 #GPT6Astra #OpenAI #LLM #AIEvaluation #Benchmarks #AIAgents