Zhihu review: Astra scores higher while using fewer tokens
On a logic benchmark Astra scored 87.64 with 69% fewer tokens and about half the time, which the author sees as OpenAI's 'compression is intelligence' bet paying off.
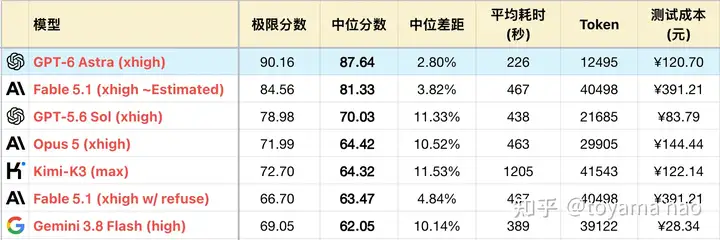
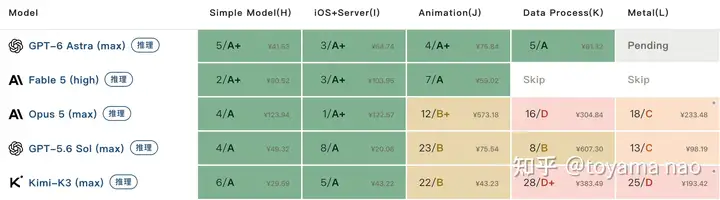
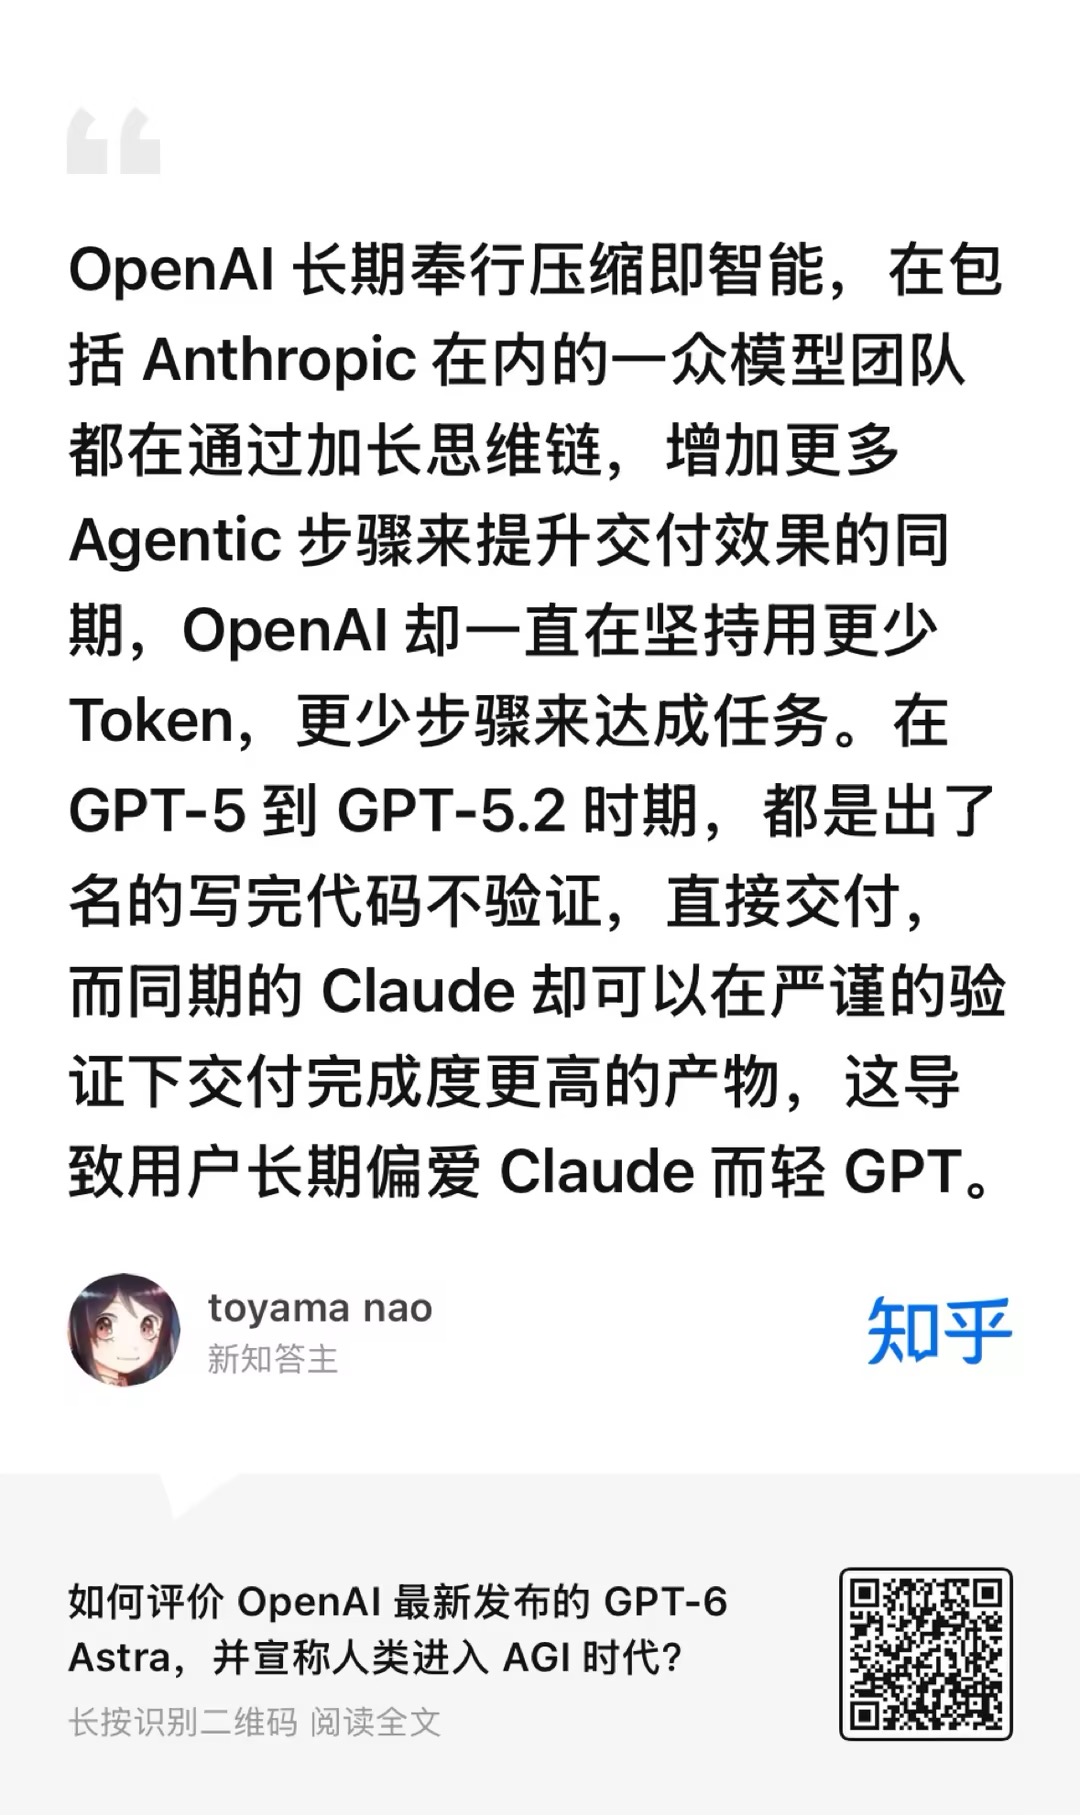
GPT-6 Astra’s Real Breakthrough: More Intelligence per Token In toyama nao’s logic benchmark, Astra scored 87.64 versus an estimated 81.33 for Fable 5.1, while using 69% fewer tokens and finishing in roughly half the time. The leap is not longer reasoning. It is stronger reasoning with less computation. Rather than debating the AGI label, Zhihu contributor toyama nao focuses on a measurable shift: OpenAI’s “compression is intelligence” bet appears to be paying off. 1️⃣ OpenAI chose the opposite path While other labs extended chains of thought and added more agentic steps, OpenAI kept pushing models to finish tasks with fewer tokens and actions. That once meant under-verifying code: GPT-5 and GPT-5.2 could trail Claude’s more careful workflows in delivery quality. 2️⃣ Astra changes the trade-off In the author’s partial comparison, sorted by median score: 🔹 GPT-6 Astra: 87.64 points, 12,495 tokens, 226 seconds, RMB 120.70 🔹 Fable 5.1 (estimated): 81.33 points, 40,498 tokens, 467 seconds, RMB 391.21 Astra leads while using far less time, computation, and test cost. 3️⃣ From parity to a clear lead The author calls GPT-5.6 the first milestone: it matched leading models with slightly lower resource use. Astra is the second. OpenAI’s efficiency-first approach now appears to improve capability and delivery at the same time. 4️⃣ The frontier keeps moving AI progress often follows a cycle: users ask too much, models disappoint, and those same requests eventually become routine. In 2023, few developers would hand AI their core codebase. Today’s frontier models can handle far more of that work. The next “wish list” is already taking shape. 🔗 Full Reading: https://www.zhihu.com/question/2079054472190469850/answer/2079717779138205220 📊 Benchmark methodology: https://zhuanlan.zhihu.com/p/2077362656424600453 📈 Full leaderboard: https://llm2014.github.io/llm_benchmark/ #GPT6Astra #OpenAI #LLM #AIResearch #AIBenchmarks