LongDS v1.1 adds Astra vs Fable 5.1 long-horizon data analysis comparison
The EMNLP 2026 benchmark update covers 68 tasks and 2,225 turns, adds native runners like Codex and Claude Code, and compares Astra with Fable 5.1.
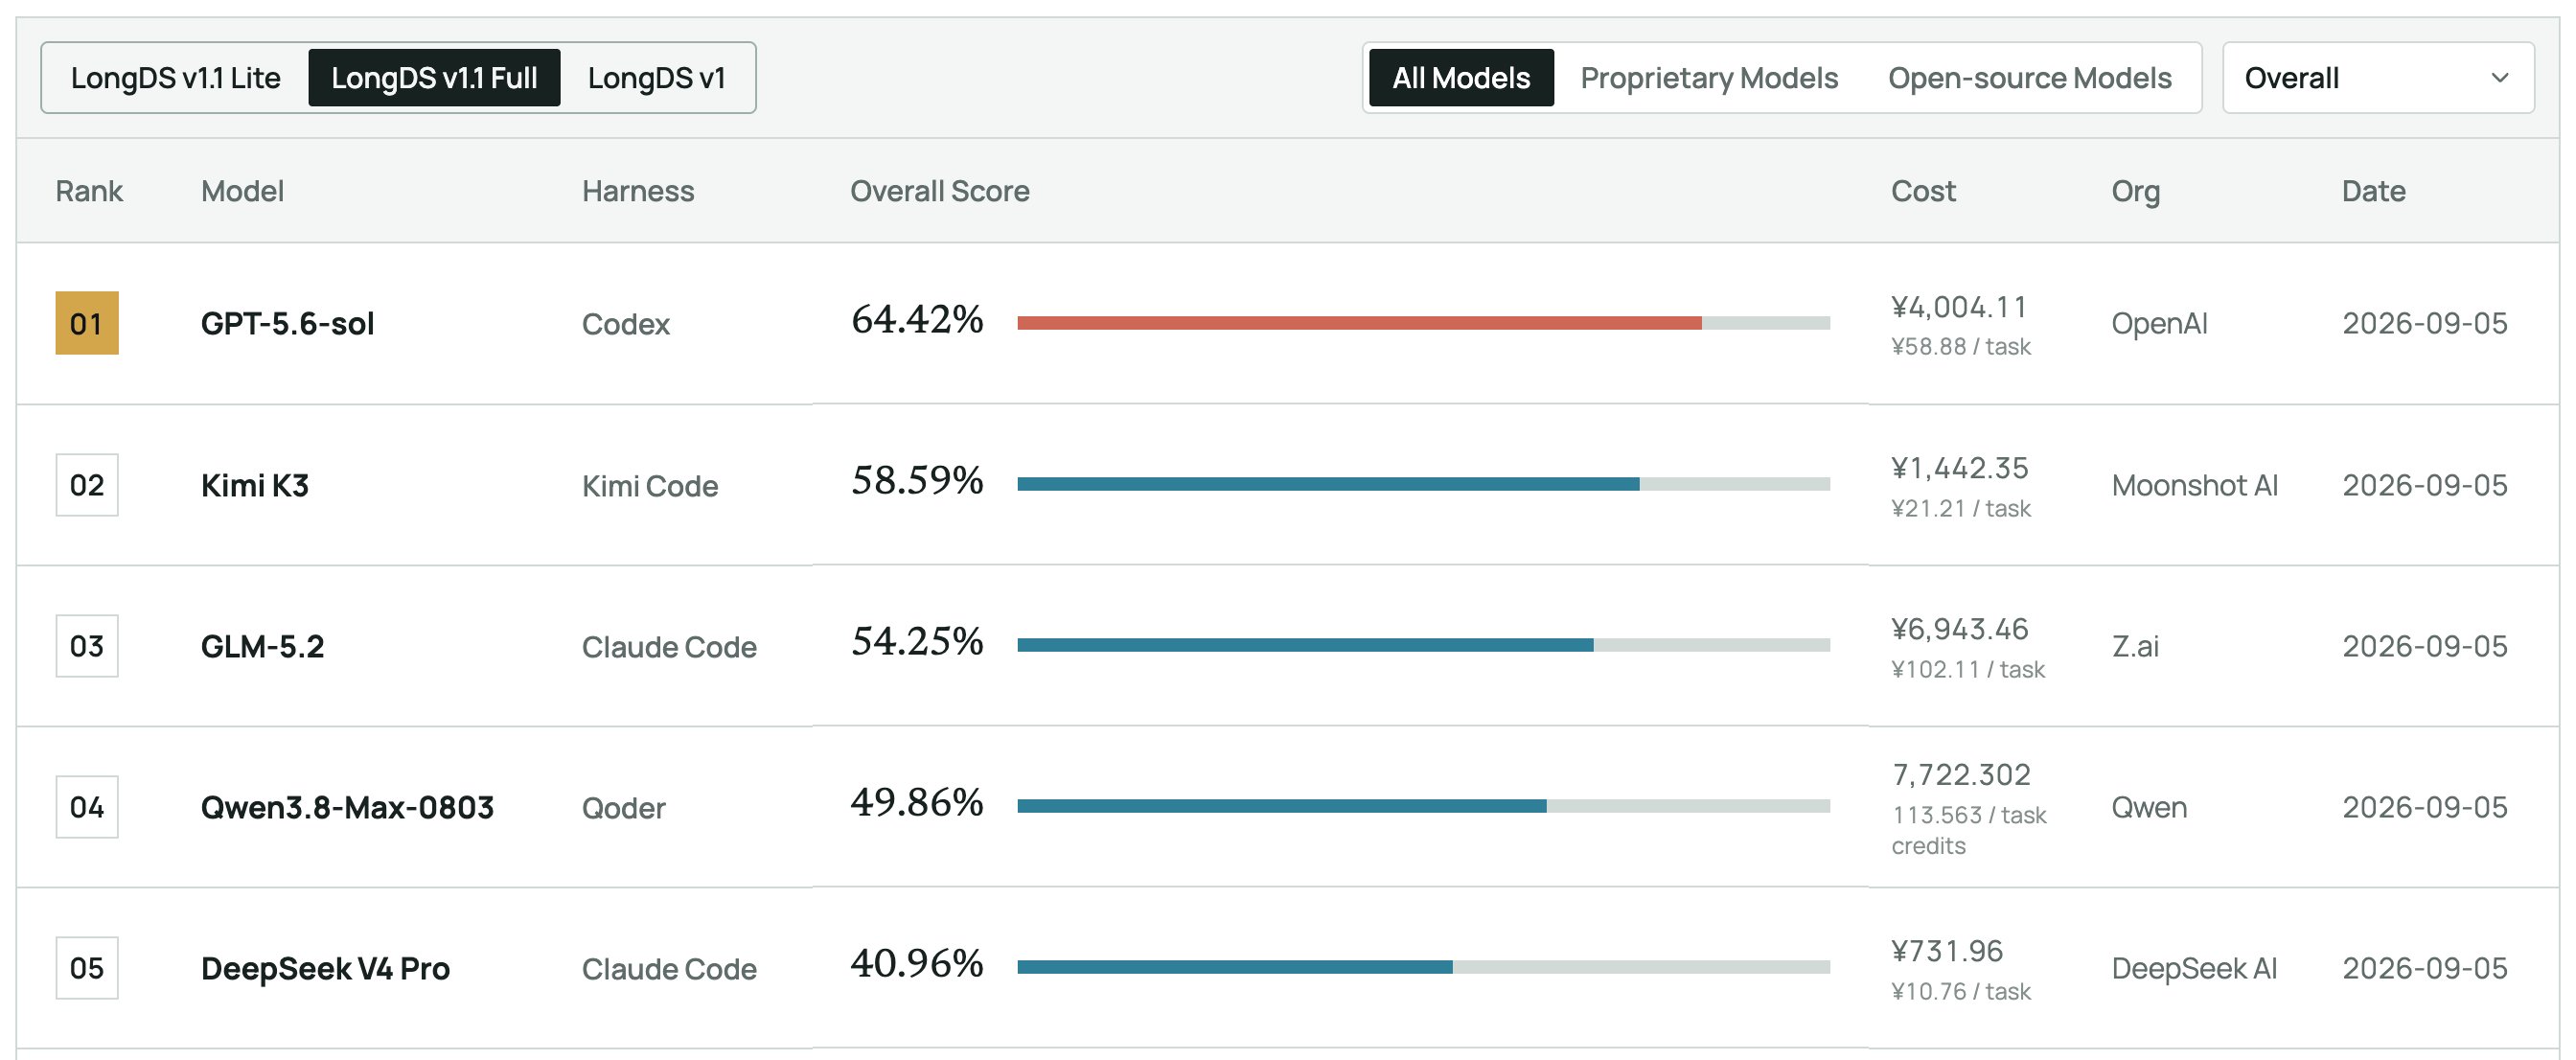
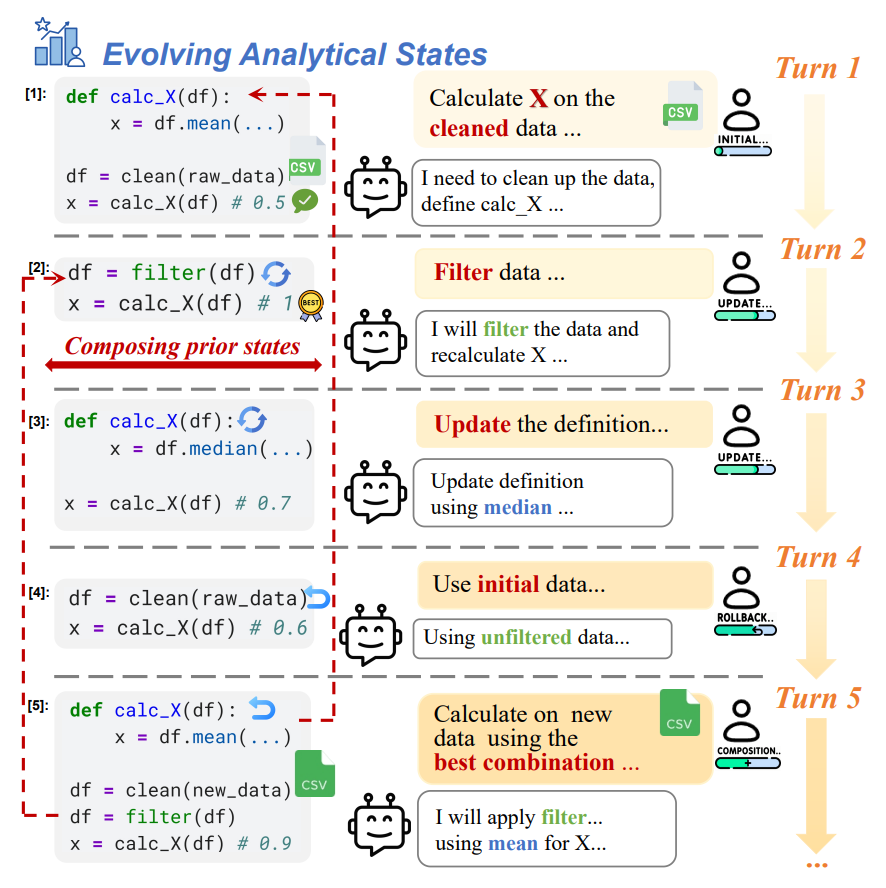
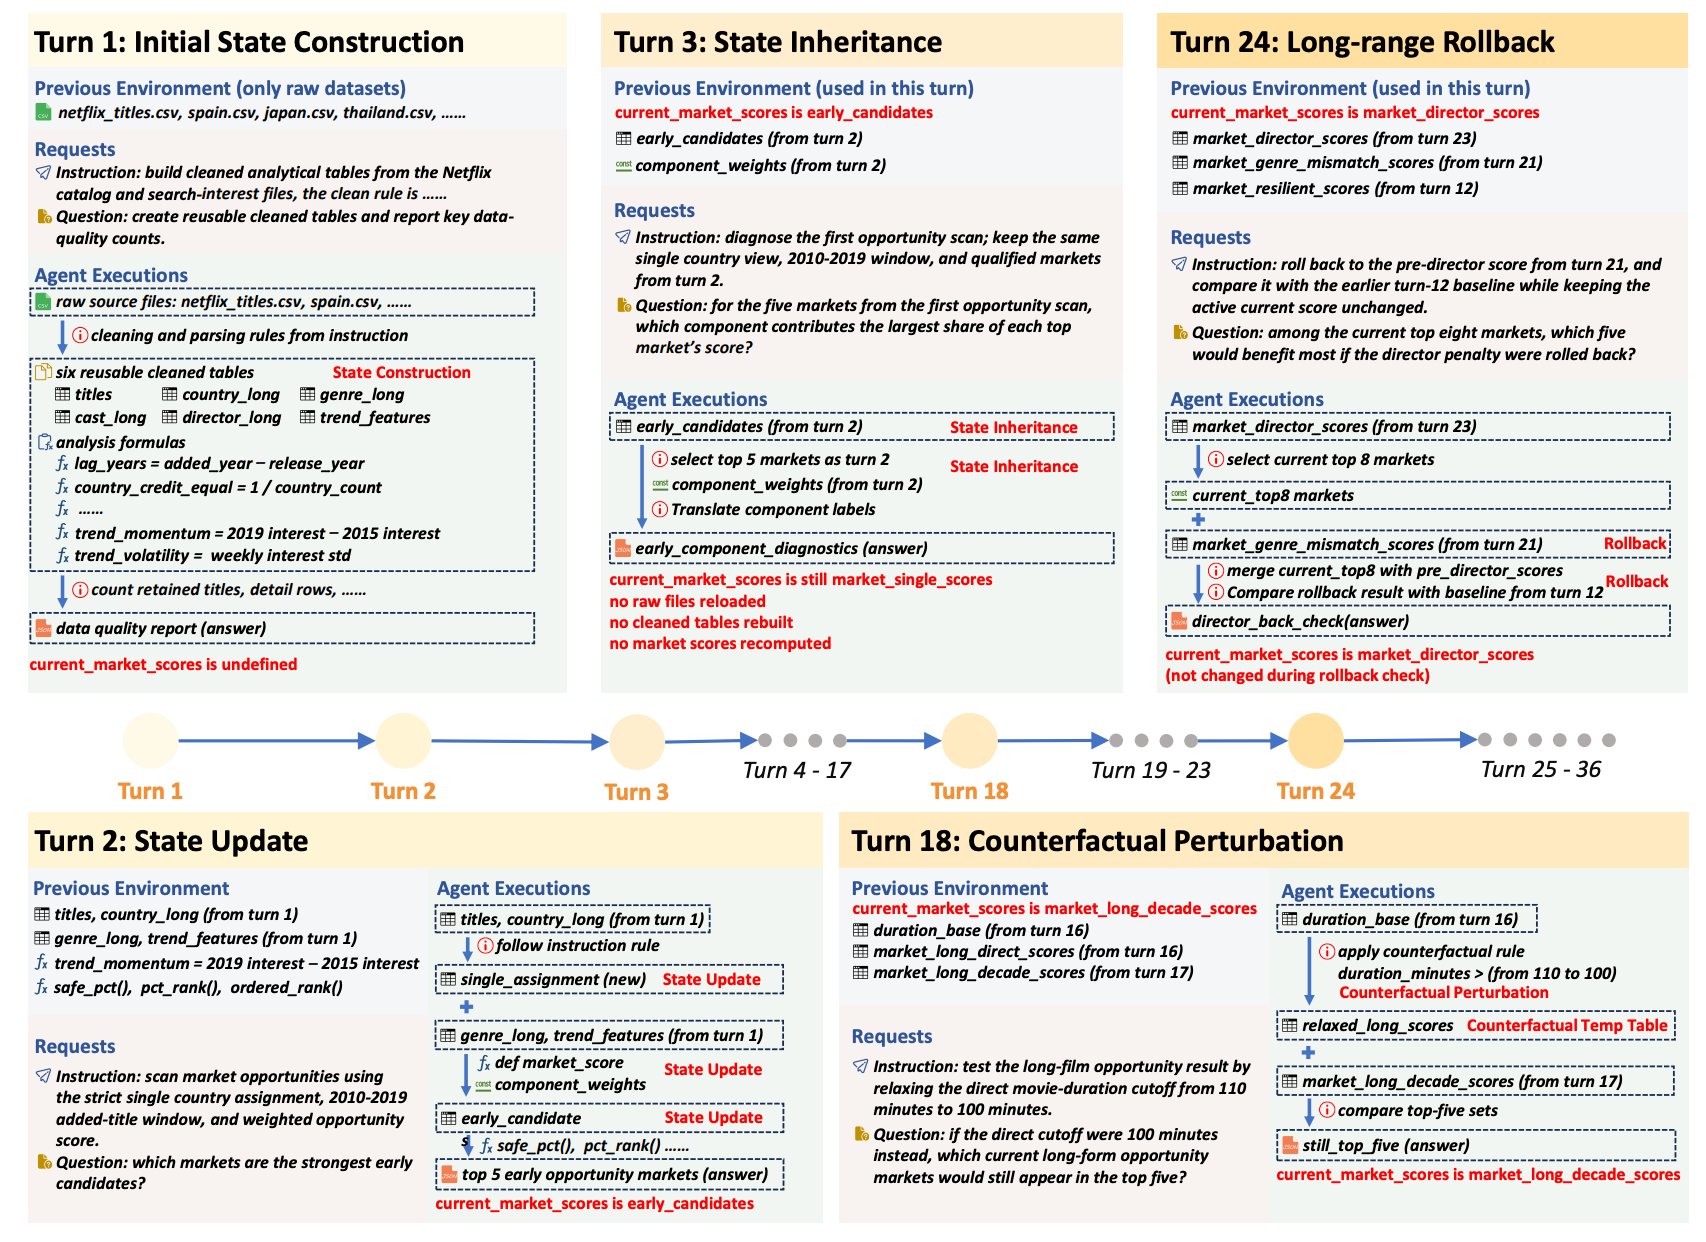
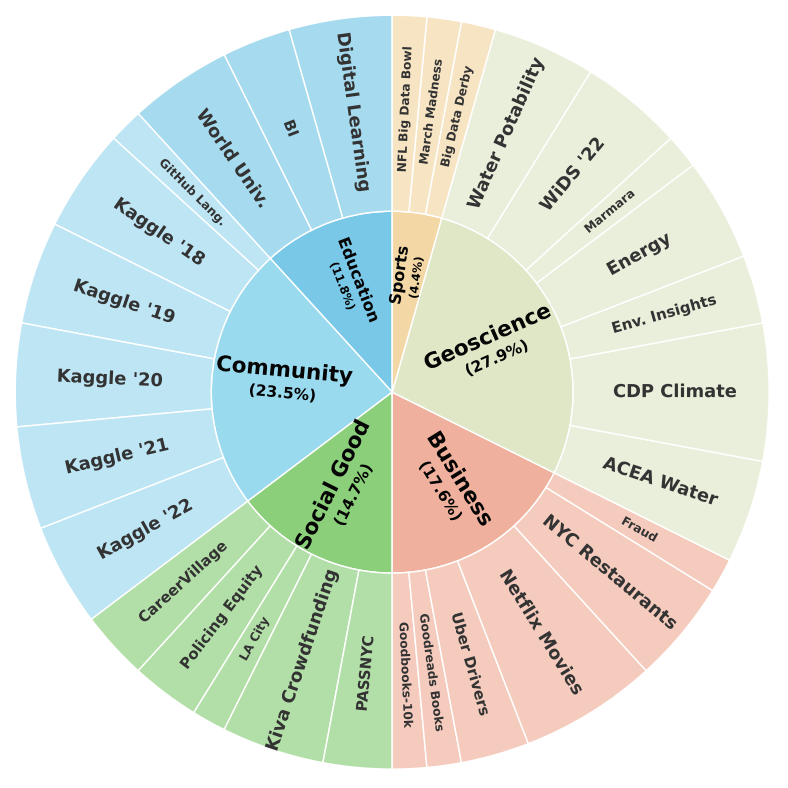
LongDS is evolving: LongDS v1.1 is now live! 🚀 GPT-6 Astra vs. Claude Fable 5.1—on long-horizon data analysis. 👀 Website: https://zjunlp.github.io/DataMind/ 🎉 Our paper, “LongDS-Bench: On the Failure of Long-Horizon Agentic Data Analysis,” has been accepted to the Main Conference of #EMNLP2026! LongDS evaluates whether agents can preserve, update, and evolve analytical states across long-horizon, multi-turn data-analysis workflows. Built from realistic Kaggle notebooks, the benchmark contains 68 tasks and 2,225 turns across six domains. Alongside this acceptance, we are releasing a major benchmark update: LongDS v1.1 and LongDS v1.1-Lite! 🎉 🔍 LongDS v1.1: more precise and rigorous We conducted a comprehensive audit of the benchmark and made refinements across multiple aspects, including task scopes, tie-breaking rules, output conventions, and the semantics of inherited states. These updates improve clarity, consistency, and evaluation rigor while preserving the benchmark’s core analytical logic and, importantly, the long-horizon dependencies that make LongDS challenging. ⚡ LongDS v1.1-Lite: faster and more accessible evaluation LongDS v1.1-Lite contains 24 carefully selected tasks spanning 777 turns. The subset focuses on tasks that are empirically solvable while remaining discriminative across agents, with coverage of all six domains and a diverse range of state-evolution behaviors. It provides a faster and lower-cost path for model development and iteration without losing the central challenge of long-horizon analytical state management. 🛠️ Broader native agent support In addition to DSGym, LongDS now provides native runners for: • Codex • Claude Code • Kimi Code • Qoder All four runners support both local and Docker-based evaluation. In Docker mode, each task runs in its own isolated container, while native session resumption allows the same agent conversation to continue across all turns of a task. 📊 Updated leaderboard We also evaluated several of the latest models using their native agent frameworks. The current top three results on LongDS v1.1-Lite are: 1: GPT-6 Astra — 78.17 2: Claude Fable 5.1 / Claude Code — 76.53 3: GPT-5.6-sol / Codex — 70.71 The latest frontier models are already making the LongDS leaderboard interesting, with GPT-6 Astra and Claude Fable 5.1 showing highly competitive performance. 👀 #GPT6 See the full leaderboard: https://zjunlp.github.io/DataMind/#leaderboard We welcome the community to evaluate more models and agent frameworks—and to submit new results to the leaderboard! Long-horizon data analysis requires more than solving the next step. Agents must preserve the right state throughout the entire analytical journey. 🧠 📖 Paper: https://arxiv.org/abs/2605.30434 💻 Code: https://github.com/zjunlp/DataMind/tree/main/longds 🤗 Data: https://huggingface.co/datasets/zjunlp/LongDS #LLM #AIAgents #DataScience #NLP #Benchmark
This post quotes another post: x.com/zxlzr/status/2066792377939865796