Upstream llama.cpp b11870 supports DeepSeek V4.1 Flash, but the author found the smallest working community GGUF (Q2_K) needs 246.3 GiB, far beyond 128 GB, and warns some fork GGUFs aren't interchangeable.
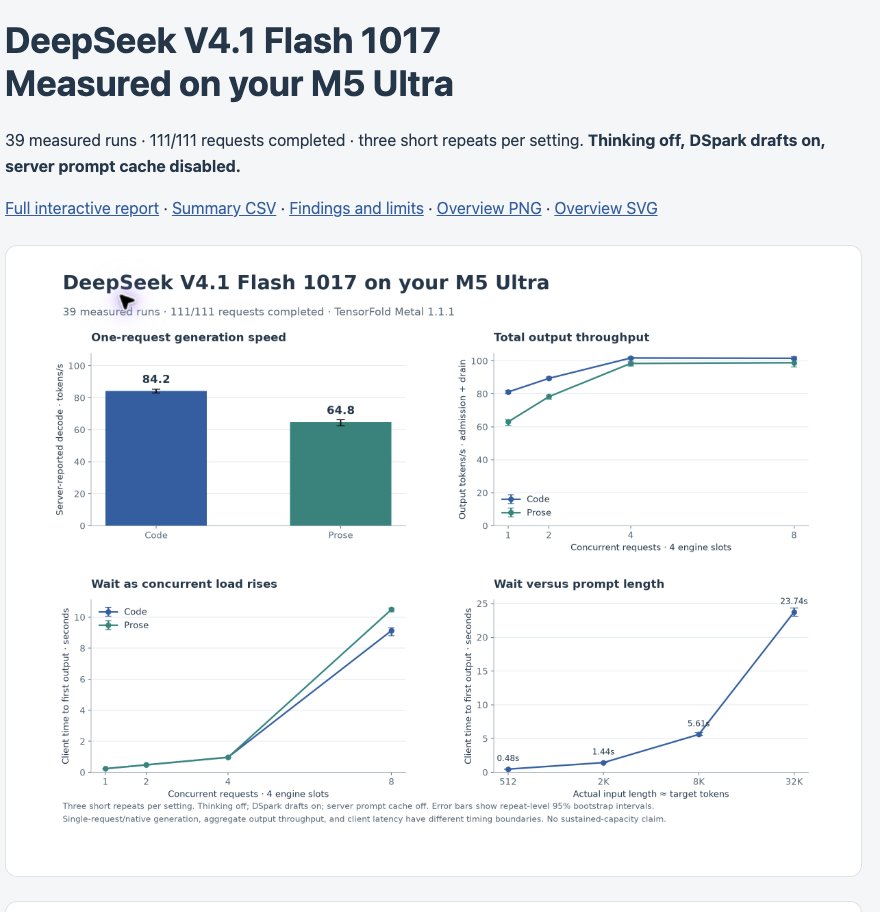
A user pushes back on the idea that only small 4-bit quants run locally, saying the full native quant of DeepSeek V4.1 Flash 1017 runs at solid speeds across 4x DGX Sparks.
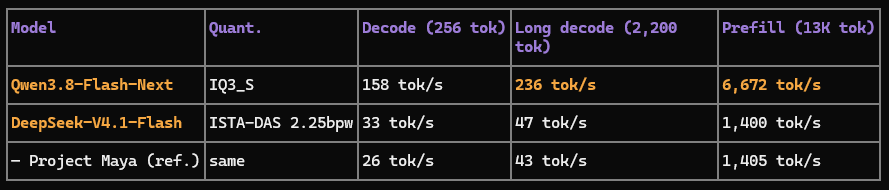
Local DeepSeek-V4.1-Flash at ISTA-DAS 2.25 bpw on one RTX 5090: 47 tok/s long generation and 1,400 tok/s prefill, beating Project Maya on the same box.
Local deployment: Maya-XS (93 GB) keeps every expert and Maya-S (122 GB) stays closest to the original, running on V100+ NVIDIA, Strix Halo and llama.cpp, plus a new loop guard against repeating answers.
The author tries a DeepSeek V4.1 Flash 1017 IQ2_XXS-Uncensored quant on Strata, swapping the SSD-resident Engram part from 4-bit to original MXFP8 weights using only the weights already on hand.