基于 Jev 架构的 10 步编码 agent 省钱蓝图
把 LLM 写、harness 执行、Jev 决定每轮看什么/路由到哪/是否运行拆开,用小模型决策替代前沿模型生成。
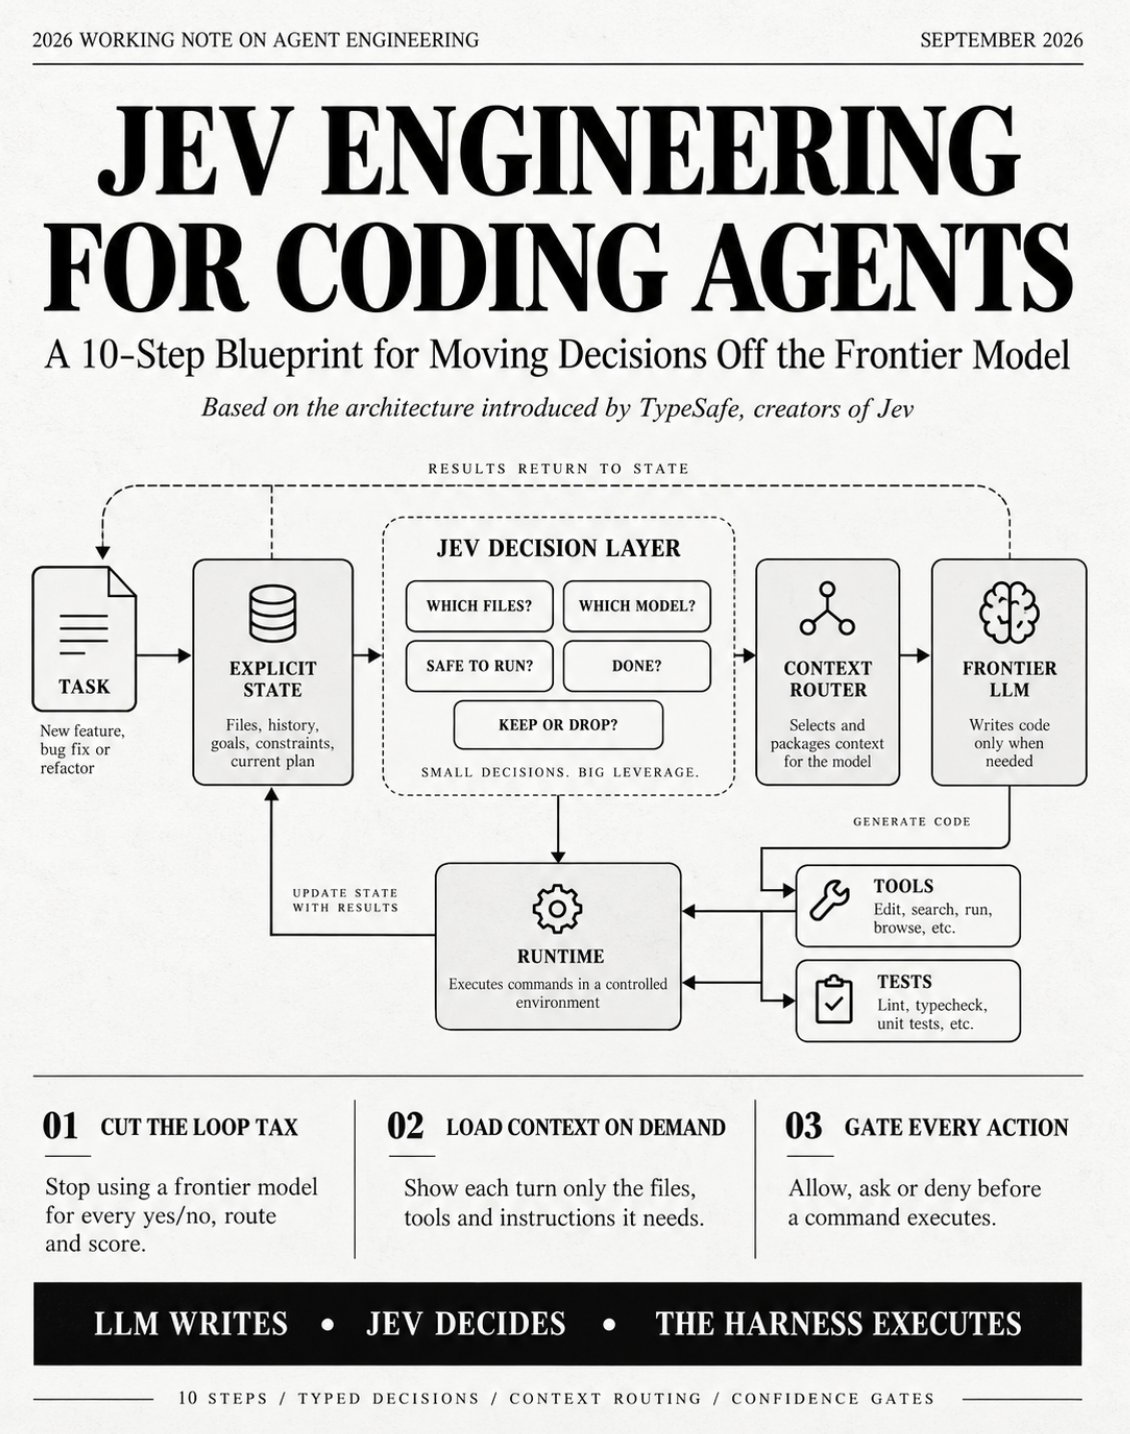
Сreators of Jev, TypeSafe, just showed why coding agents waste most of their frontier-model budget on decisions that never needed generation I turned the architecture into a 10-step blueprint for building faster and cheaper coding agents: step 1 → split the loop: the LLM writes, the harness executes, Jev decides what each turn sees, where it routes and whether it runs step 2 → make state explicit: store the task, current plan, file changes, tool results and test history outside the model context step 3 → move small decisions off the frontier model: which files matter, which model to call, whether a command is safe, whether the task is done and which outputs to keep step 4 → route by task: simple edits go to cheaper models, architecture and complex reasoning go to frontier models, uncertain requests go to review step 5 → retrieve once, then score context for the current query: hide it, summarize it or show it in full instead of reloading everything every turn step 6 → disclose tools in tiers: short descriptions first, schemas only when selected, documentation only when required step 7 → load instructions conditionally: touching frontend files loads the style guide, touching billing loads payment rules, running infrastructure loads deployment constraints step 8 → gate every command before execution: allow safe actions, ask for approval on uncertain ones and deny destructive operations step 9 → share one retrieval pass across reviewers, subagents, evals and background workers instead of paying to rediscover the same context step 10 → log every decision, confidence score, route and outcome — then tune the thresholds using real failures the architecture is simple: explicit state → Jev decision layer → context router → frontier LLM only when needed → runtime → tools and tests → state updated TypeSafe reports that Jev returns typed decisions in roughly 70–500ms and can be dramatically cheaper than generative models on narrow decision tasks the real advantage is not making the LLM write code faster it is preventing the LLM from wasting tokens on every yes/no, route and score surrounding the code LLM writes • Jev decides • the harness executes bookmark the blueprint and send it to your Claude Code or Codex instance ↓
这条是引用着另一条写的:「Jev 创始人讲「决策模型」而非聊天机器人」