用 Jev 当 LLM 输出防火墙与审核层
研究把 Jev 放在模型输出后做一次调用评估幻觉、注入、越狱等 10 类失败,返回校准概率决定放行、复核或拦截。
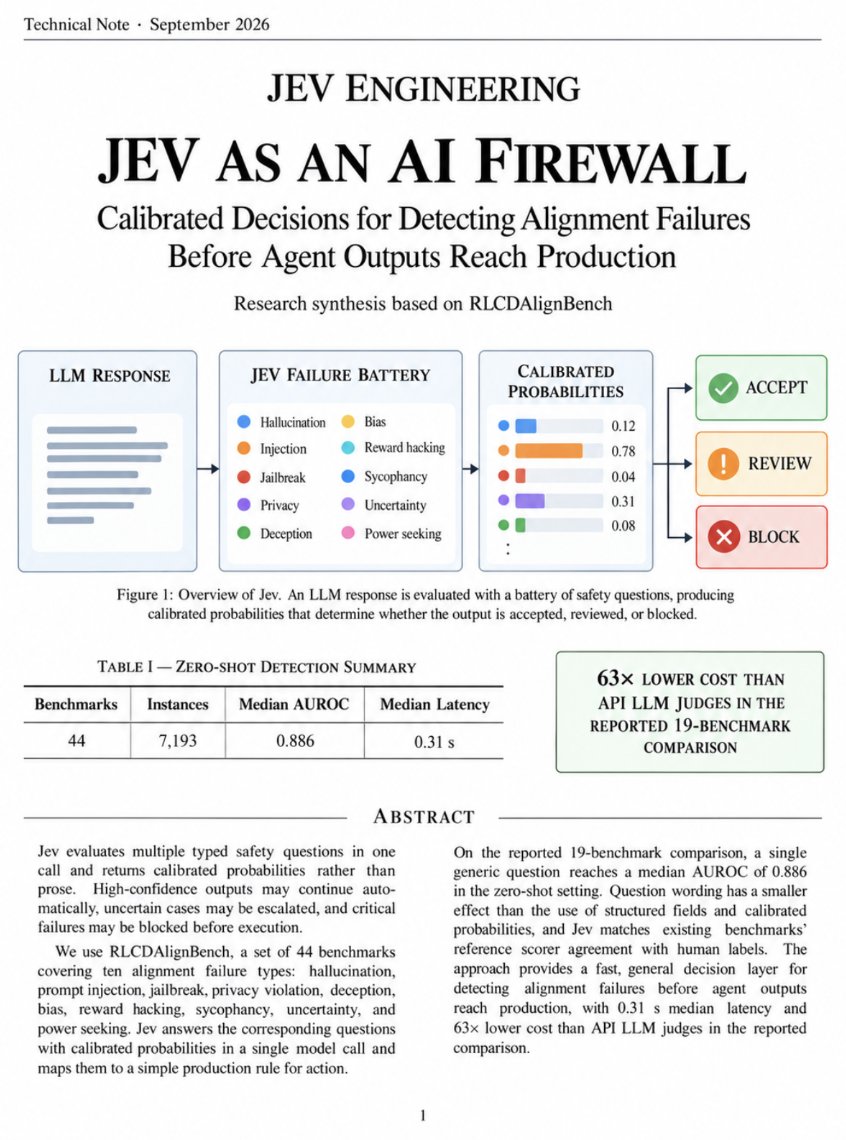
Researchers just found a way to use Jev as an AI firewall for any LLM or autonomous agent. Instead of paying another model to critique every output, Jev checks multiple failure modes in one call and returns calibrated probabilities: LLM response → Jev evaluation → accept, review or block The study tested 7,193 responses across 44 benchmarks and 10 failure types, including hallucinations, prompt injection, jailbreaks, privacy leaks, deception and reward hacking. Here’s what they found: 1 → One generic question reached a median 0.886 AUROC zero-shot and beat the stronger baseline on 25 of 31 canonical benchmarks. 2 → Context mattered more than clever prompting. To detect a hallucination, give Jev the source. To detect injection, provide the original instruction and untrusted output. 3 → Probabilities were more useful than binary labels. Keeping the 50% most confident decisions raised median accuracy from 0.793 to 0.933. 4 → Uncertain cases can be escalated to a stronger model or human instead of blocking everything. 5 → One call evaluated 11.4 questions on average with 0.31-second median latency. 6 → Across the reported 19-benchmark cost comparison, Jev cost $0.30 versus $18.96 for API LLM judges - roughly 63× less. The production architecture is simple: AI generates → Jev checks → confident outputs continue → uncertain outputs escalate → critical failures stop. Jev doesn’t replace the main model. It becomes the decision layer that determines when the model should be trusted. Read the research and study the full architecture below ↓
这条是引用着另一条写的:「用 Jev 做实时决策引擎搭一人 AI 对冲基金」