Qwen-Audio-Jev:用 CHOICE/NOUL/SCORE 做音频决策
在 Qwen-Audio-3.1 上加 Jev 决策头,统一选择、判断、打分三类输出,推理提速约 20 倍,覆盖音频筛查、声纹验证与质量评估。
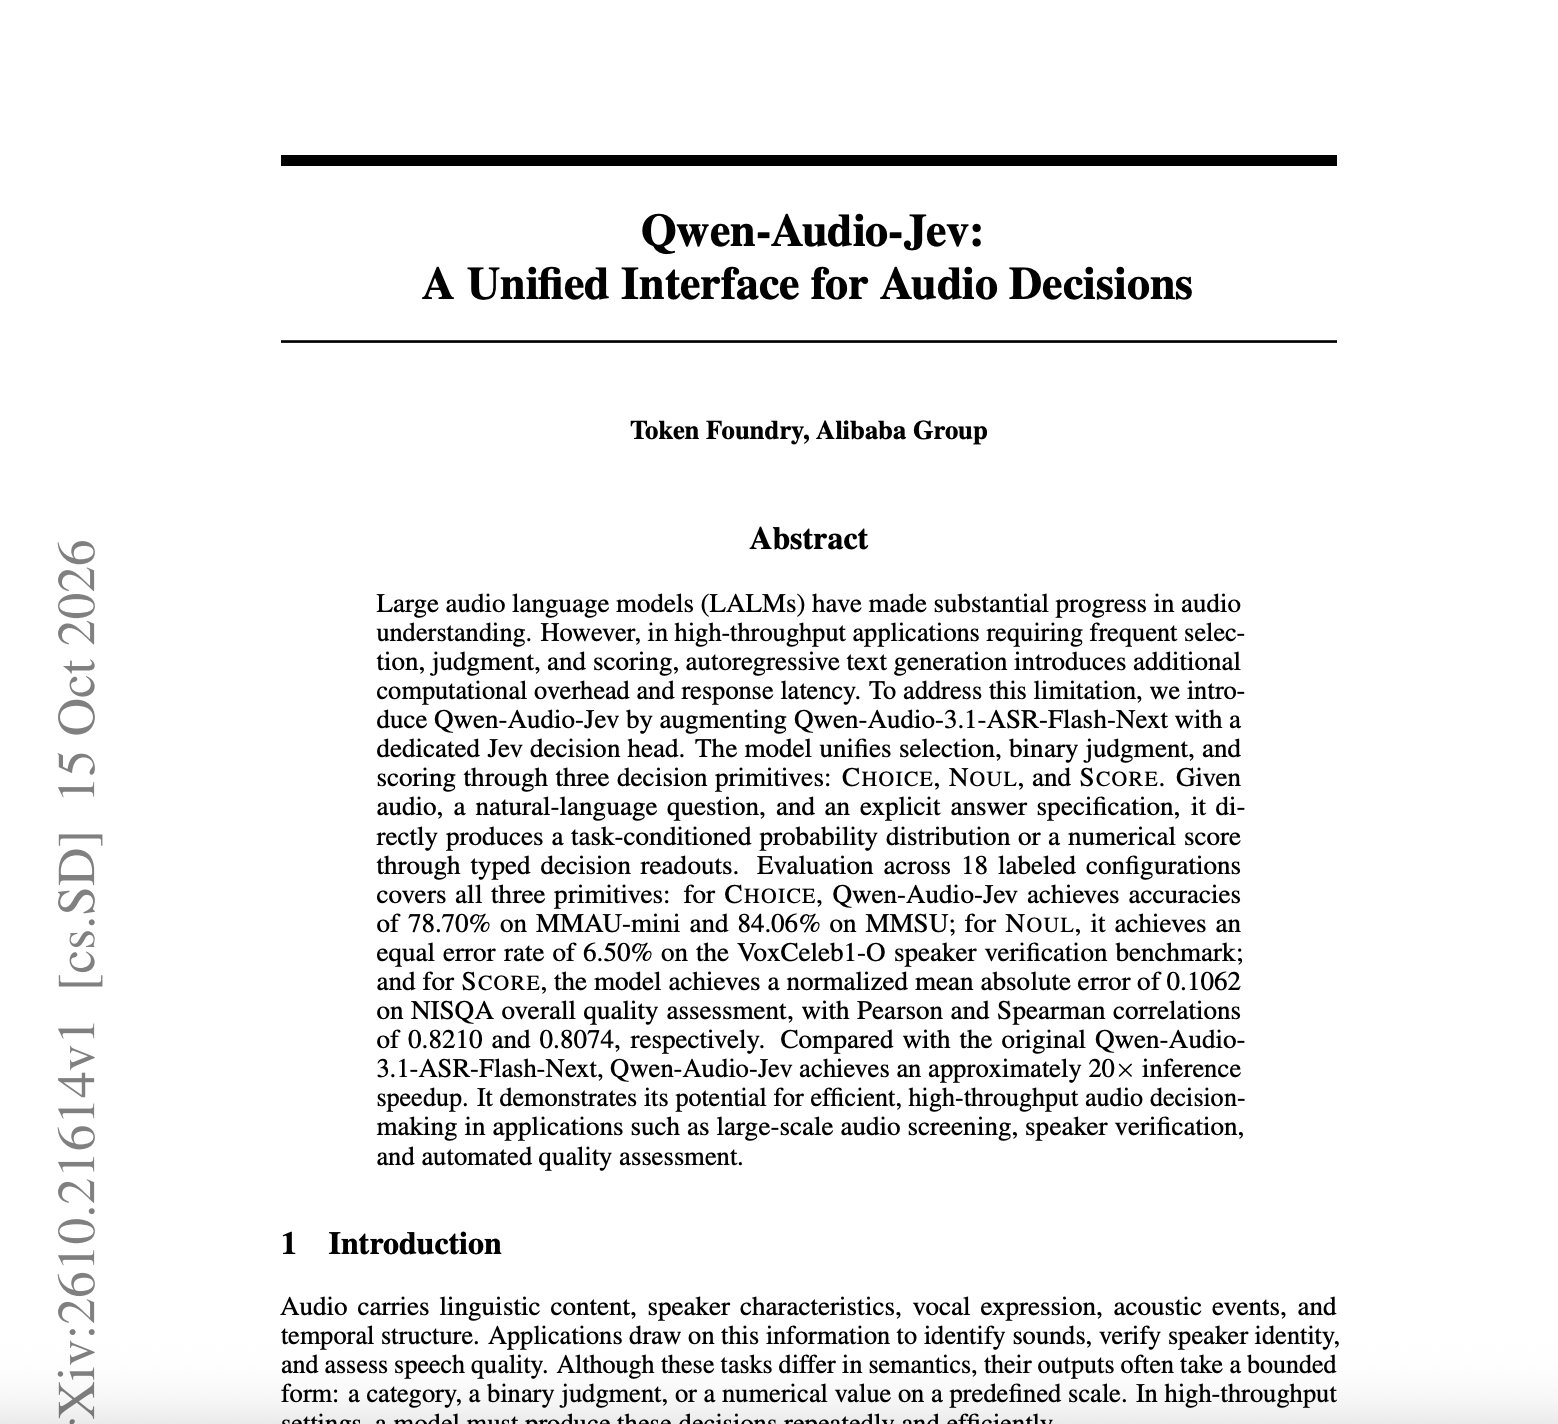
Jev use-cases are getting out of control and the latest one is to use it with an Audio Model! Qwen-Audio-Jev: A Unified Interface for Audio Decisions "Compared with the original Qwen-Audio-3.1-ASR-Flash-Next, Qwen-Audio-Jev achieves an approximately 20x inference speedup. It demonstrates its potential for efficient, high-throughput audio decision-making in applications such as large-scale audio screening, speaker verification, and automated quality assessment." Qwen-Audio-Jev is designed by augmenting Qwen-Audio-3.1-ASR-Flash-Next with a dedicated Jev decision head. The model unifies selection, binary judgment, and scoring through three decision primitives: CHOICE, NOUL, and SCORE. Given audio, a natural-language question, and an explicit answer specification, it directly produces a task-conditioned probability distribution or a numerical score through typed decision readouts. Evaluation across 18 labeled configurations covers all three primitives: for CHOICE, Qwen-Audio-Jev achieves accuracies of 78.70% on MMAU-mini and 84.06% on MMSU; for NOUL, it achieves an equal error rate of 6.50% on the VoxCeleb1-O speaker verification benchmark; and for SCORE, the model achieves a normalized mean absolute error of 0.1062 on NISQA overall quality assessment, with Pearson and Spearman correlations of 0.8210 and 0.8074, respectively. Paper link - https://arxiv.org/pdf/2610.21614v1