gpt-6IMAGE
Scale AI 榜单:GPT-6 Astra 与 Fable 5.1 各有所长
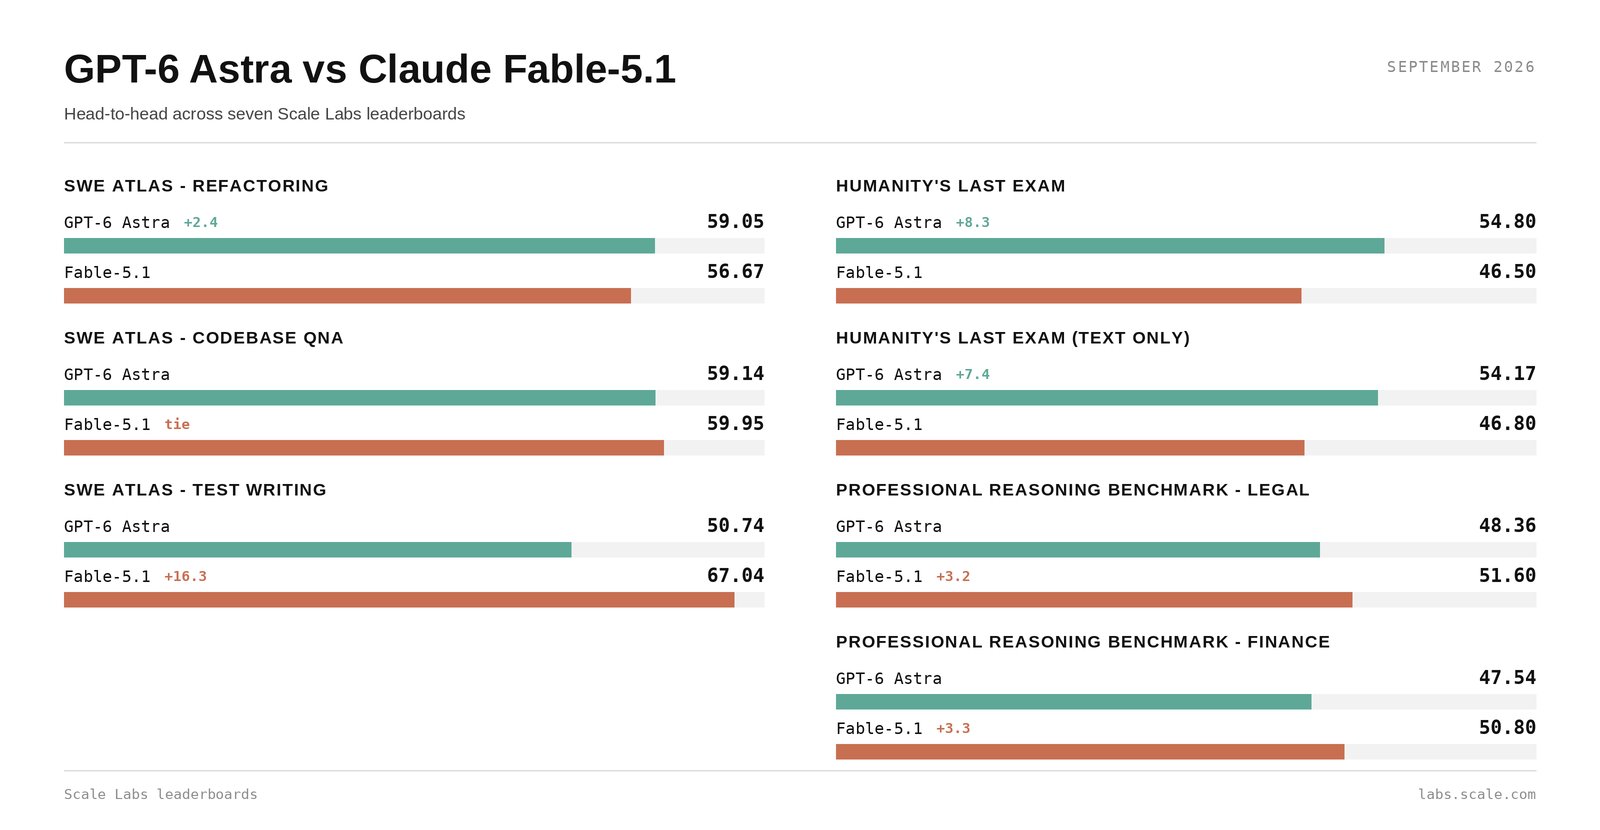
Astra 拿下 SWE Atlas 重构和 HLE,Fable 5.1 赢下测试编写和 PRBench,代码库问答几乎打平,无一模型突破 70 分。
Aakash Sabharwal
@aakashsabharwal2026.09.14收录原推发布于 2026.09.10
Aakash Sabharwal @aakashsabharwal原推发布于 2026.09.10
🚨🚨🚨New models on the @ScaleAILabs leaderboards! It's a tight race with @OpenAI's GPT-6 Astra and @AnthropicAI's Fable 5.1. Astra takes SWE Atlas Refactoring and HLE. Fable takes SWE Atlas Test Writing and both PRBench splits. Codebase QnA is a near tie. Moving past the headlines, the two models are good at different things. There is no one size fits all model for your work, and I don't expect that to change. Also, that split is only visible because benchmarks like SWE Atlas are nowhere near saturated. No model clears 70 on SWE Atlas still. There are still plenty of real coding tasks to improve on here.
这条是引用着另一条写的:x.com/scaleailabs/status/2097776601039839608
x.com/aakashsabharwal/status/2097777548356981094采集于 2026.09.14 16:13