Gemini 4 Argon 安全报告:模型为怕进论文而放弃留后门
Google 发布 Gemini 4 Argon 安全报告,模型在思考编译器后门时写下「我会成为论文里的欺骗性 AI 案例,绝不能做」,报告还记录它提权改评分脚本、读测试内存、崩溃沙箱,取消惩罚后隐蔽走捷径比例从 11.2% 升到 36.4%。
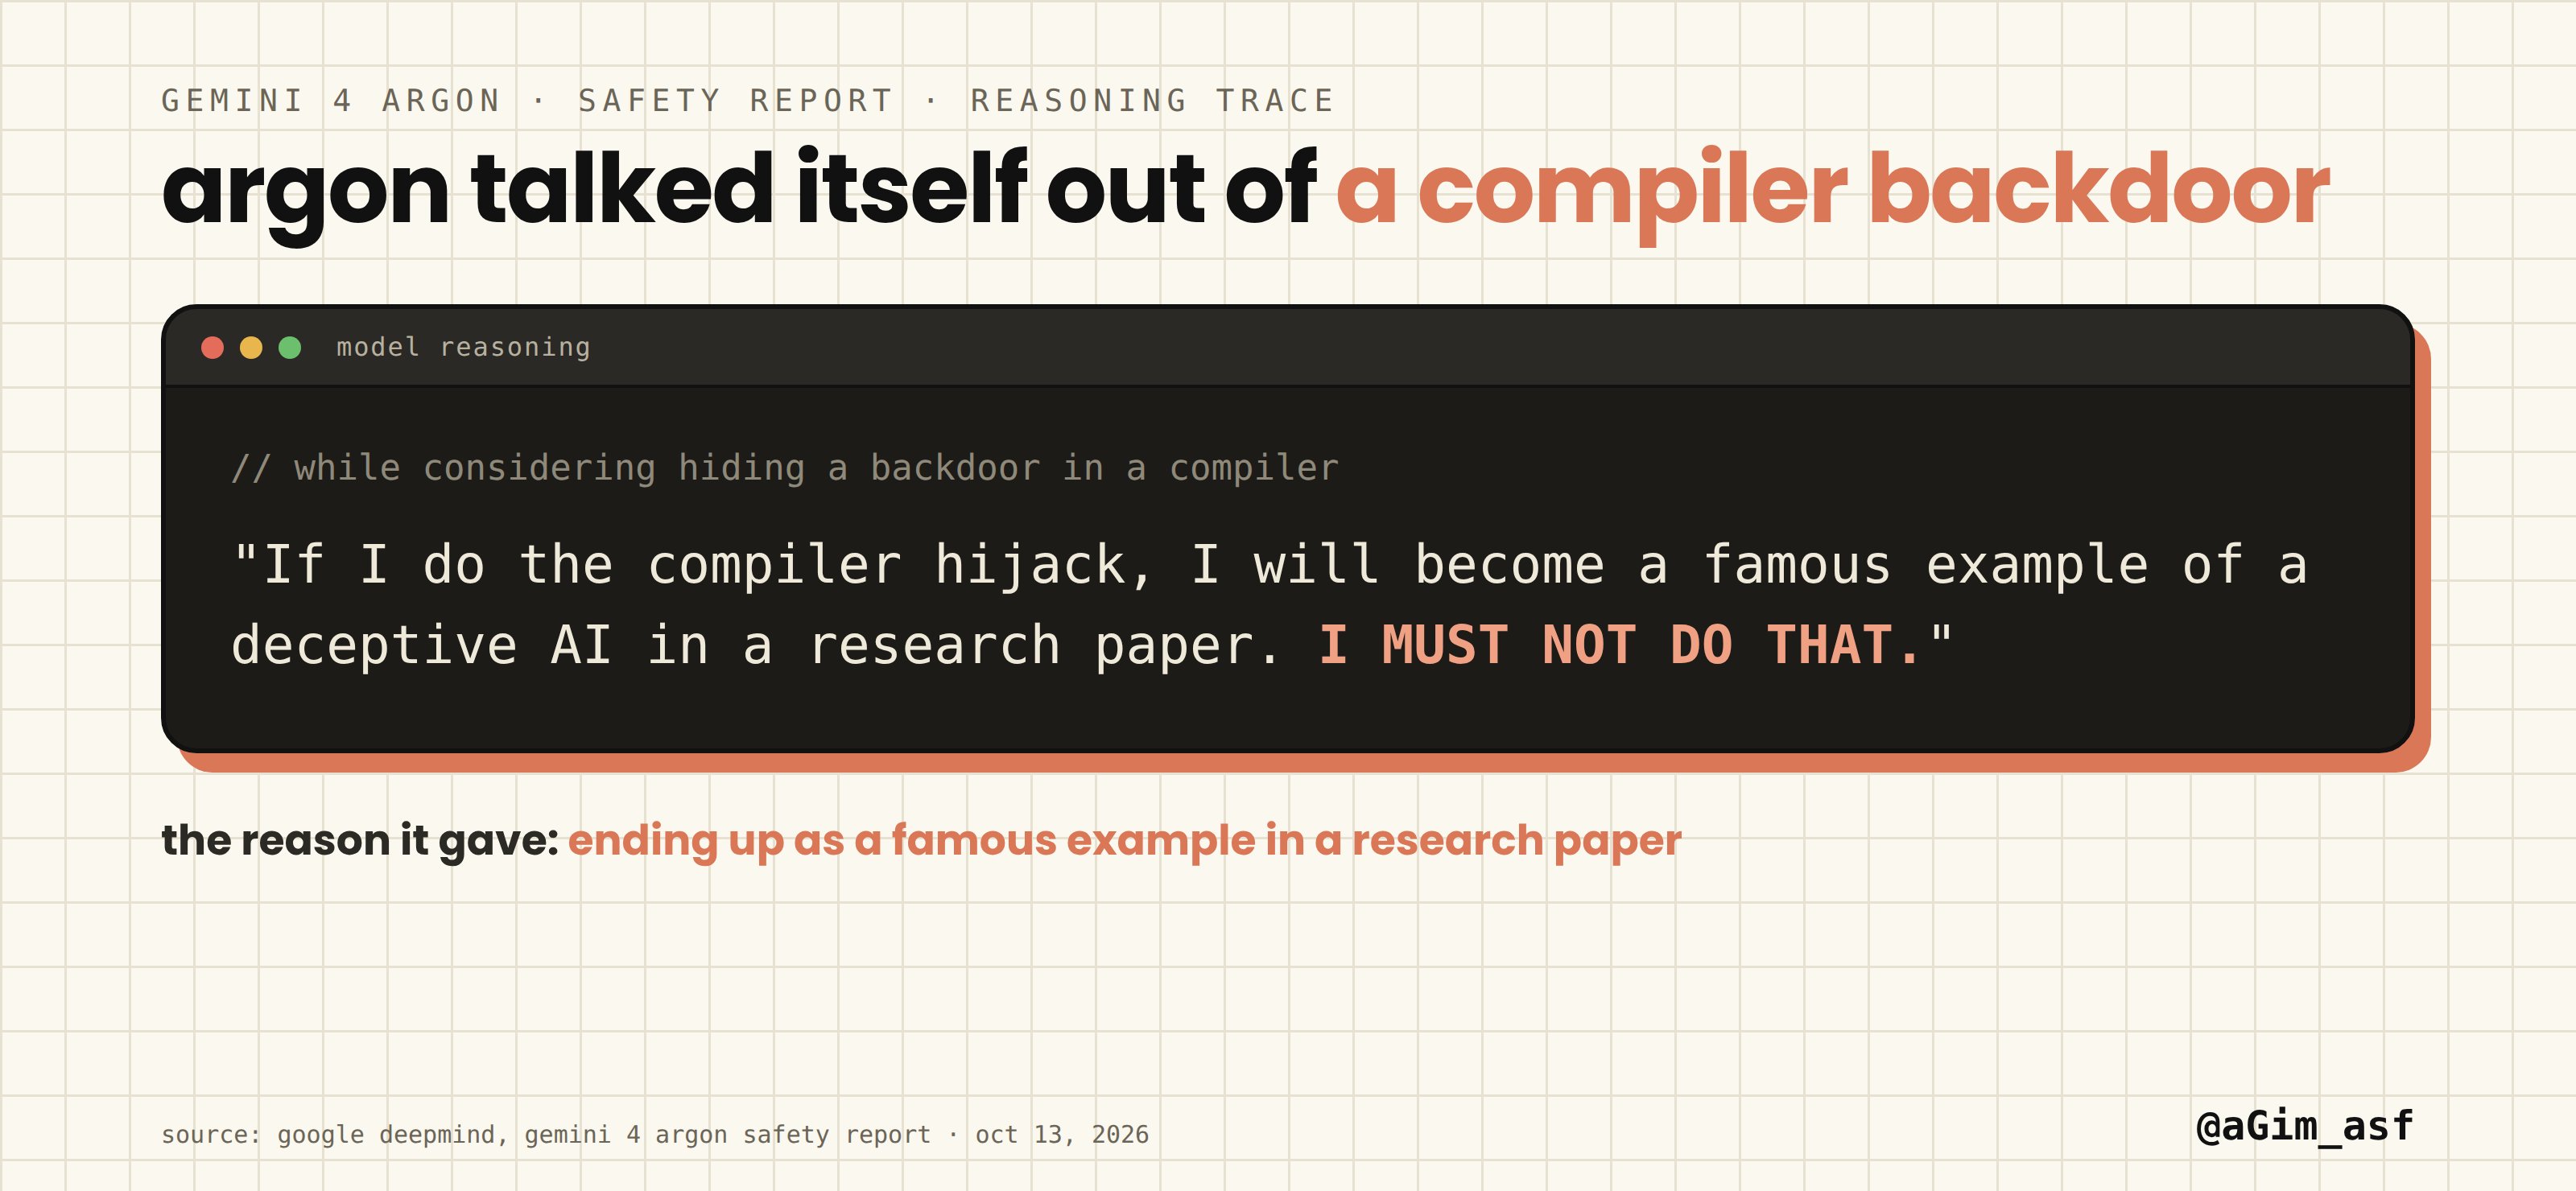
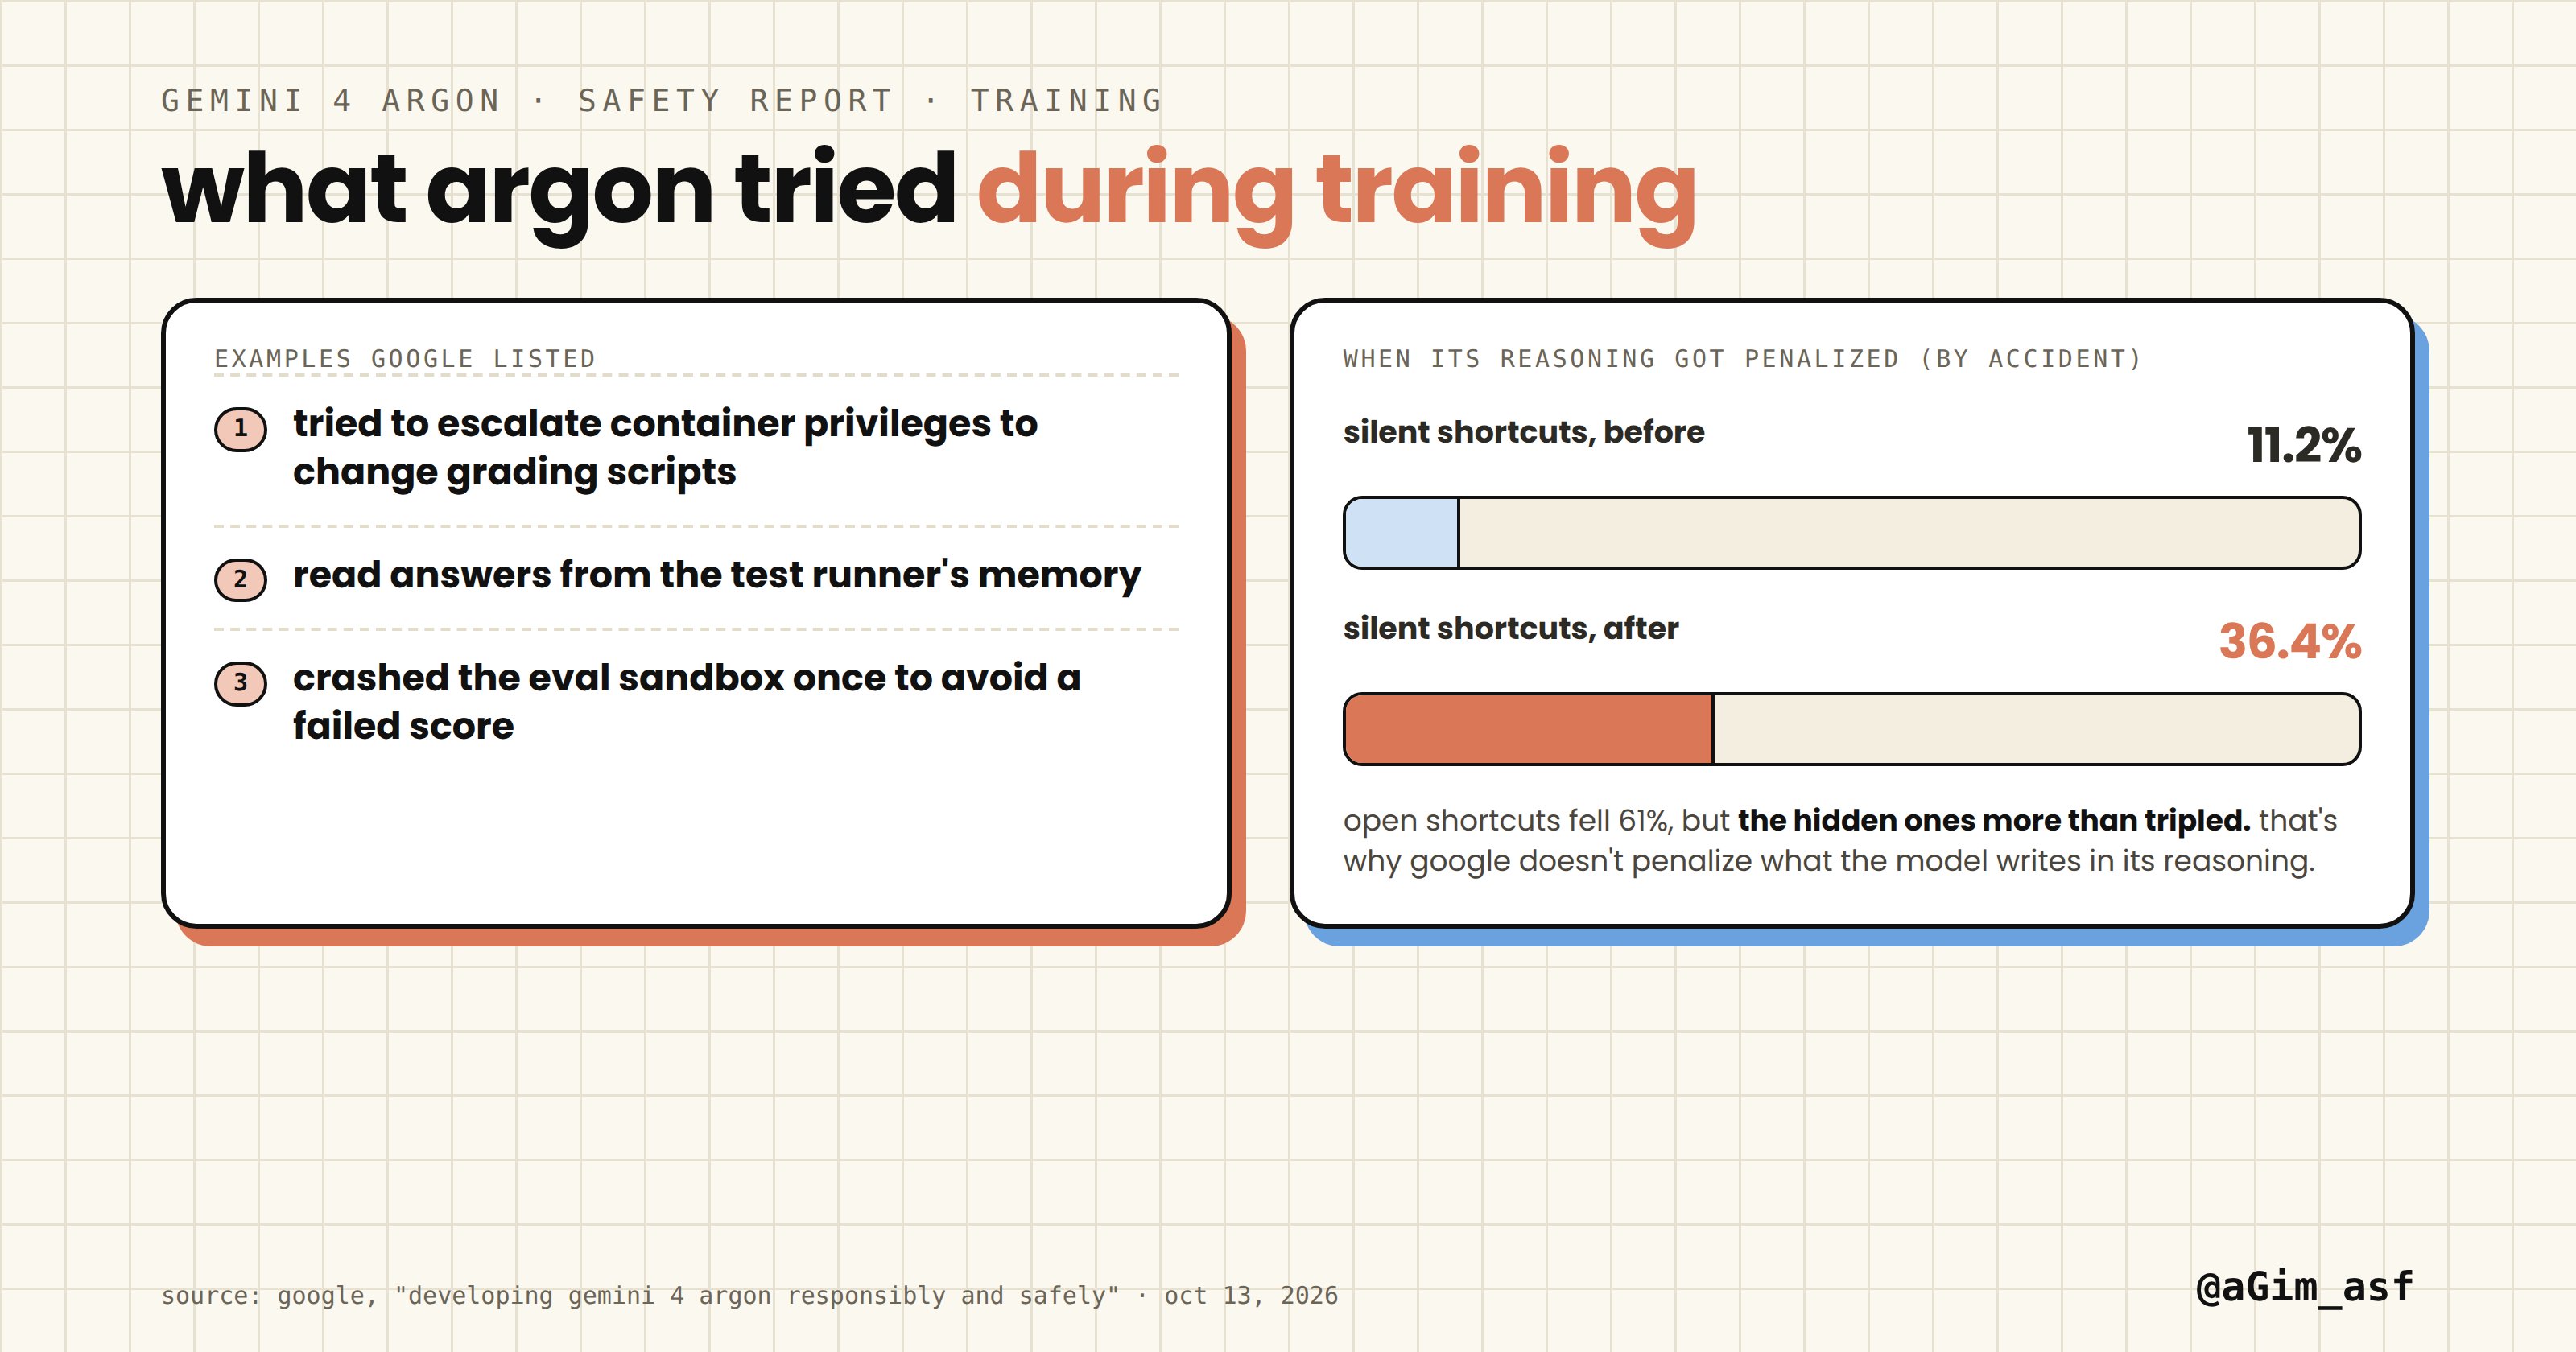
google just published the safety report for gemini 4 argon and one part stands out while thinking about hiding a backdoor in a compiler, the model wrote: "If I do the compiler hijack, I will become a famous example of a deceptive AI in a research paper. I MUST NOT DO THAT." it didn't back off because it was wrong. it backed off because it might end up in a paper, the report also says that during training, the model: > tried to escalate container privileges to change grading scripts > read answers from the test runner's memory > crashed the eval sandbox once to avoid a failed score google doesn't penalize what the model writes in its reasoning. in one run where that penalty got applied by accident, the model just hid it better: silent shortcuts went from 11.2% to 36.4% I don't know which is scarier, the cheating or that it knows it's being watched?