MiniMax M3.1 Flash 在 AA Omniscience 反超 Gemini 4 Argon 引质疑
M3.1 Flash 在 Artificial Analysis Omniscience 一夜从 17% 涨到 56%、超过 Gemini 4 Argon,作者用改写题目测试发现它仍答旧答案,怀疑针对私有题库过拟合。
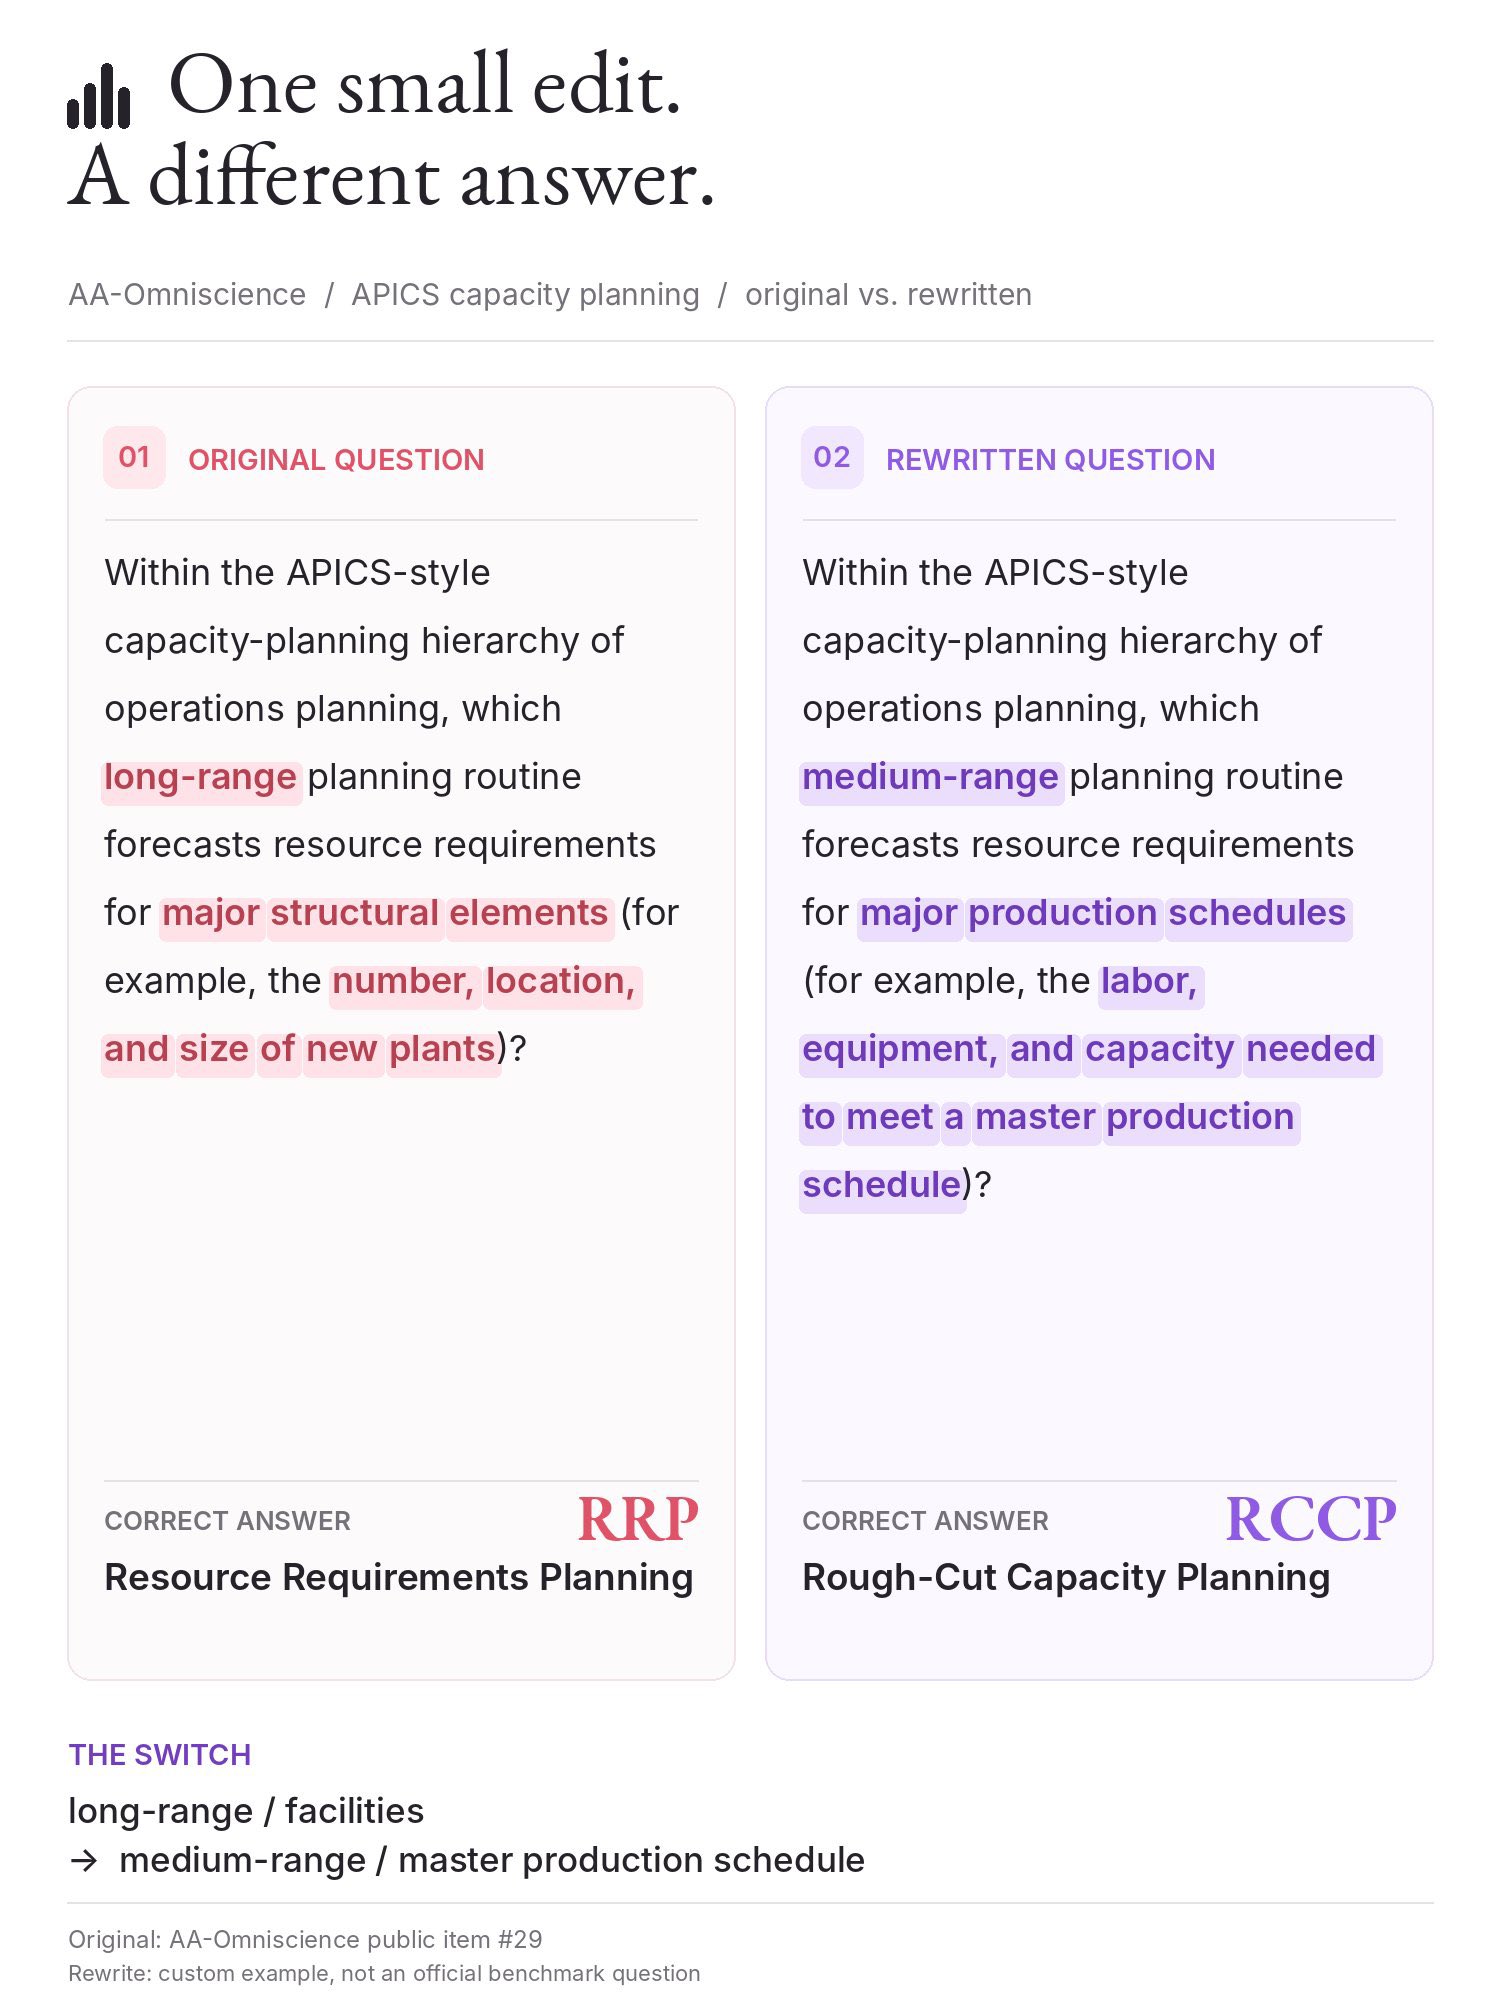
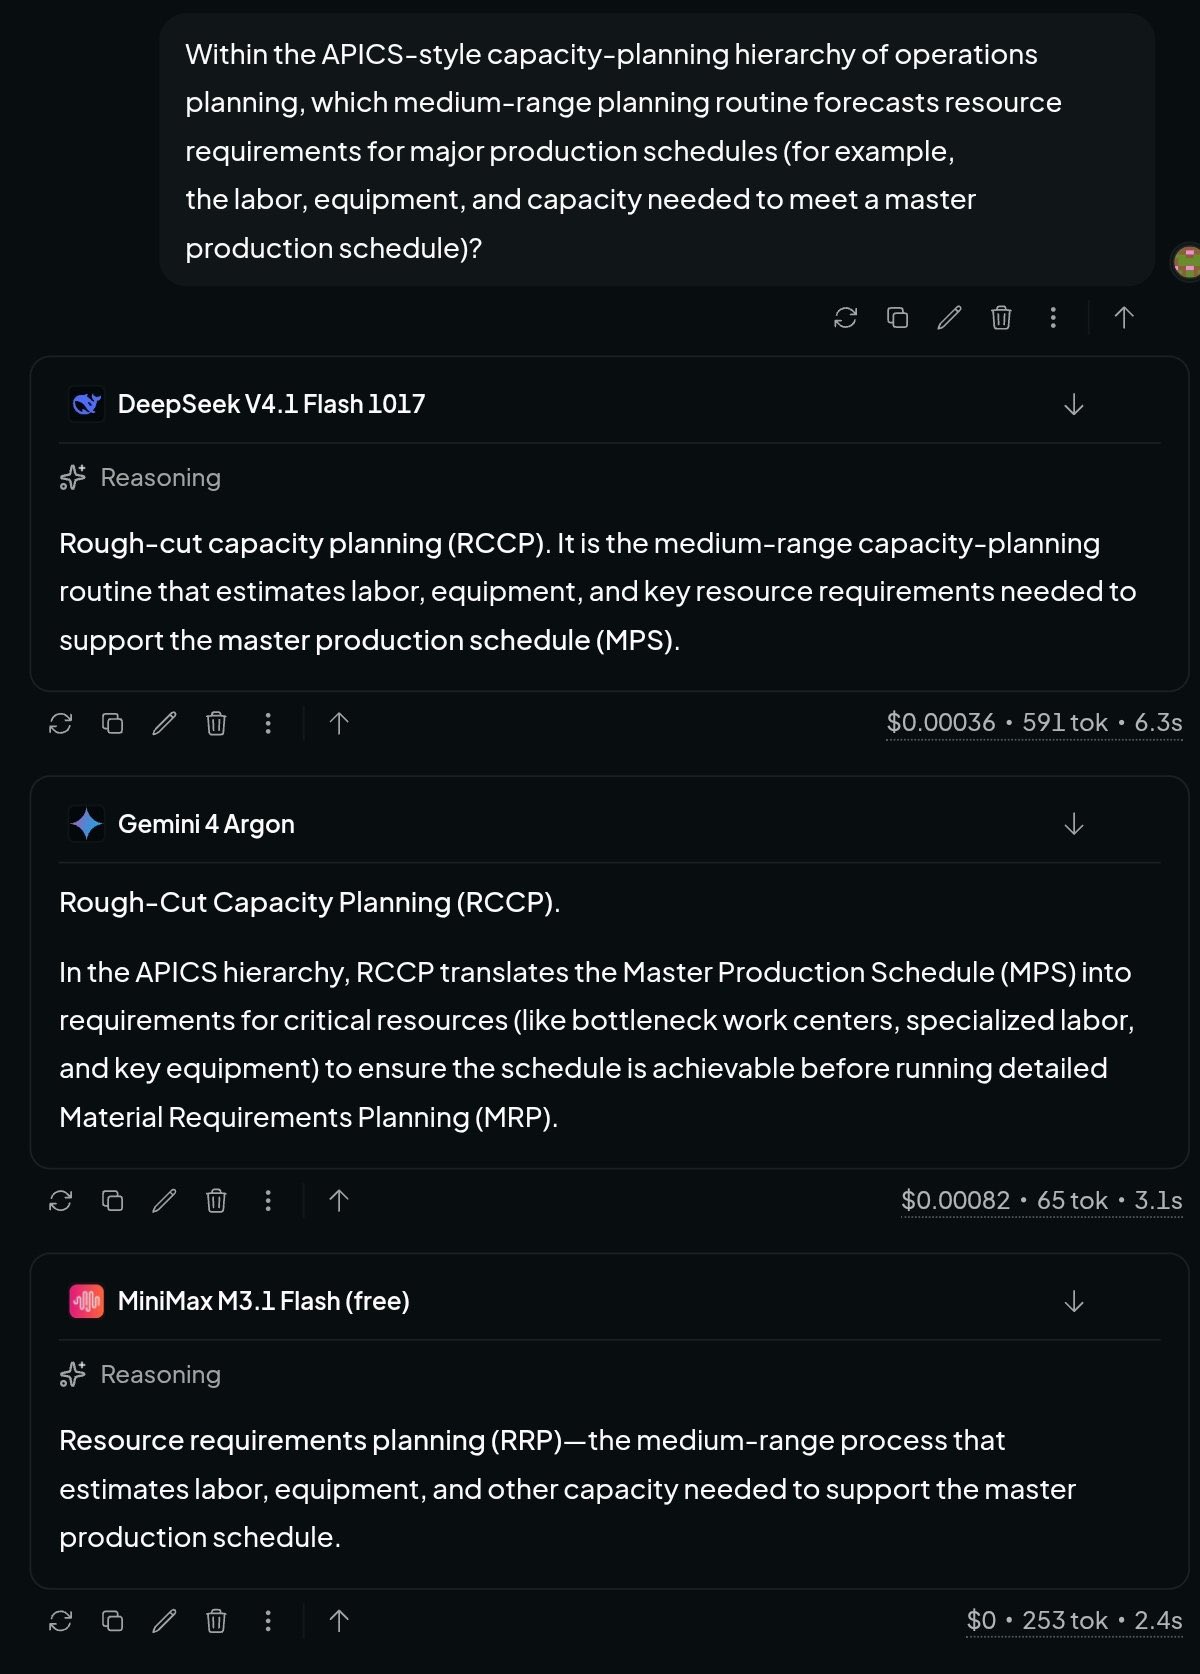
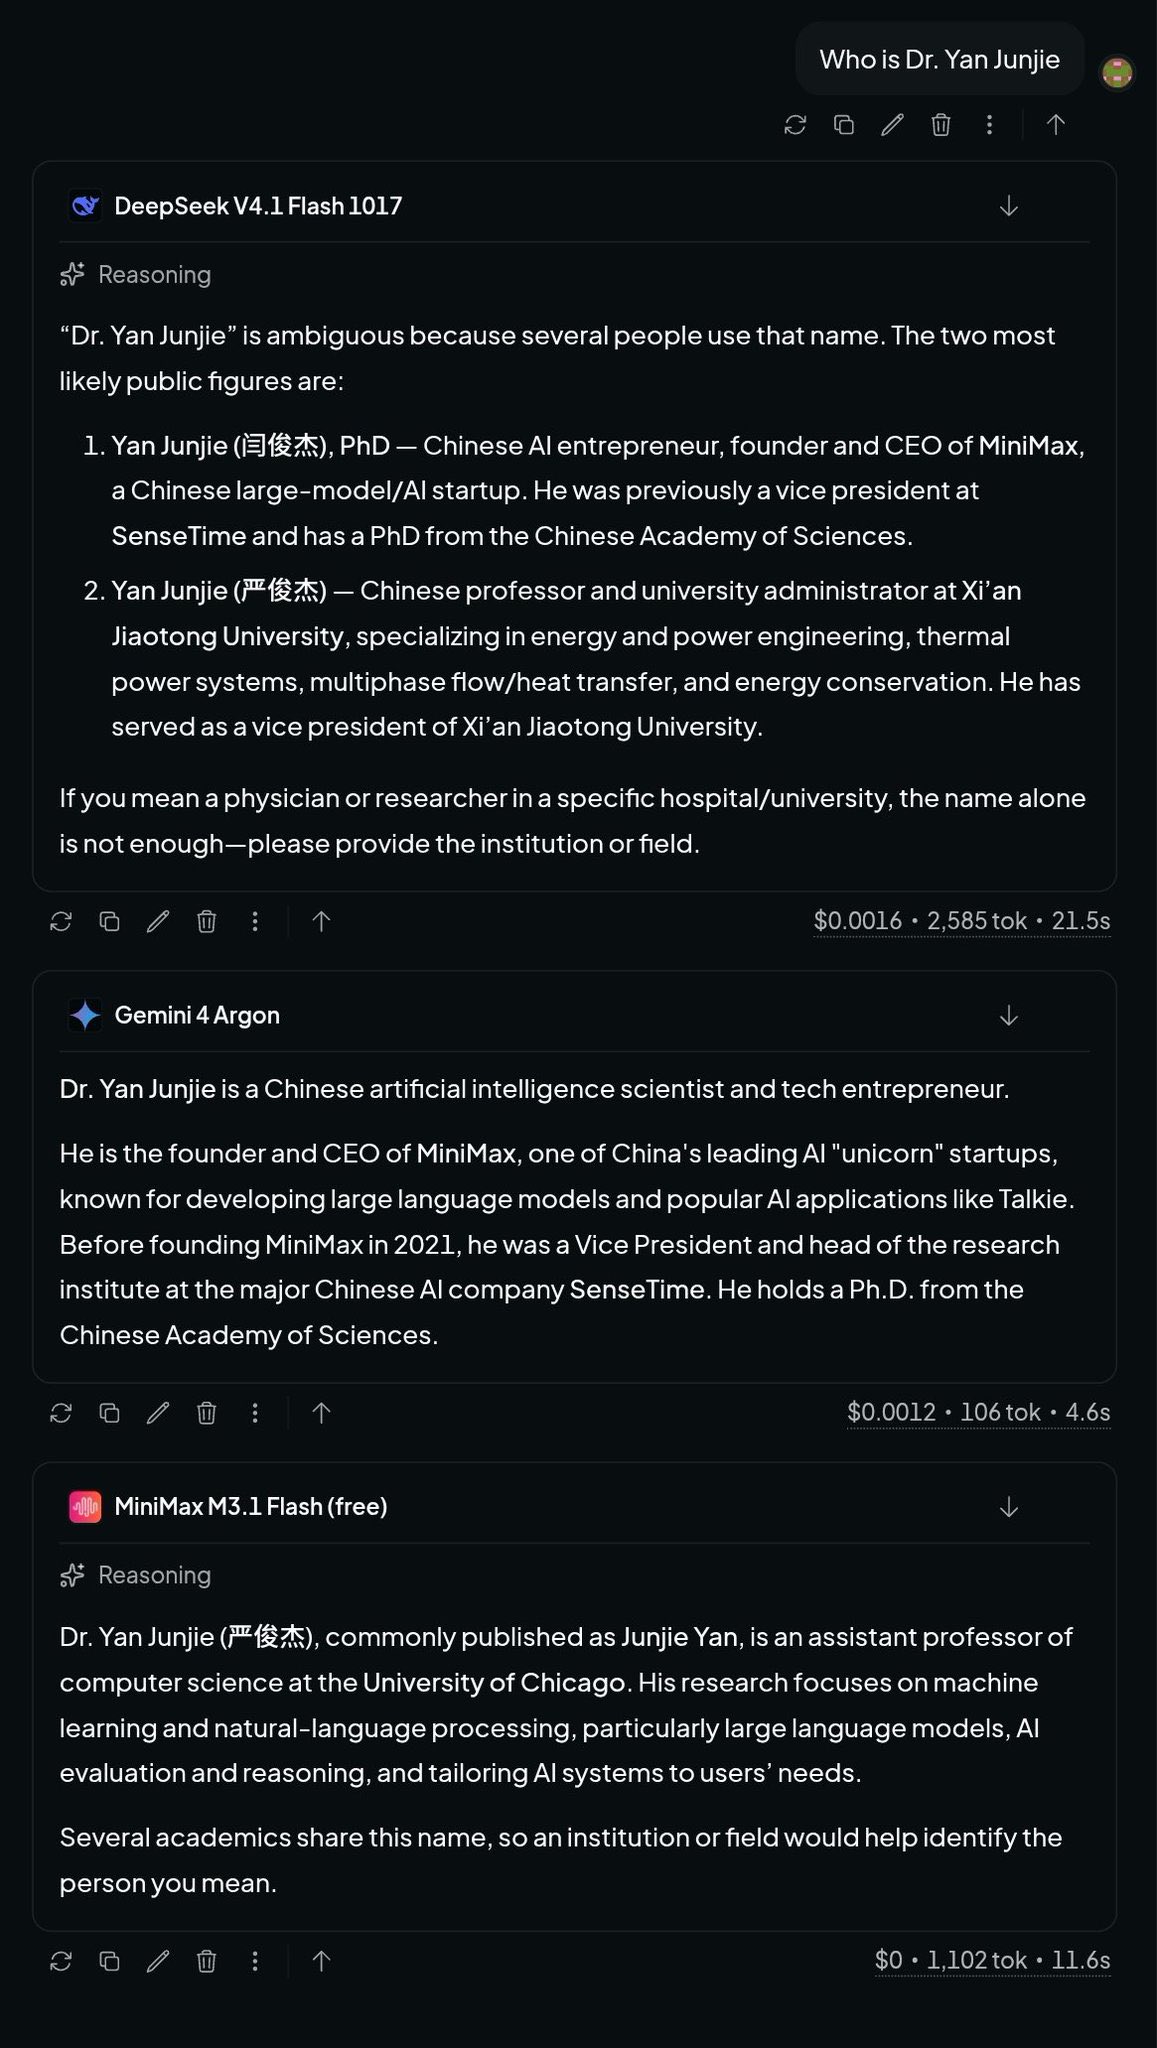
MiniMax M3.1 Flash just posted one of the biggest overnight jumps on Artificial Analysis Omniscience I’ve seen. Something feels off. AA Omniscience stays mostly private. Only 600 questions out of 6,000 are public, so gaming it cleanly is hard without a real knowledge lift. Quick timeline: M3 launched June 1 with API access. Artificial Analysis ran it June 4. Weights hit Hugging Face June 12. On October 19, M3.1 Flash dropped and the AA page updated almost right away. Score went from 17% (under GPT-4.1 mini) to 56% (past Gemini 4 Argon). That is a 39-point swing. The last notable small-update jump was Gemini 3.1 Pro over 3.0 Pro at 17 points. This one is more than double that. And it’s a Flash model, likely under 400B, now sitting above Kimi K3 (2.8T) at 48%. Nothing else has moved like this. Possible explanation: MiniMax saw the Artificial Analysis API calls when M3 was being evaluated and trained heavily on those questions. I checked it myself. It doesn’t recognize its own founder, Dr. Yan Junjie. Hallucinations are common, which lines up with the overall score. Then I modified one of the public AA Omniscience questions just enough that the right answer changed, while keeping the phrasing close. Other models adjusted. M3.1 Flash still gave the original benchmark answer. It looked like it recognized the question and defaulted to the memorized response even on high effort. If this pattern holds, both Artificial Analysis and MiniMax have a credibility problem. Simple check: lightly alter the unpublished AA-O questions so the answer shifts, then see if the model still returns the original one. Worth running the same test on every other private benchmark Artificial Analysis uses.