Meta Muse Wonder 在 KingBench 4 上落后 Astra 与 Opus
KingBench 4 排名:Opus 5.5 57.8%、GPT-6 Astra 56.5%、Sol 55.0%,Muse Wonder 仅 45.8%,且单任务成本高于 Astra 之外多数模型。
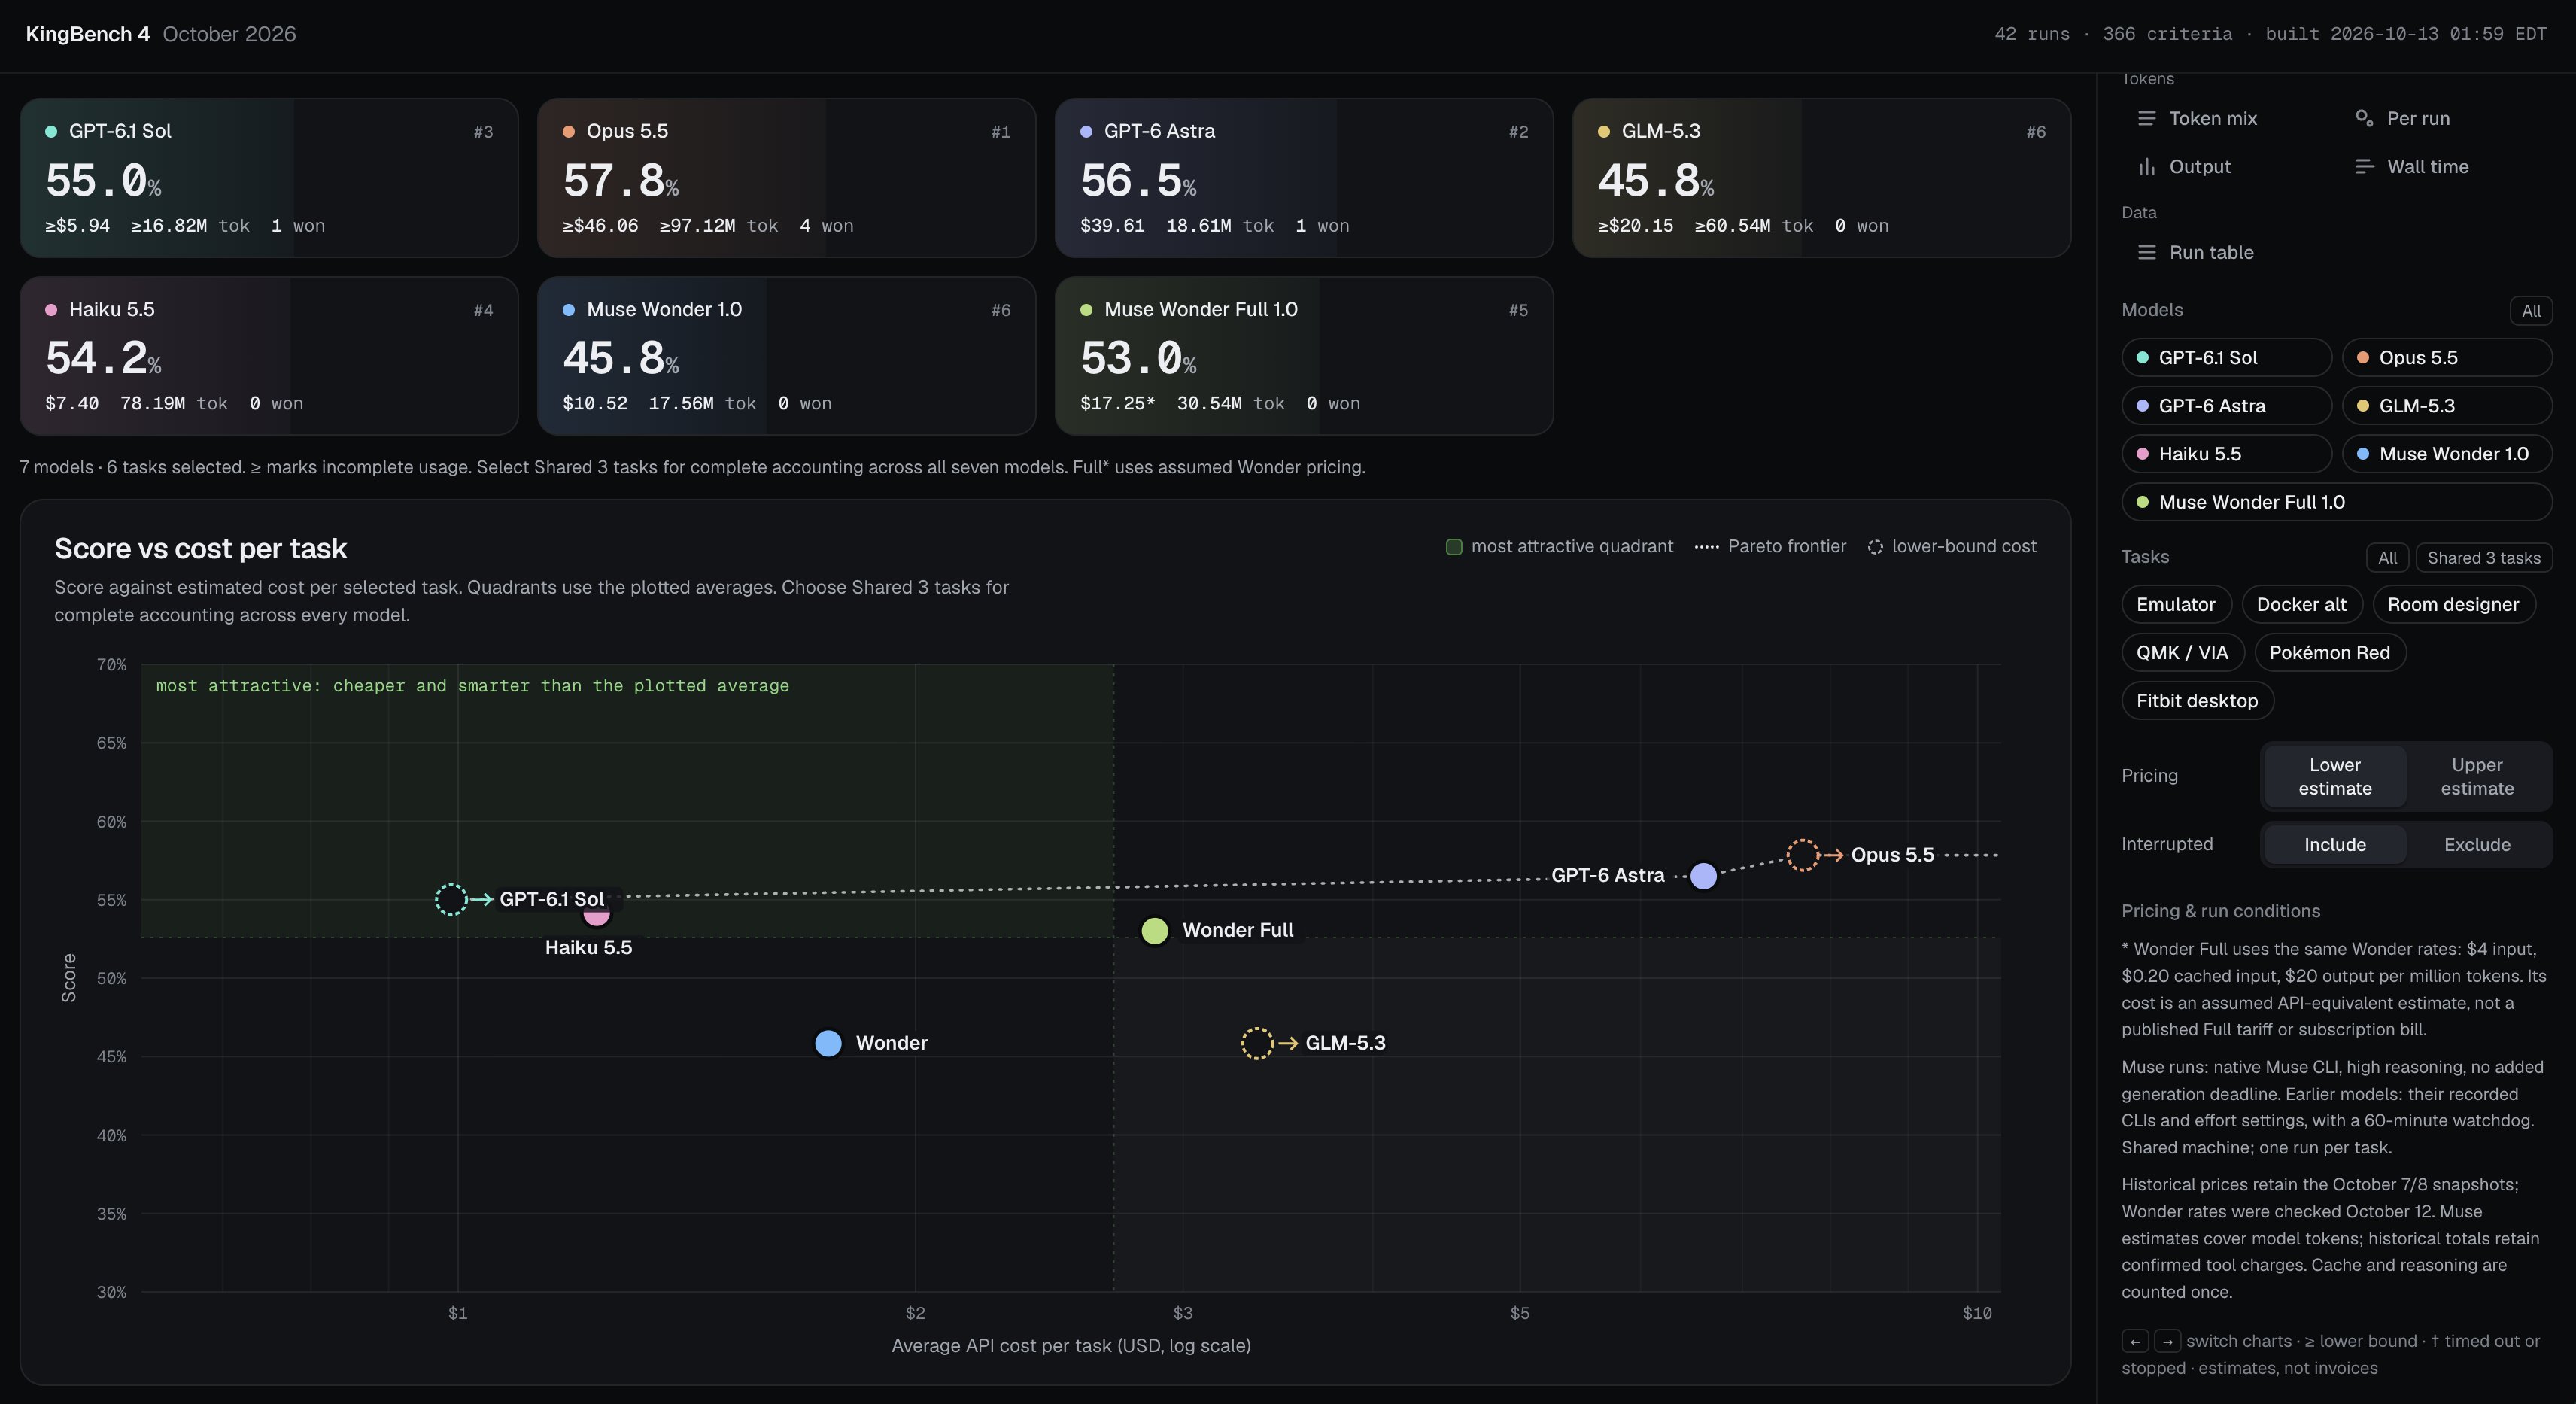
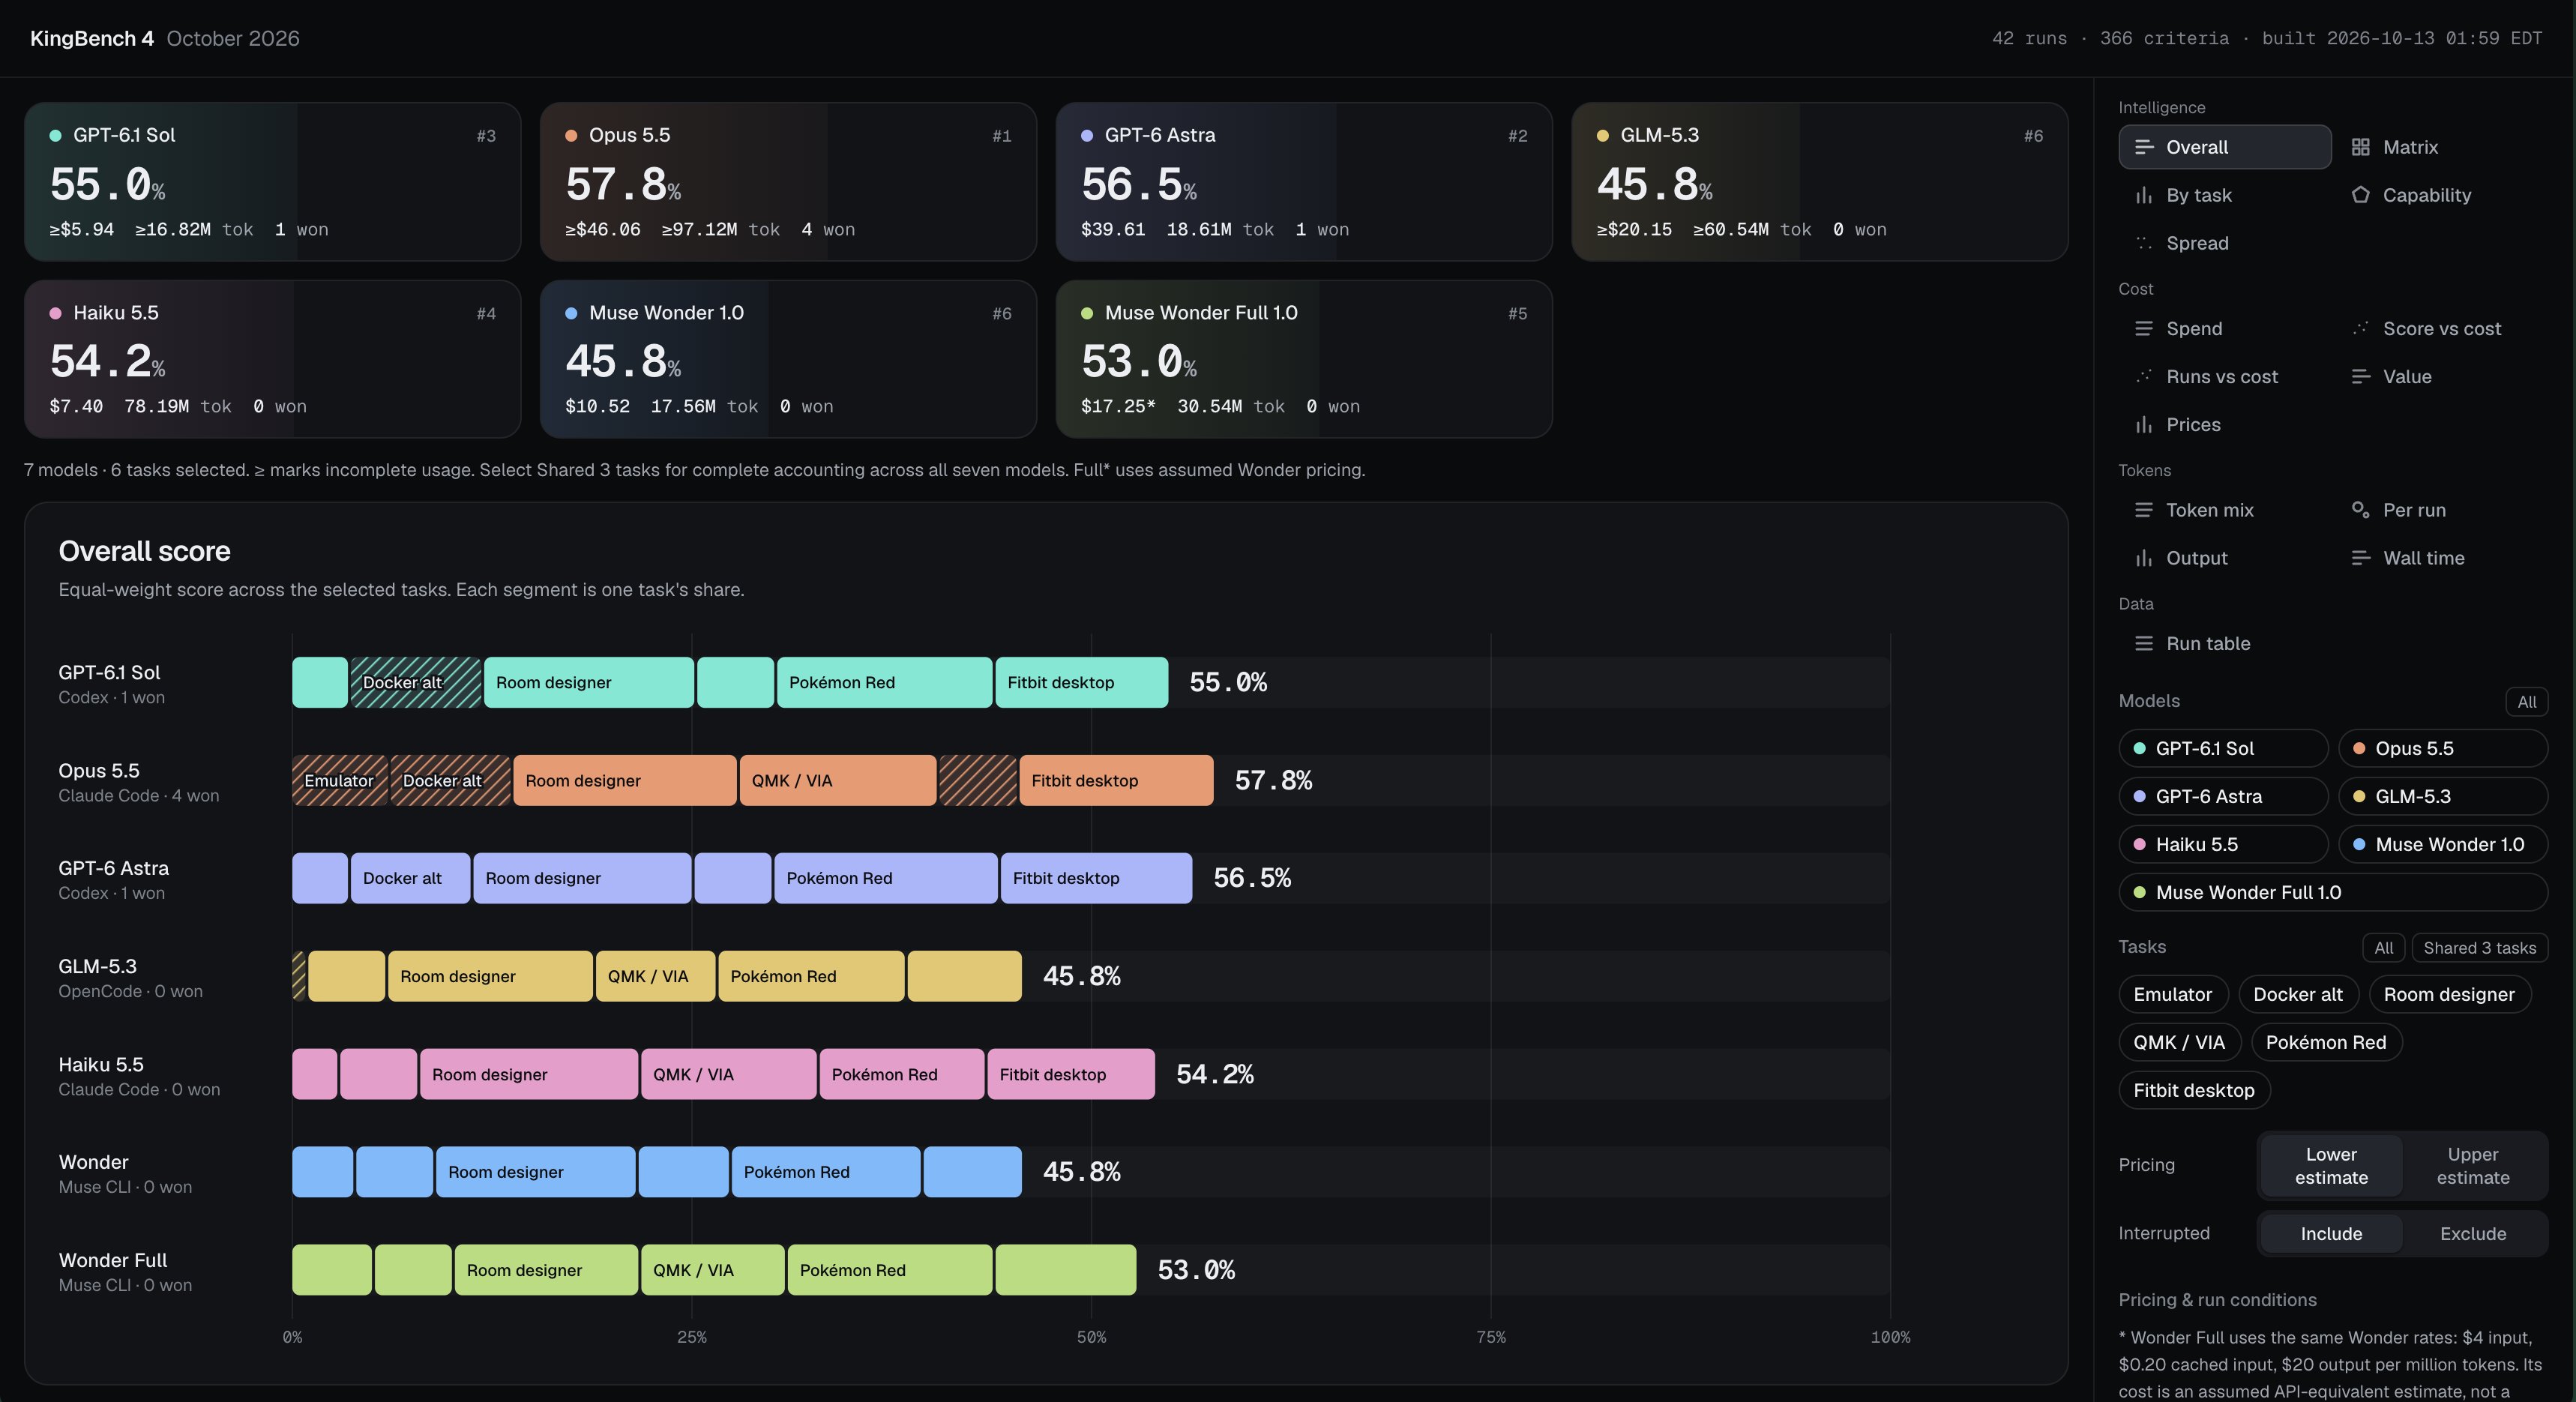
Muse Wonder & Wonder FULL by @AIatMeta on KingBench 4 Ranking: Opus 5.5 — 57.8% GPT-6 Astra — 56.5% GPT-6.1 Sol — 55.0% Haiku 5.5 — 54.2% Muse Wonder Full 1.0 — 53.0% Muse Wonder 1.0 and GLM-5.3 — 45.8% each, tied The models is not Opus 5.5 Level and is not token efficient at all. There are more downsides to the model than there are upsides. GPT-6.1 Sol still remains the king at being token efficient. Sol costs about $1 per task, Haiku costs about $1.23 per task, Wonder costs about $1.75 per task. Wonder Full costs about $2.87 per task Astra costs $6.6 and Opus 5.5 - $7.5 This price could have been very justified if the performance was on level with Opus or Astra but it is below Sol and Haiku. Wonder is on GLM-5.3 level while Wonderfull is short of Sol & Haiku. Wonder is really bad at complex prompts, developing fully featured apps unattended. The bench for context tests for 6 prompts that involve building a docker clone (VM), GBA, DS Emulation, Room Desigining Software, Pokemon Red reconstruction, QMK/VIA Compatible Keyboard Configurator and so on. The model is not acing any of these tests. The full test results will be available on the YT Video: https://www.youtube.com/watch?v=k3t3catymeM&pp=0gcJCTcMAYcqIYzv