用 Astra 分析 Codex 线程,拆解额度都花在哪
一位在 Astra 上花了约 5000 美元的开发者,用 Astra 分析自己的 Codex 线程,发现 70% 成本是缓存输入读取,并给出省额度实操建议。
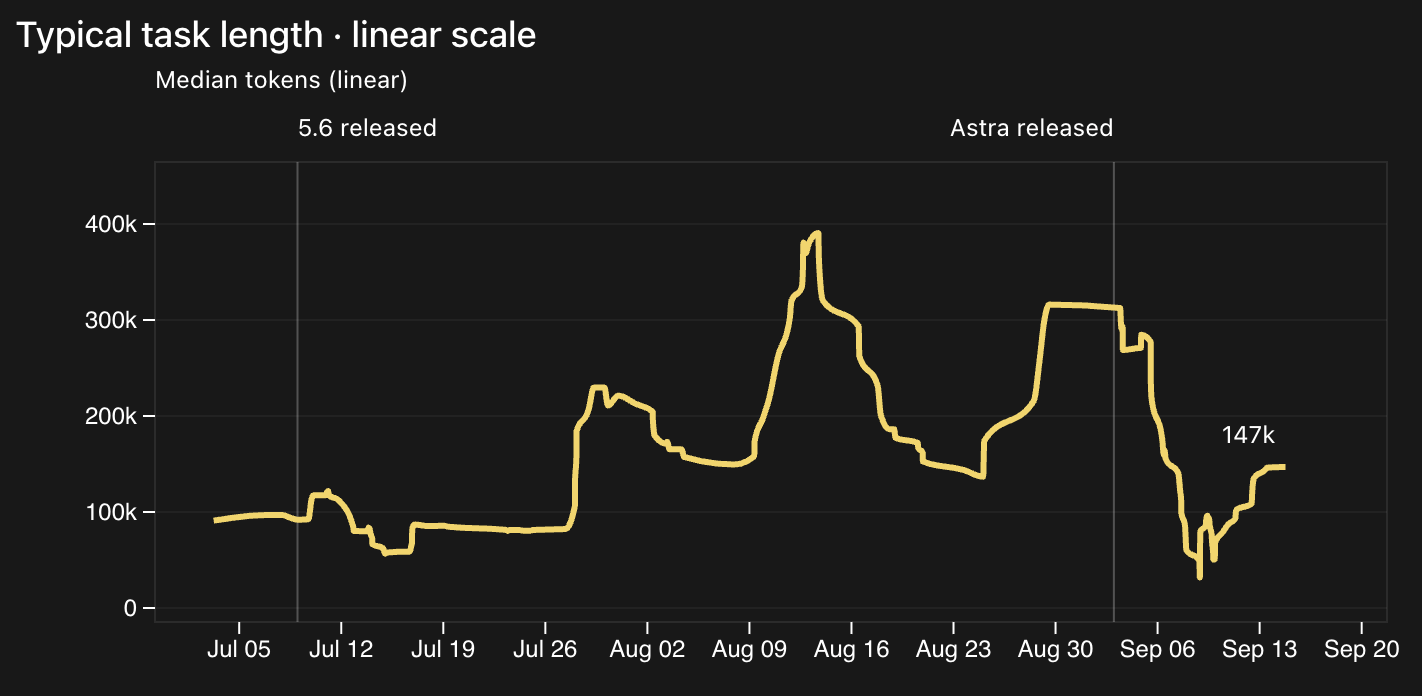
I had Astra analyze all my Codex threads and learned a lot about quota. Here's how to get the most Astra usage. (applicable to Fable too) I've spent ~$5000 on Astra since release*: - 70% is JUST cached input reads - 16% is uncached input - 13% is output - <1% is cache writes Till now, my Codex threads kept getting longer and longer, but Astra broke the trend (see chart). Long context is eating most of your quota. The biggest levers: - Smaller threads. New thread for each little task. Don't let context build up - Use smaller models that delegate coding tasks to Astra subagents. Don't let Astra see big outer thread - Avoid continuous polling. Have Astra set timers and wake back up for long-running tasks - Trim tokens wherever you can: skills/MCPs, AGENTS.md, custom instructions, etc - 3rd party tools like RTK that return more compact outputs might help (haven't tested this yet) Investigating that 70% input cost in more detail: - 40% is encrypted content (reasoning or other OpenAI stuff) - 20% is file reads - 10% is tool call arguments, schemas, etc - 7% is skills (catalog, loading instructions, output) - 5% is base instructions (system prompt, custom instructions, AGENTS.md) - 5% is browser/computer use input - 3% is command/tool output - The rest is minor or not actionable: compaction handoffs, assistant prose, user messages What you can do: - Use the lowest reasoning you can for your task, to cut CoT tokens - Make your repo as agent-friendly as possible. Small files/modules with clear folder structure, so Astra isn't grepping and reading large chunks. Try asking Astra to delegate file search tasks to subagents like Luna - Don't dump in tons of skills, instructions, AGENTS.md stuff; be intentional about it - Delegate browser/computer use to smaller models unless you need max performance And, probably goes without saying: - Don't use /goal with Astra. The few times I did absolutely obliterated my quota - /fast mode basically only if Tibo says he's resetting in an hour and you have 100% quota to burn Let me know if you have any observations to share! *I didn't literally drop $5k, this is mapping token to equivalent API prices