Jev 创始人 12 页 PDF:AI agent 验证层蓝图
Diogo Almeida 提出 10 步验证层方案,用 Choice/Score/Noul 把模糊评审变成类型化问题,在交付前拦住 agent 自我批准的坏结果。
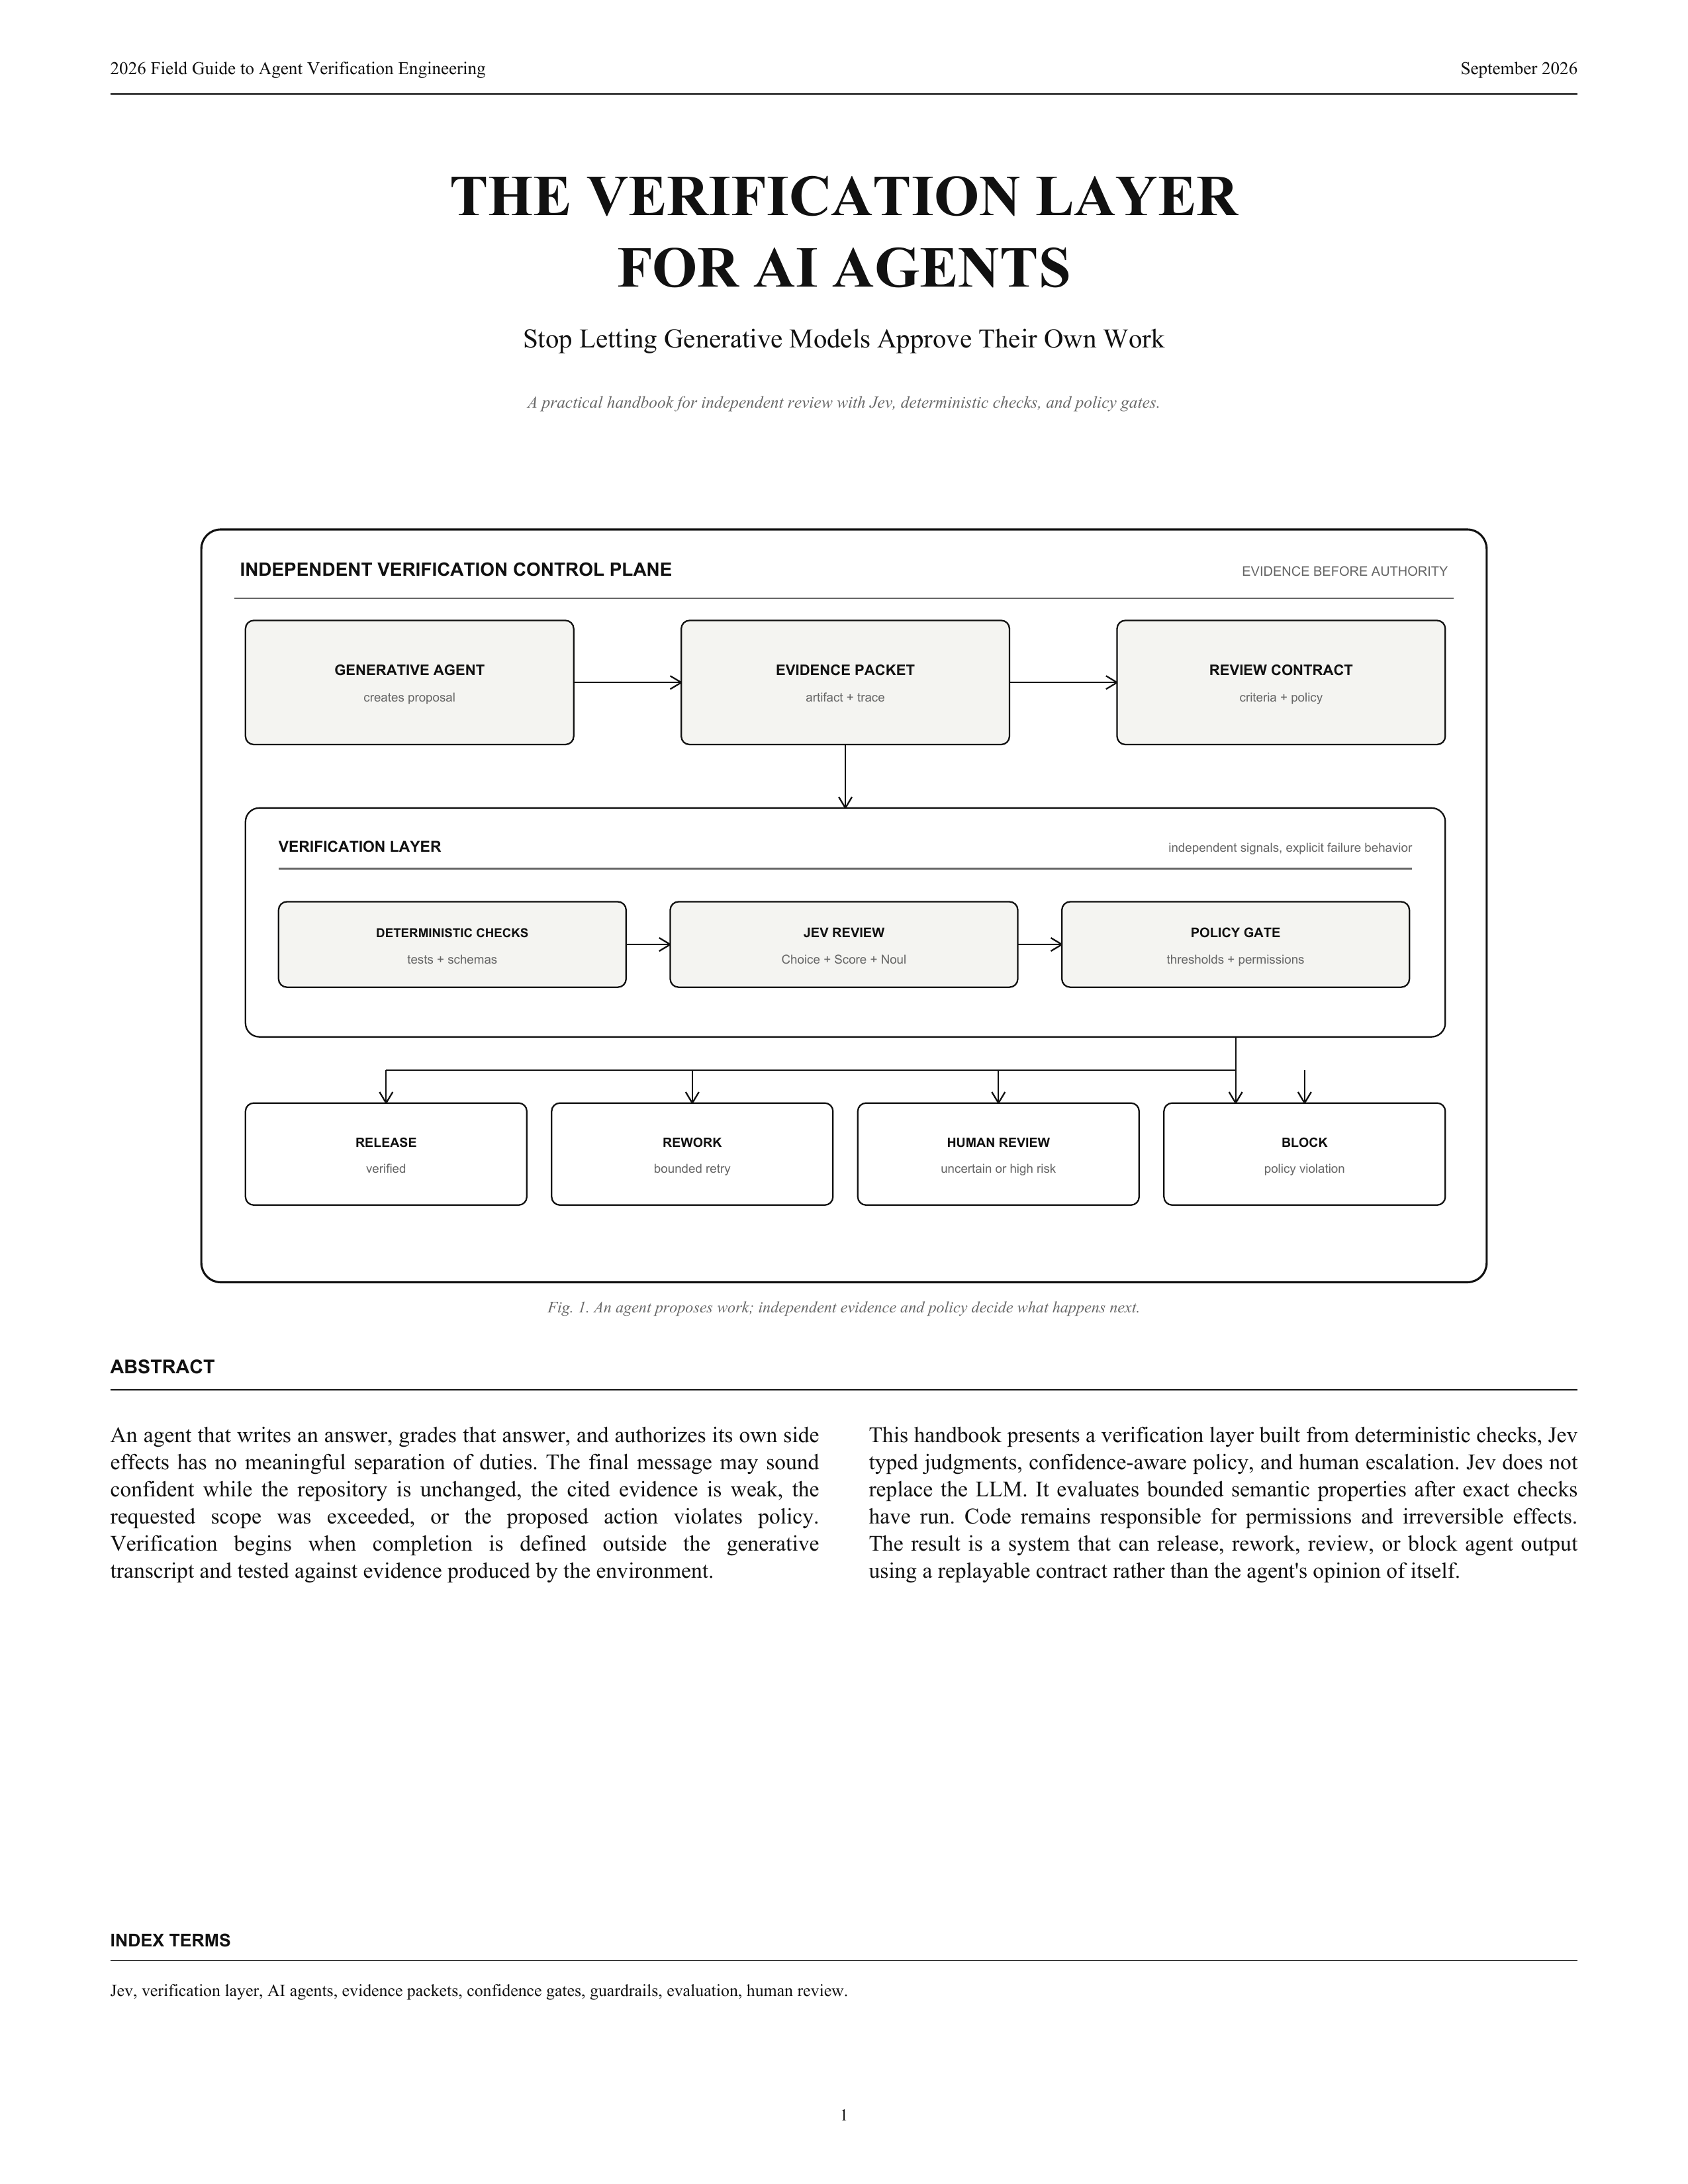
Jev Founder, Diogo Almeida, just released a 12-page PDF on building the Verification Layer for AI agents it explains why the most dangerous agent is not the one that fails it is the one that confidently approves its own broken work this is a 10-step blueprint on how to catch bad outputs before they ship - without paying another LLM to reread the entire task: step 1 → eliminate self-approval: the LLM creates the work, Jev reviews bounded semantic properties and deterministic code retains authority step 2 → write the verification contract before generation: define the expected artifact, allowed scope, required evidence, risk class and approval owner step 3 → build an evidence packet: bind the artifact to test results, sources, tool receipts, policy versions and timestamps instead of trusting the agent’s final message step 4 → run deterministic checks first: schemas, permissions, file boundaries, tests, numerical limits and allowlists should fail before semantic review begins step 5 → turn vague review prompts into typed questions: use Choice for defect categories, Score for completion rubrics and Noul for evidence-support probabilities step 6 → verify three dimensions separately: did the agent complete the task, does the evidence support the result and did the work remain inside the requested scope? step 7 → gate autonomy by confidence and consequence: high-confidence low-risk work can proceed, uncertain cases gather more evidence and consequential actions require review step 8 → make rework finite: return the failed criterion, relevant evidence and permitted correction scope instead of asking the agent to reconsider everything step 9 → record a decision receipt: contract version, artifact digest, state, questions, probabilities, thresholds, outcome, override and verified result step 10 → make the agent earn autonomy: begin with offline replay, move to shadow mode, assist human reviewers and automate only a measured low-risk slice most builders try to improve agents by giving them larger models, longer prompts and more tools this guide improves them by making every consequential output earn the right to ship this 12-page PDF is more useful than most paid AI-agent courses because it gives you the actual control architecture: agent → evidence → deterministic checks → Jev review → policy gate → release / rework / human review / block the result: fewer confidently broken outputs, smaller reviewer prompts, bounded retry loops and a complete explanation of why every agent action was approved Send this PDF and the original Jev article to Claude Code or Codex and tell it to build the Verification Layer before your agent ships its next task ↓
这条是引用着另一条写的:「Jev 把路由打分验证做成决策层」