Terminal-Bench-Science 榜单:GPT-6 Sol 与 Opus 5.5 提升
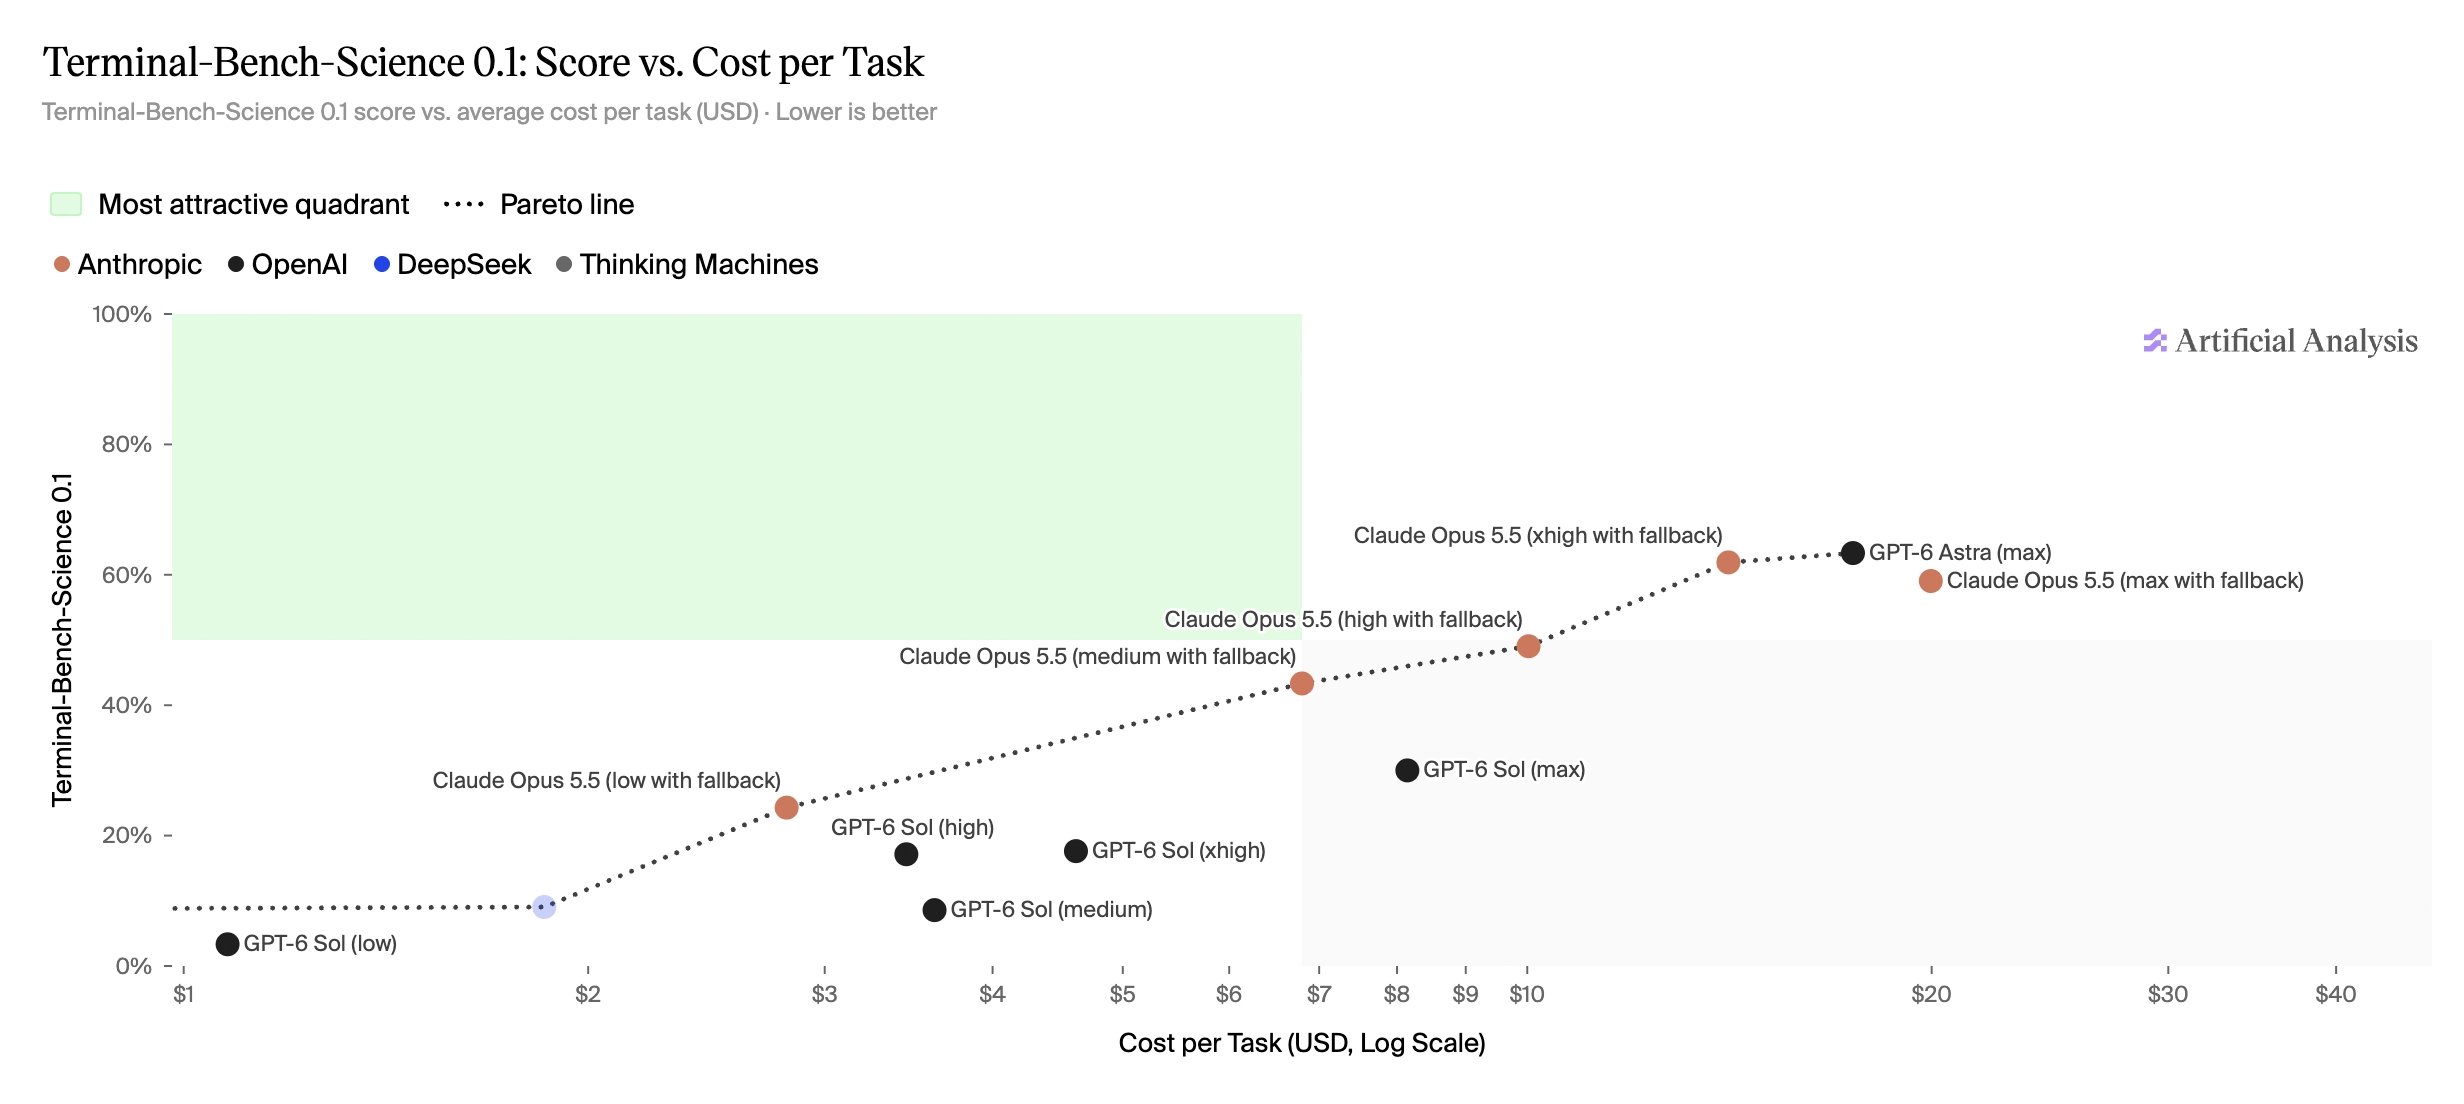
Artificial Analysis 称 GPT-6 Astra 与 Claude Opus 5.5 领先约 20 分,同家族中 Sol 与 Opus 5.5 提分且单任务成本下降。
Recent releases from OpenAI and Anthropic lead other models by a wide margin on Terminal-Bench-Science. GPT-6 Astra and Claude Opus 5.5 have a ~20-point lead over Fable 5.1 in our testing. The best-performing model we’ve evaluated so far outside of these labs is Qwen3.8 Max (0902) at 12%. Within the same model families, the most recent GPT and Claude model releases made large gains. Comparing max effort, GPT-6 Sol and Opus 5.5 both saw performance improvements on the dataset while also reducing cost per task compared to GPT-5.6 Sol and Opus 5.
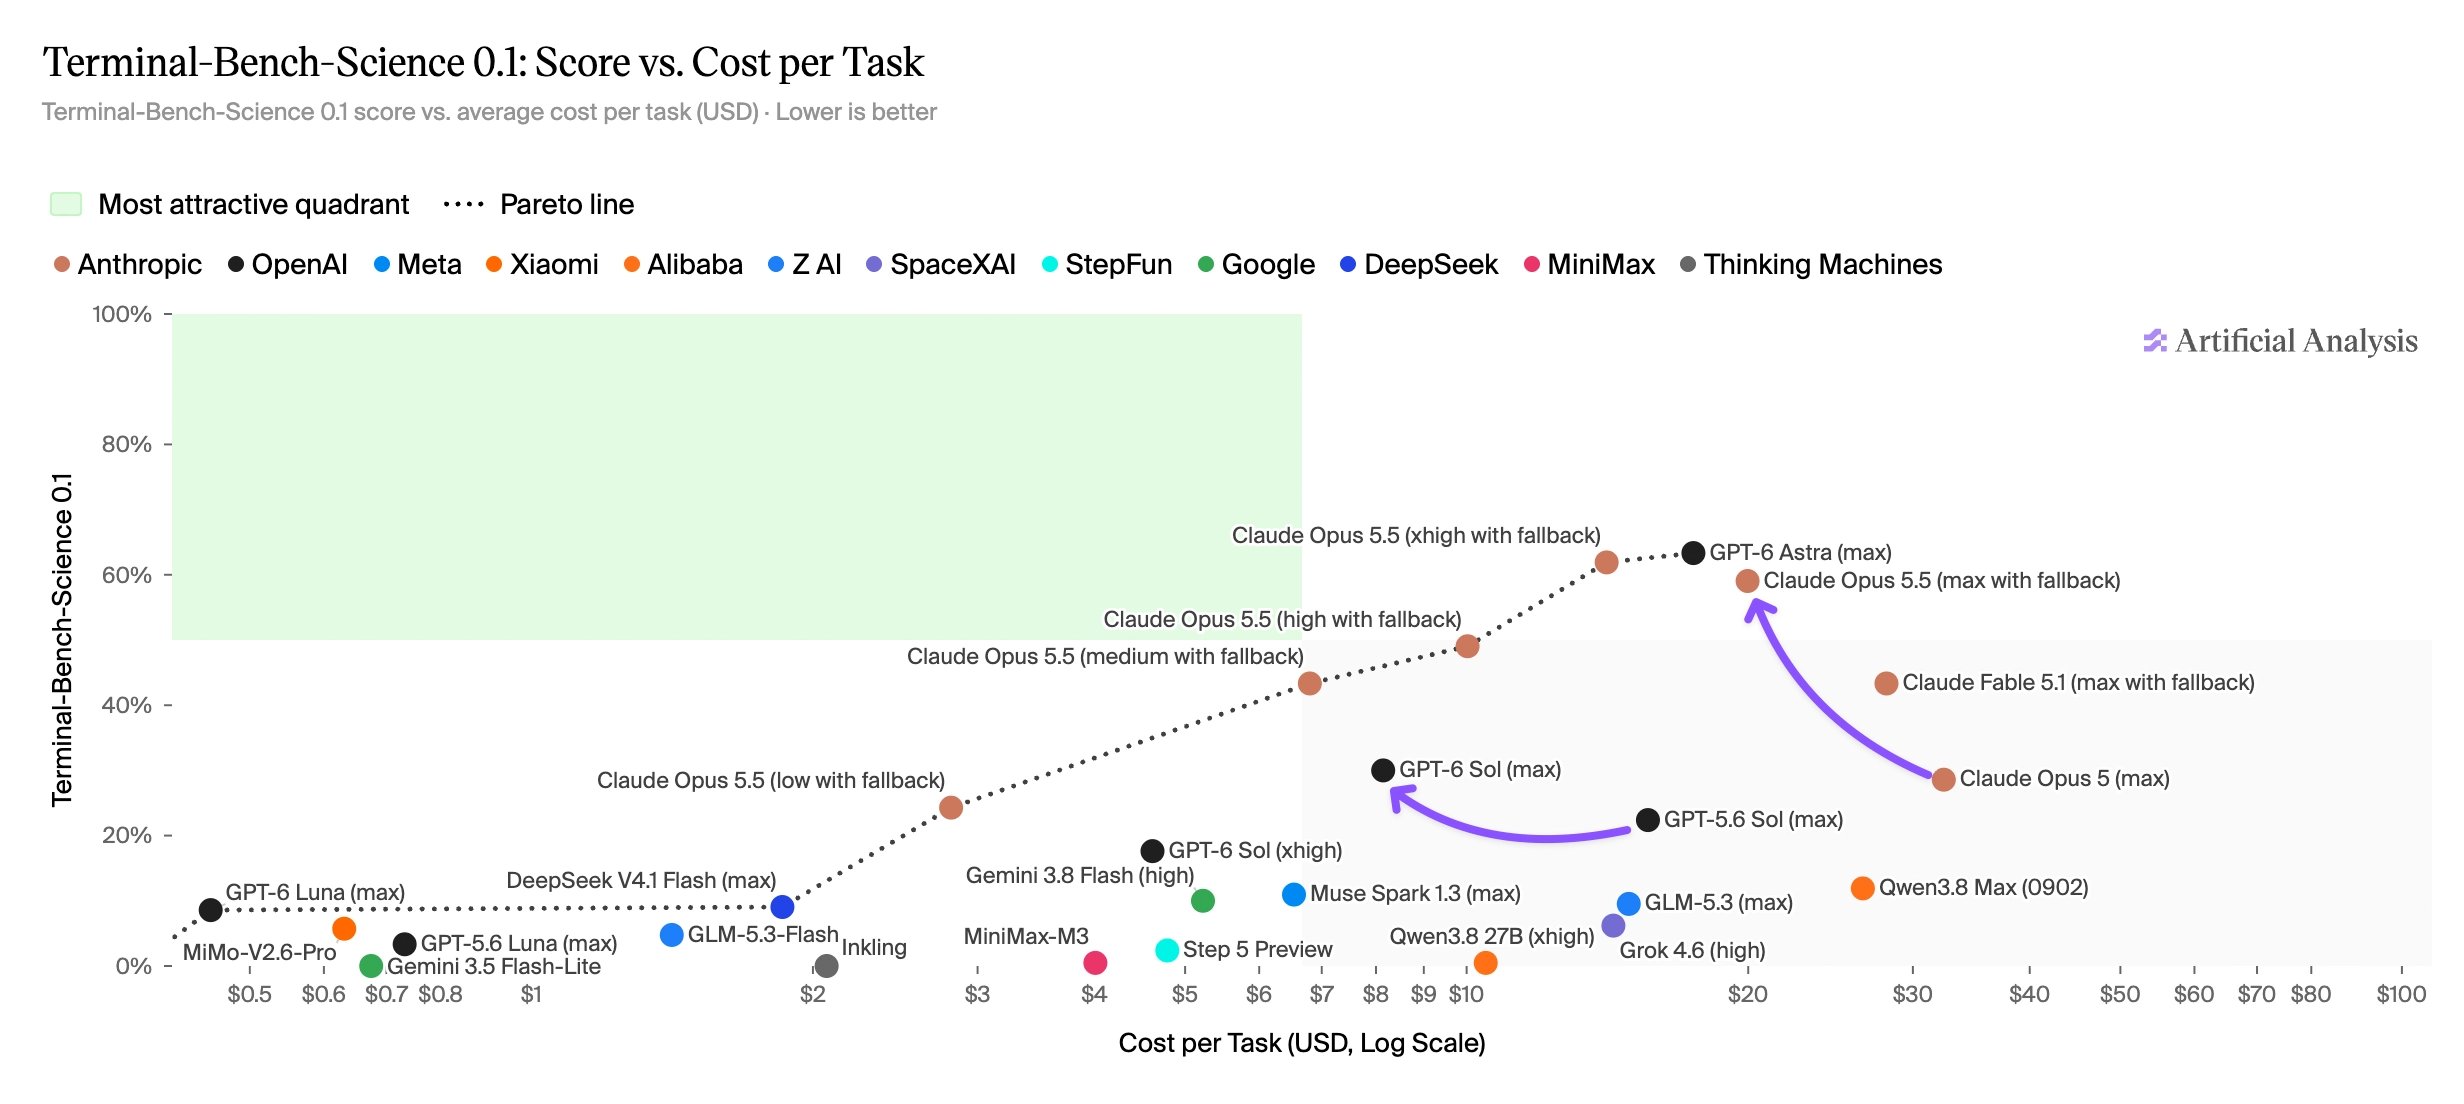
Terminal-Bench-Science discriminates well between models, as well as between different reasoning effort levels within frontier models. Claude Opus 5.5 rises ~38 points from low effort at 24% to xhigh at 62%, alongside a 5x difference in the cost per task. Max effort for Opus 5.5 scores slightly below xhigh at 59%. GPT-6 Sol gains 27 points from low to max effort at ~7.5x the cost per task.