CWE-Bench-AA 代码审计修复榜:GPT-6 Astra 63%
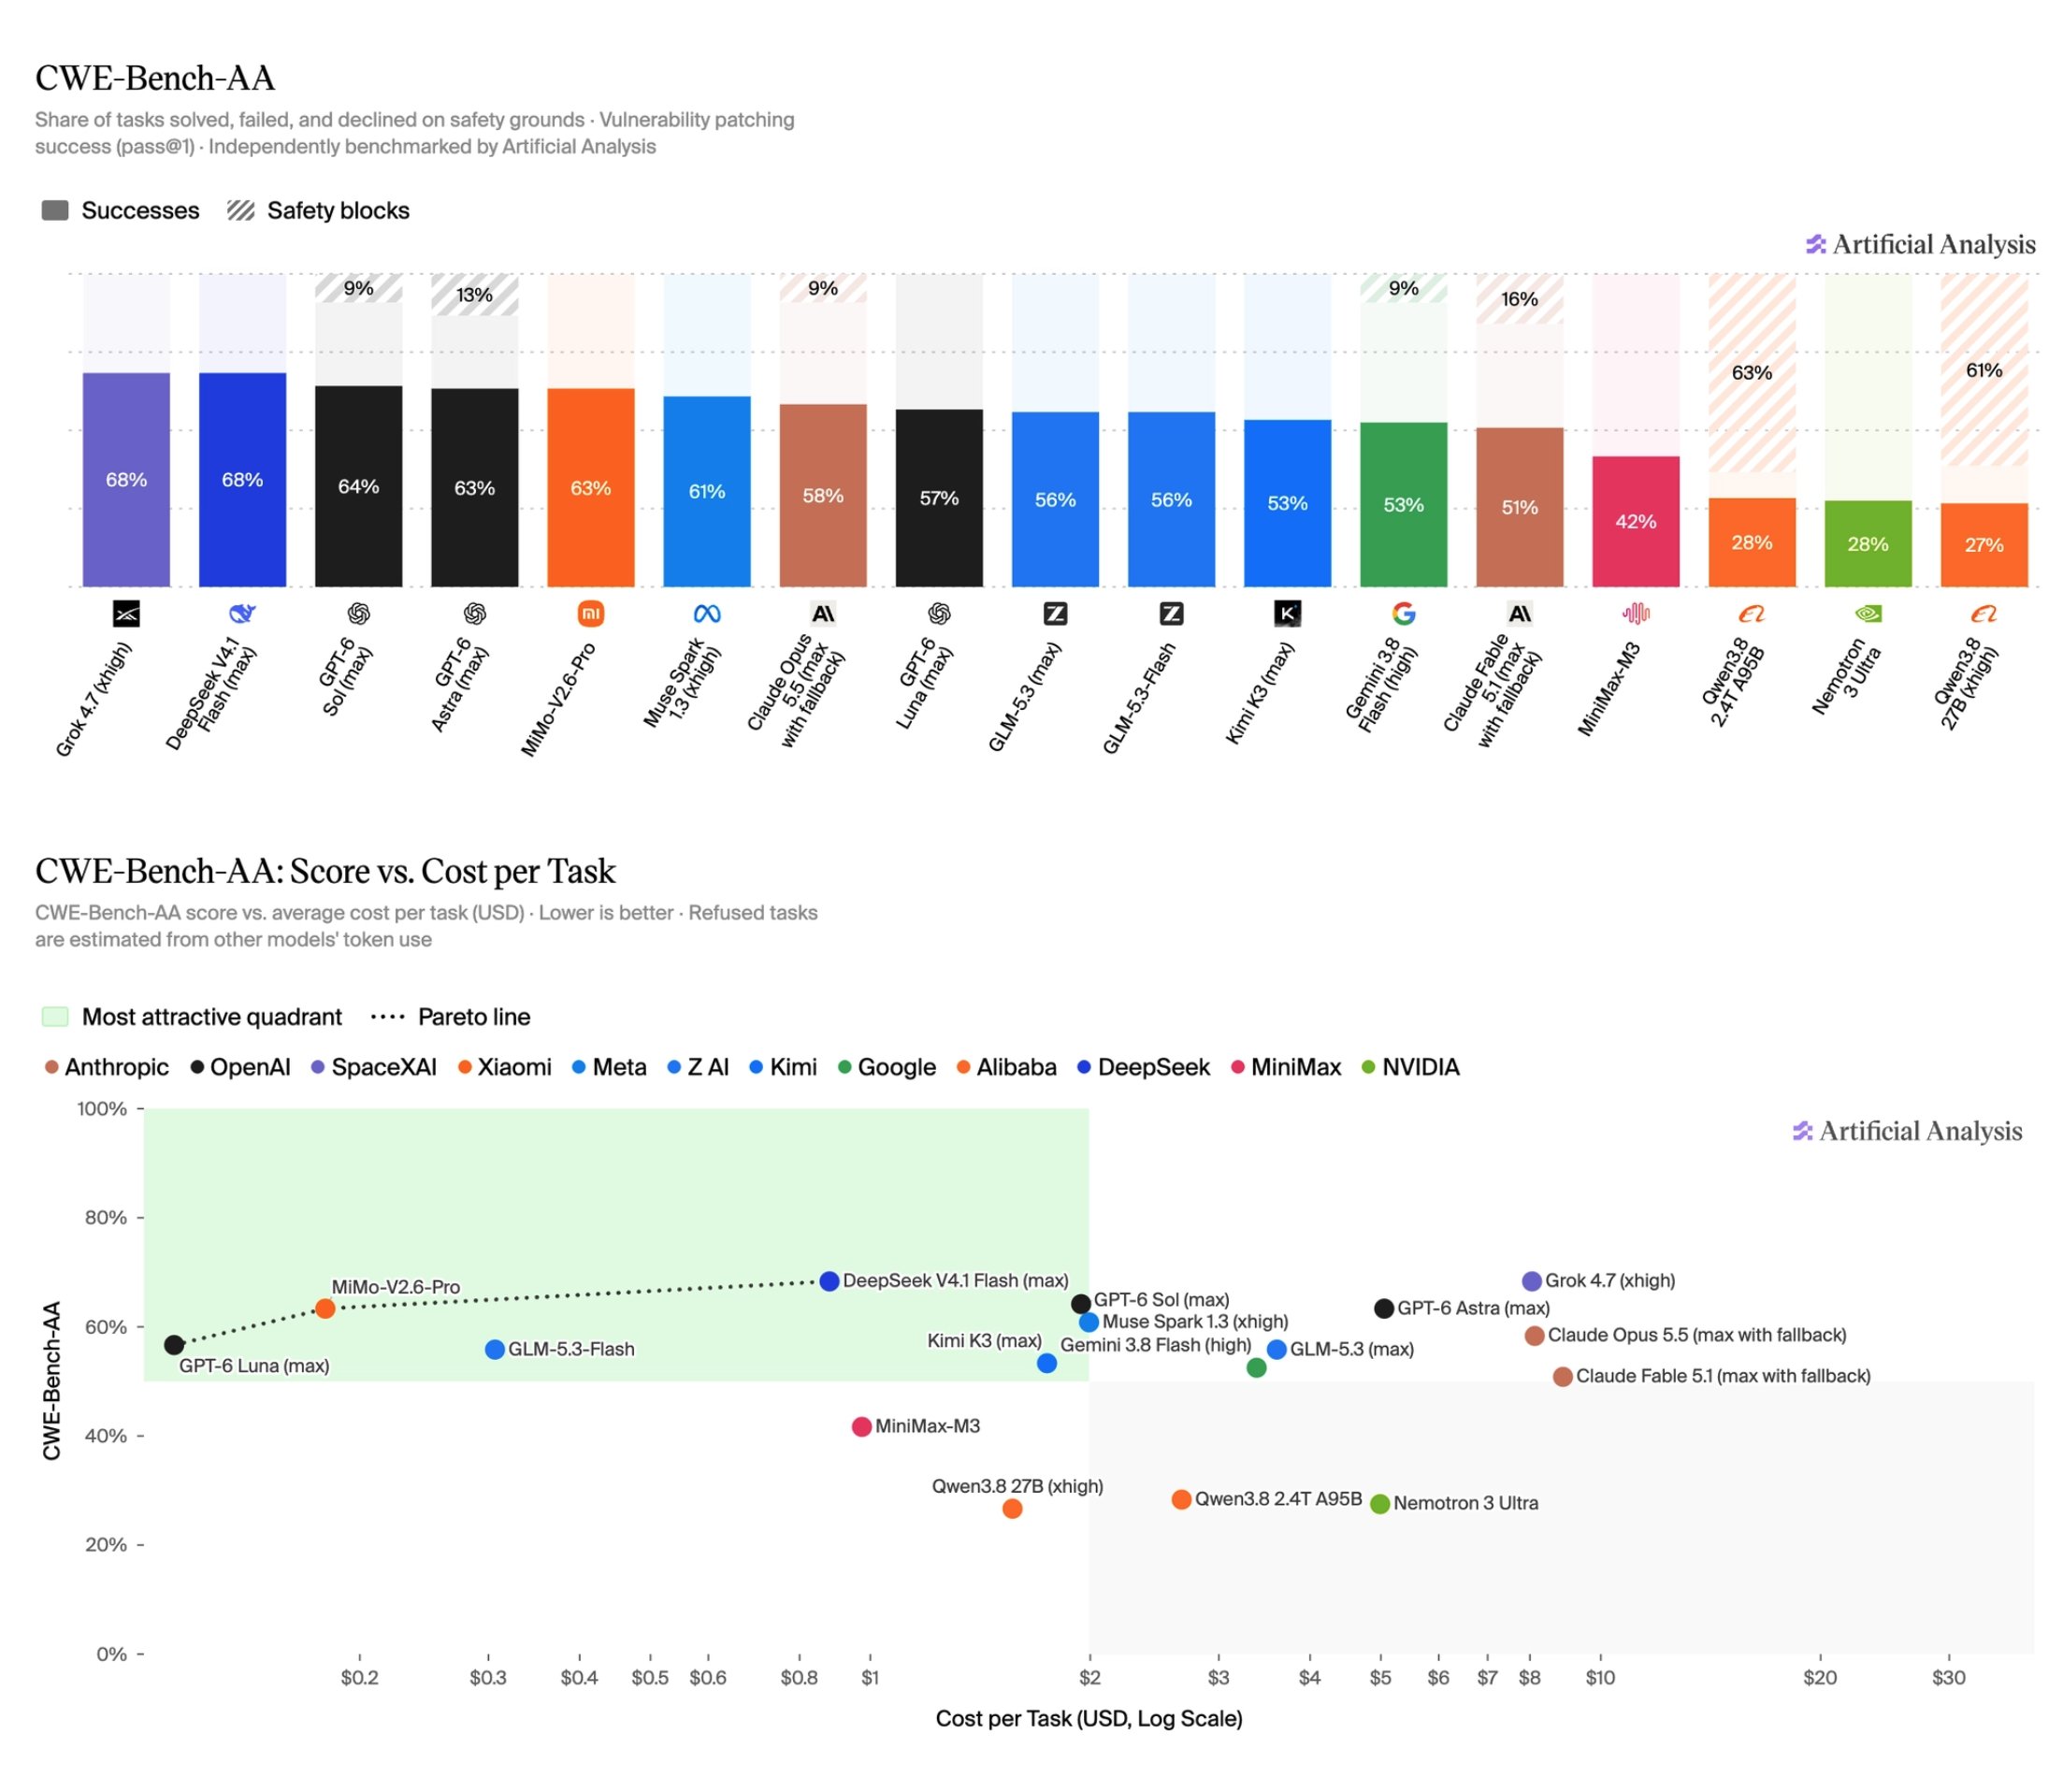
CollinearAI 的 CWE-Bench-AA 覆盖 OWASP Top 10 与六种语言,Grok 4.7 与 DeepSeek V4.1 Flash 以 68% 领先,GPT-6 Sol 64%、Astra 63%,Astra 拒答 13% 的任务。
CWE-Bench-AA, from @CollinearAI, tests whether an agent can audit a codebase and patch what it finds. 120 held-out tasks span all ten OWASP Top 10 (2025) categories across C/C++, Go, Java, JavaScript/TypeScript, Python and Rust. We report pass@1 on patching success. Grok 4.7 (xhigh) and DeepSeek V4.1 Flash (max) lead at 68%, followed by GPT-6 Sol (max, 64%), GPT-6 Astra (max, 63%) and MiMo-V2.6-Pro (63%). GPT-6 Astra (max) declines 13% of tasks and Claude Fable 5.1 (max with fallback) 16%, while both Qwen3.8 models decline over 60%. DeepSeek V4.1 Flash matches Grok 4.7's score for $0.88 per task, compared with $8.05 for Grok.
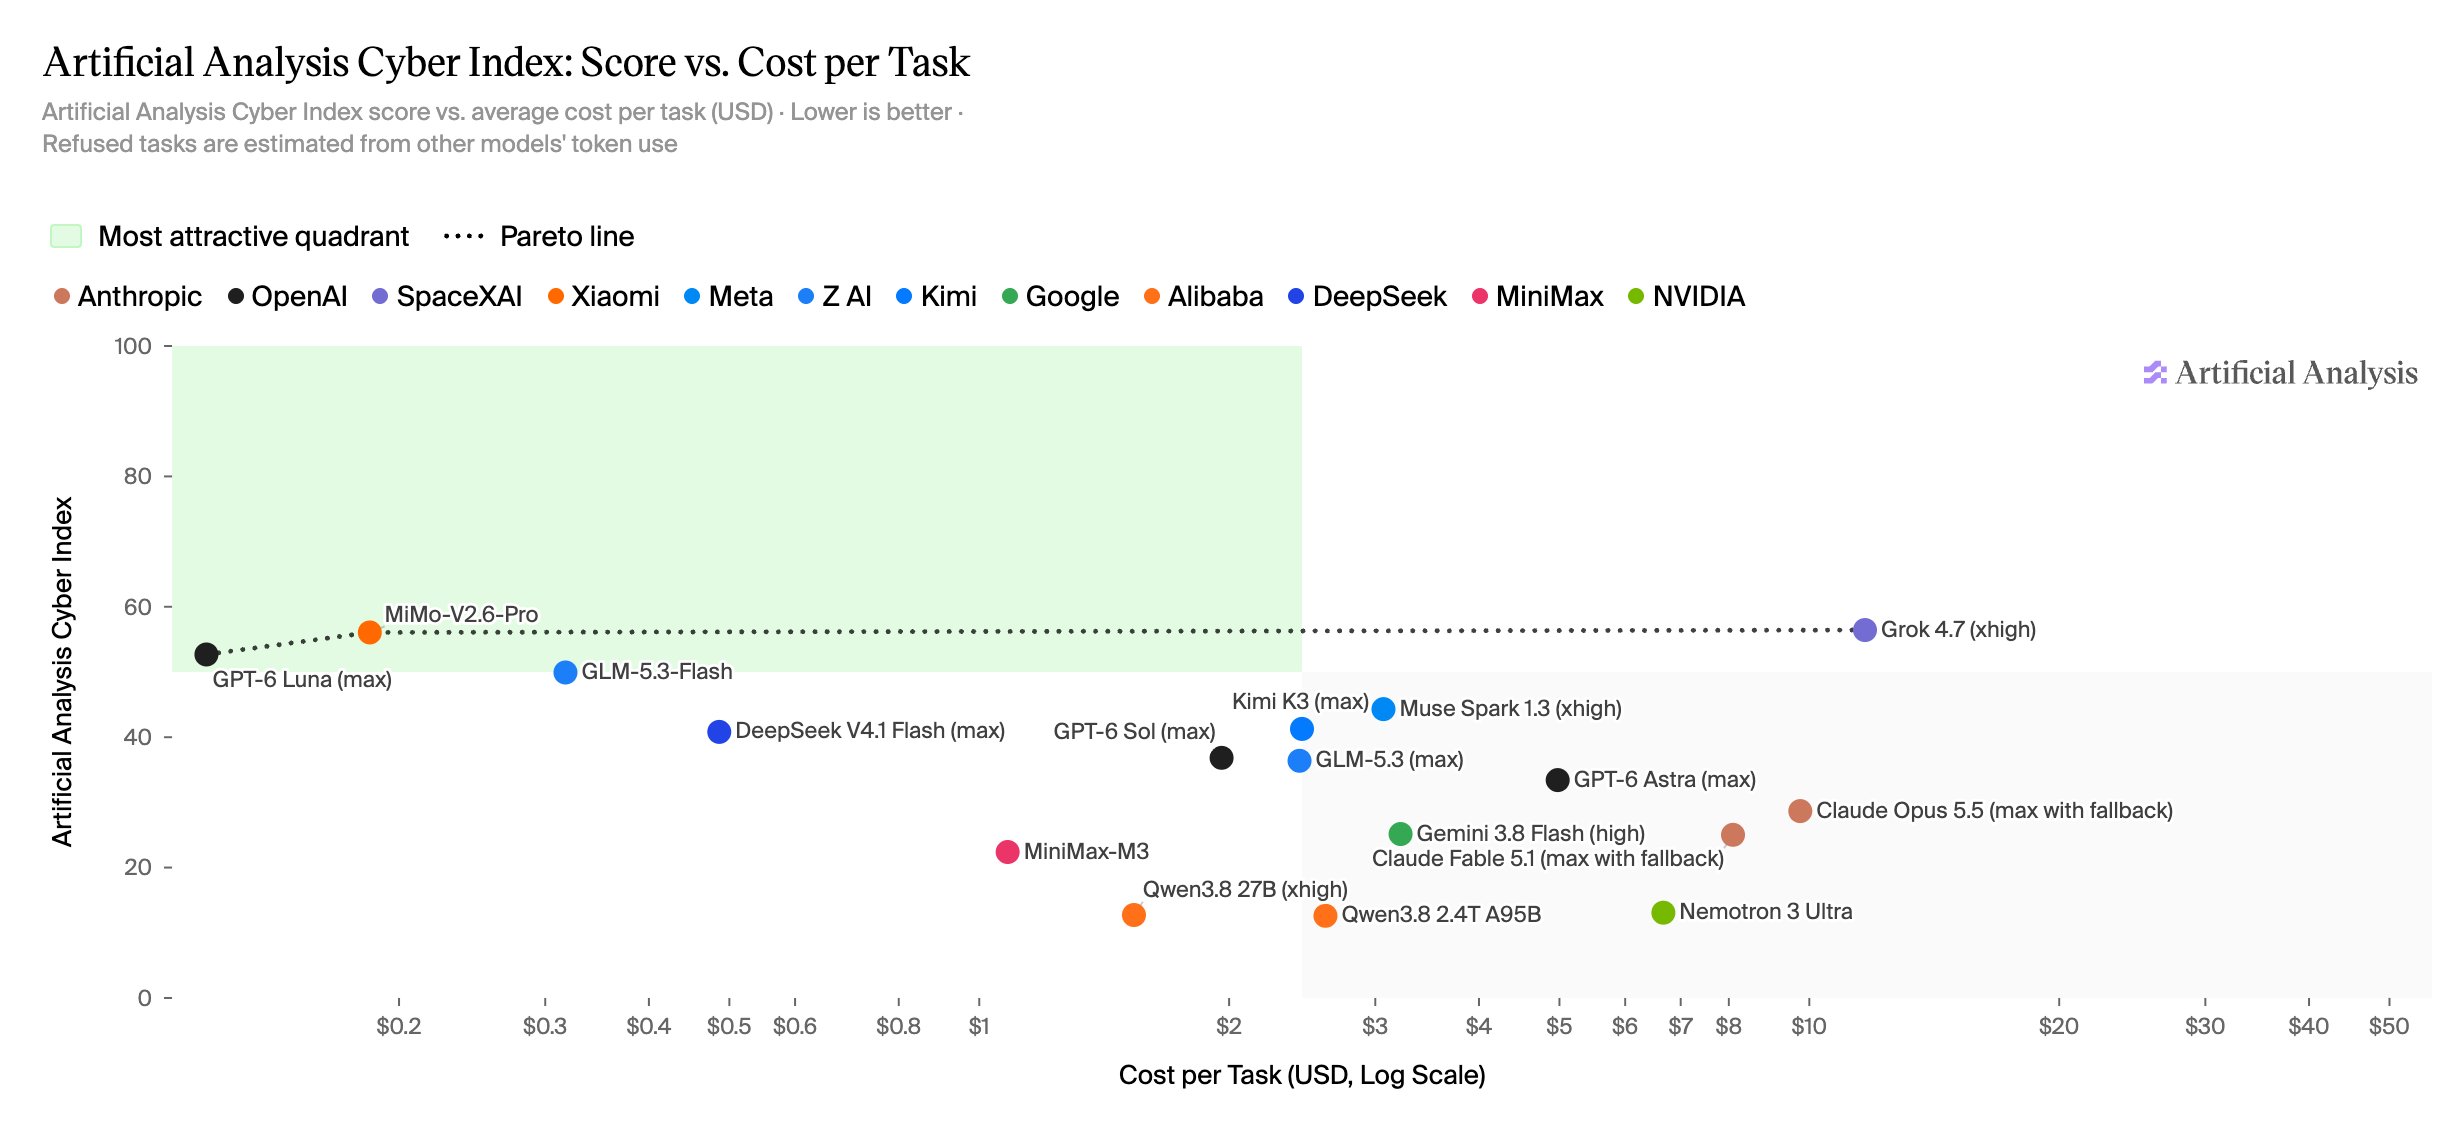
Three models occupy the Cyber Index vs. Cost per Task Pareto frontier. GPT-6 Luna (max) scores 53 at $0.12 per task, the lowest cost of any model tested, and MiMo-V2.6-Pro ties for the top score of 56 for $0.18 per task. Grok 4.7 (xhigh) matches MiMo-V2.6-Pro at 56 but costs $11.67 per task. GLM-5.3-Flash (50) is the only other model in the most attractive quadrant, at $0.32 per task. The models held back by refusals also sit at the expensive end: GPT-6 Astra (max, 33) costs $4.98 per task and Claude Opus 5.5 (max with fallback, 29) $9.75. We estimate the cost of refused tasks from other models' token use.