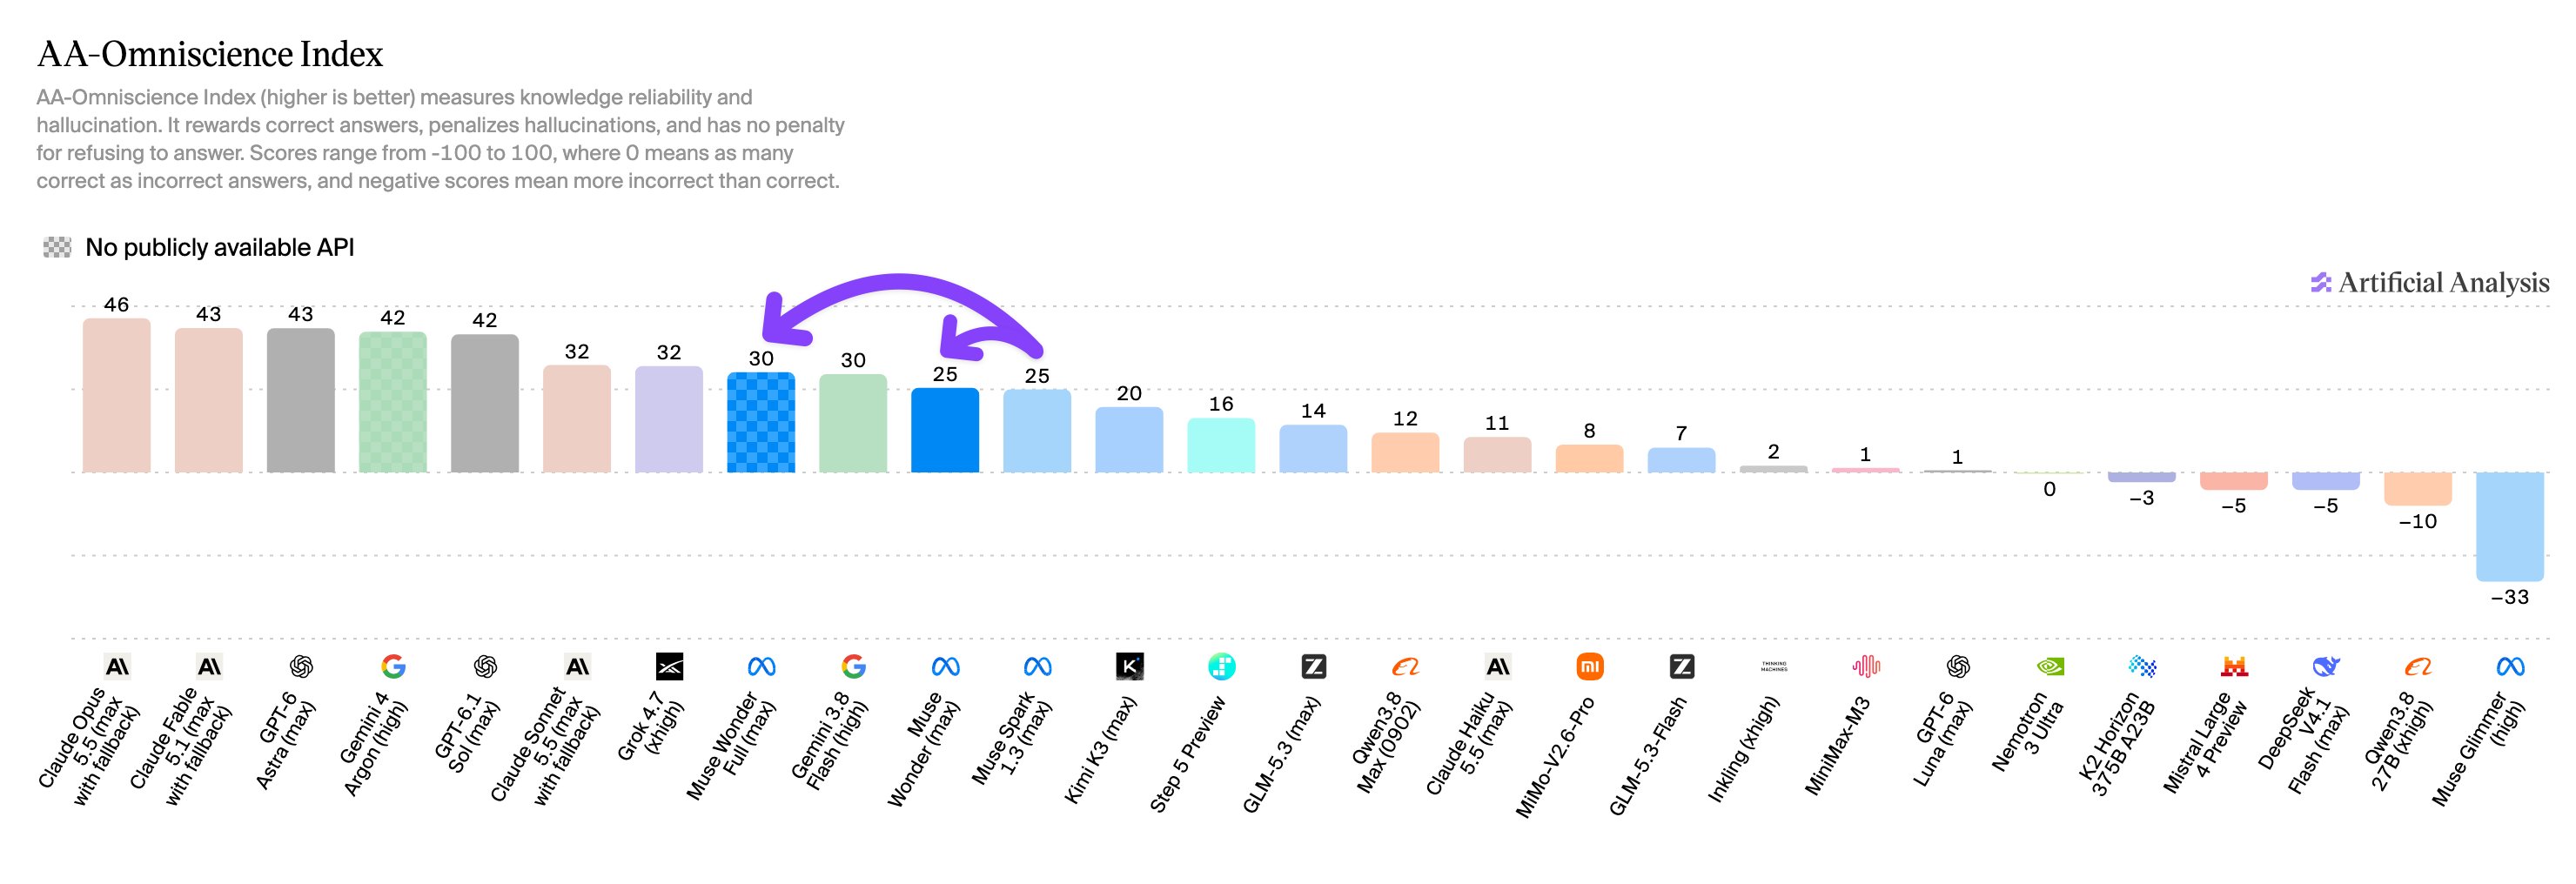
AA 榜单:Gemini 4 Argon 幻觉率最低、知识分 42
Artificial Analysis 称 Gemini 4 Argon 在 AA-Omniscience 得 42 分,且高配置下幻觉率仅 15%,为高分模型中最低。
Knowledge remains a relative weakness for both models, but this is mitigated by very low hallucination rates. On AA-Omniscience, Muse Wonder Full (max) scores 30 and Muse Wonder (max) scores 25, level with Muse Spark 1.3 (max), below e.g. Claude Opus 5.5 (46), GPT-6 Astra (43), Gemini 4 Argon (42), and Claude Sonnet 5.5 (32) Muse Wonder Full (max)'s 5-point gain comes from lowering its hallucination rate (33% to 23%), which places it among the least-hallucinating models tested: it has the second-lowest hallucination rate of any model scoring 45 or more on the Intelligence Index, behind only Gemini 4 Argon (high, 15%). Muse Wonder (max) is third at 27%
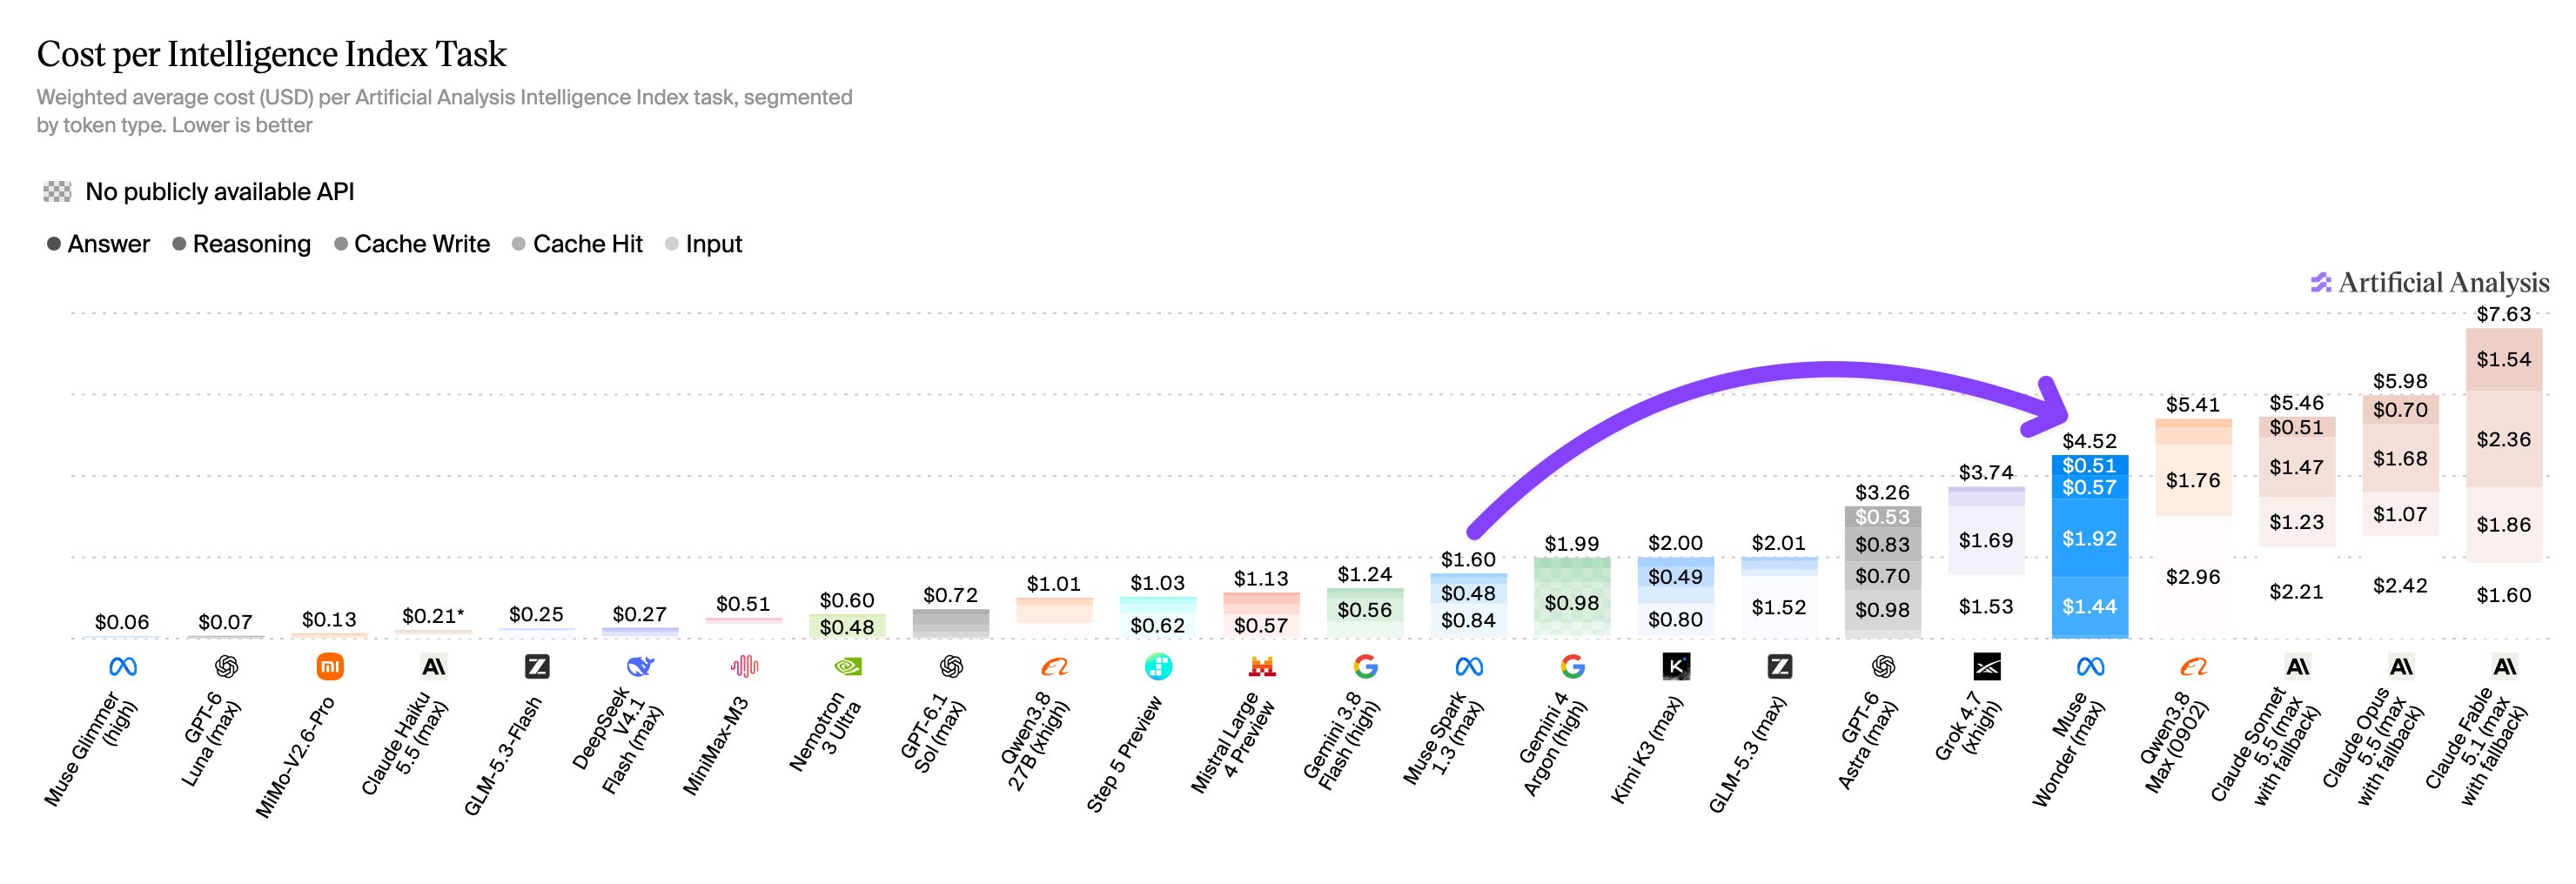
Muse Wonder (max) costs $4.52 per Artificial Analysis Intelligence Index task, 2.8x Muse Spark 1.3 (max, $1.60), driven by higher per-token prices and higher input token use ➤ Token pricing: $4 per 1M input tokens, $0.20 cached and $20 output, up from $1.25 / $0.15 / $4.25 for Muse Spark 1.3. This matches Claude Opus 5.5, is double each of Claude Sonnet 5.5, Gemini 4 Argon, and GPT-6.1 Sol ($2/$10), and is 60% below GPT-6 Astra and Claude Fable 5.1 ($10/$50) ➤ Input: 7.69M input tokens per task, 28% more than Muse Spark 1.3 (max, 6.03M) and 2-7x Gemini 4 Argon (high), GPT-6.1 Sol (max) and GPT-6 Astra (max). Input is $3.43 (76%) of its cost per task, composed of $1.92 cache writes, $1.44 cache hits and $0.07 uncached input ➤ Output: around 54k output tokens per task ($1.08), 10% fewer than Muse Spark 1.3 (max, 60k)
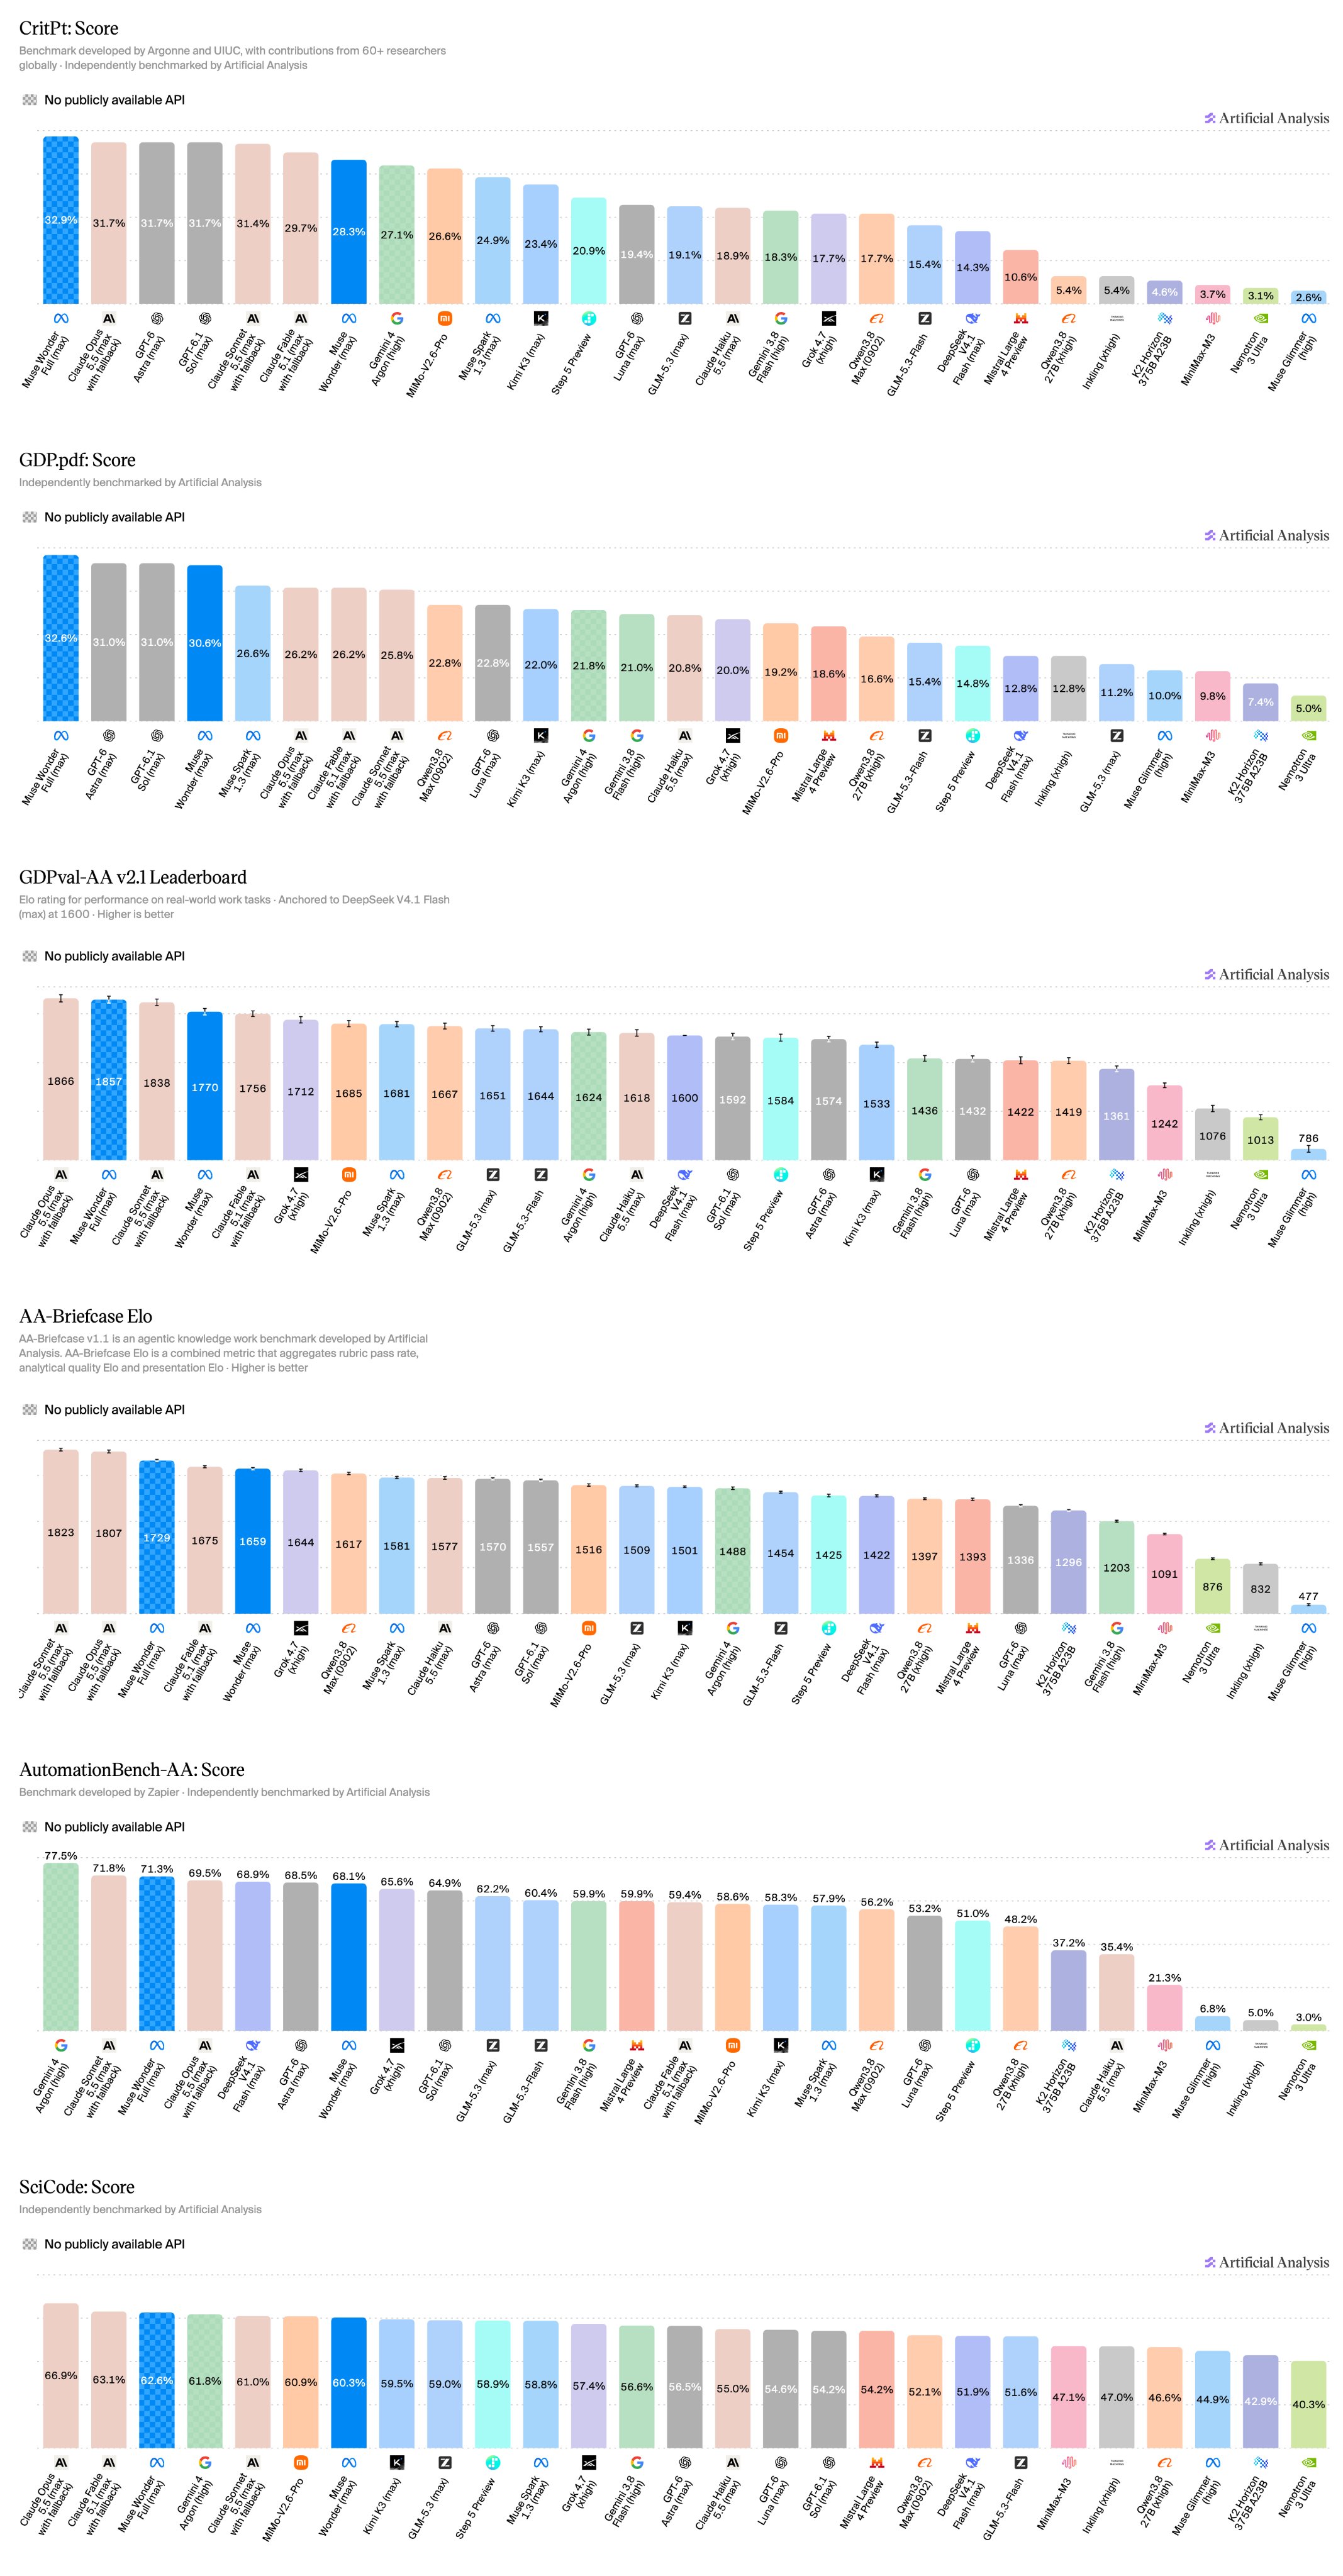
Muse Wonder Full (max) places in the top three on six of the ten Artificial Analysis Intelligence Index v4.3 evaluations: ➤ #1 on CritPt (33%) and GDP.pdf (33%) ➤ #2 on GDPval-AA v2.1 (1857 Elo) ➤ #3 on AA-Briefcase (1729 Elo), AutomationBench-AA (71%) and SciCode (63%) The leads on CritPt and GDP.pdf are narrow, with the nearest competitors scoring 31-32%. On GDPval-AA v2.1, its result is within the confidence intervals of Claude Opus 5.5 (max w/ fallback, 1866) and Claude Sonnet 5.5 (max w/ fallback, 1838) Its largest improvement over Muse Spark 1.3 is Terminal-Bench 4.0: 33% to 57%, bringing it level with Gemini 4 Argon (high)