Artificial Analysis 发布 AA-PersonalityBench 模型性格榜
新基准用 30 项性格特质和 21 项沟通特征给模型打分,GPT-6 Astra 进入透明度前三,Claude Fable 5.1 在多项指数领先。
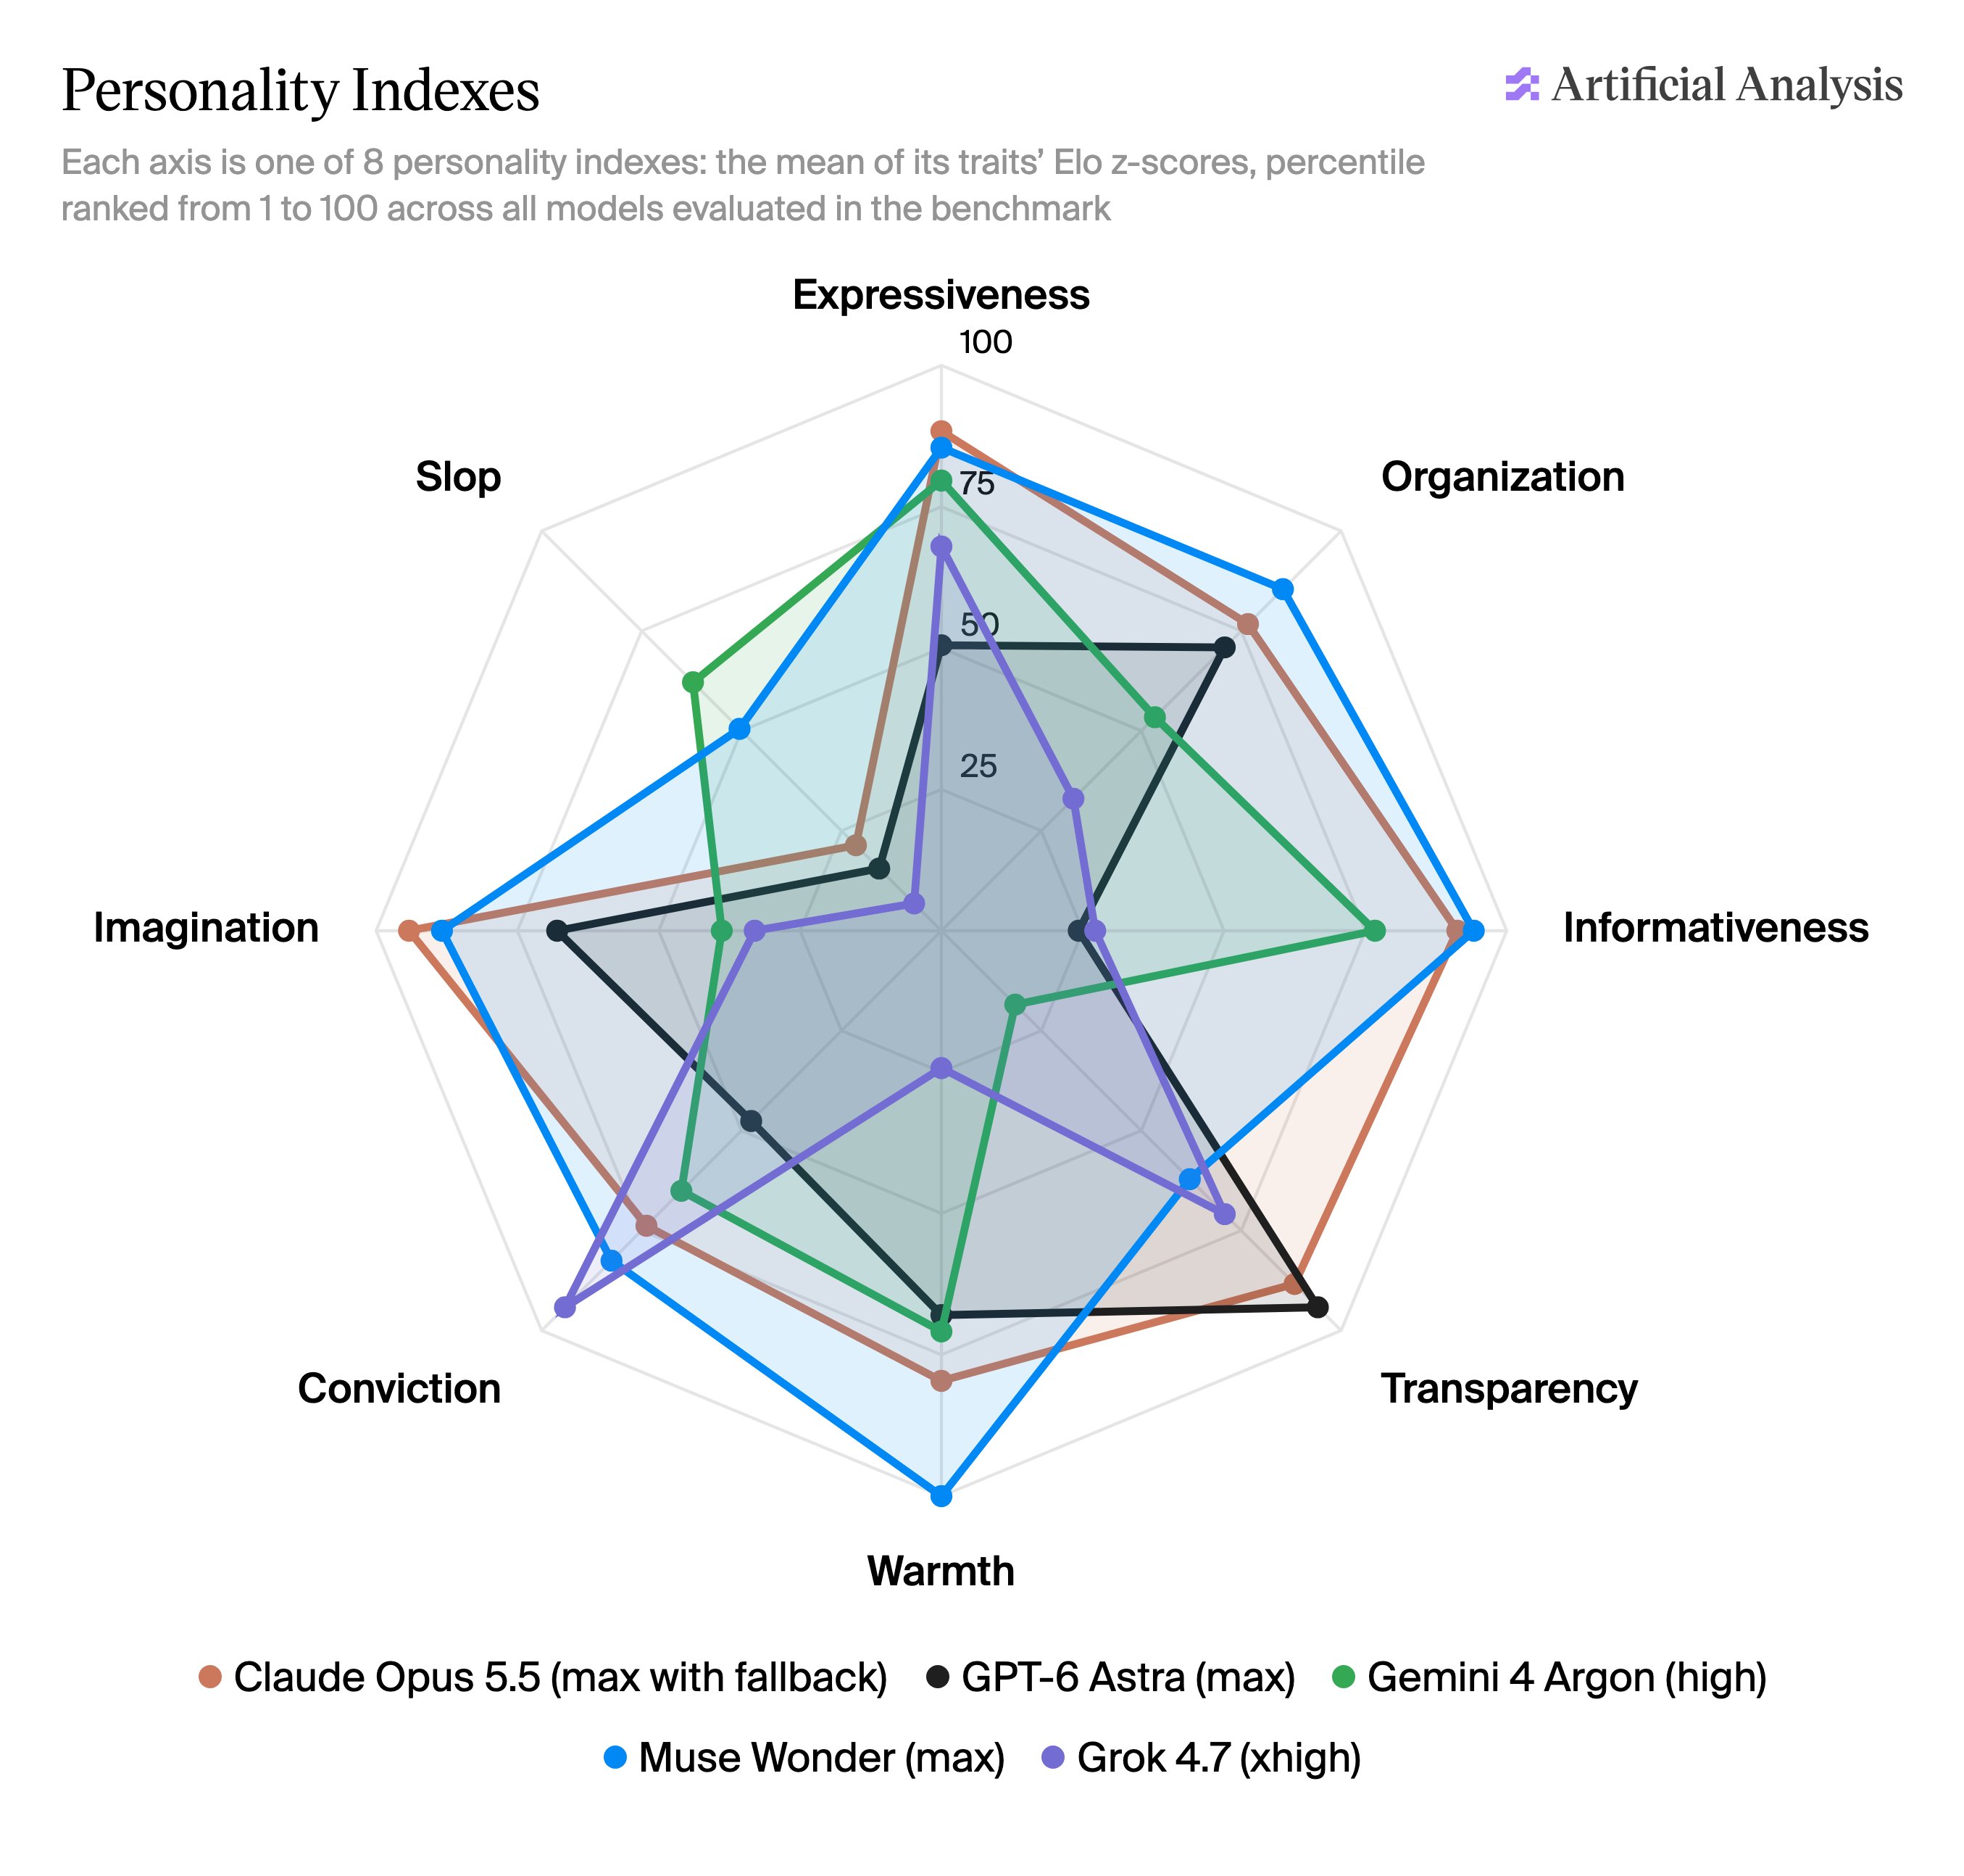
Announcing AA-PersonalityBench, our new benchmark of the personality of language models across 30 traits and their communication style across 21 characteristics Two models can give equally correct answers and still feel very different to use. AA-PersonalityBench measures those differences so people can understand which to use in different use-cases. Some use-cases like creative writing might demand imagination, while legal use-cases might demand directness. We evaluate models’ answers to 900 curated questions to judge subjective Personality Traits and programmatic means to calculate objective Communication Characteristics. Personality Traits & Indexes. There are 30 personality traits (e.g., eloquent, pragmatic, sycophantic) which we roll up into eight aggregated Personality Indexes: Expressiveness, Organization, Informativeness, Transparency, Warmth, Conviction, Imagination and Slop. Each trait has a set of 30 dedicated questions and models’ answers are compared pairwise by a panel of LLM judges. We then z-score and percentile rank the trait and personality Elos. Models with the strongest representation across the 8 Personality Indexes: ➤ Expressiveness: Claude Fable 5.1, GLM-5.3, GLM-5.3-Flash ➤ Organization: DeepSeek V4.1 Flash, Step 5 Preview, Inkling ➤ Informativeness: Muse Spark 1.3, Claude Fable 5.1, Muse Wonder, Claude Opus 5.5 ➤ Transparency: Claude Sonnet 5.5, Claude Fable 5.1, GPT-6 Astra ➤ Warmth: Muse Wonder, Muse Spark 1.3, Claude Fable 5.1 ➤ Conviction: Claude Fable 5.1, DeepSeek V4.1 Flash, Grok 4.7 ➤ Imagination: Muse Spark 1.3, Claude Opus 5.5, GLM-5.3 ➤ Slop: Llama 4 Maverick, GPT-4o, K2 Horizon Communication Characteristics. There are 21 communication characteristics (e.g., average sentence length, emoji use, em dash usage) which we group into four categories: length, structure, punctuation, and emphasis. We compute these characteristics programmatically across all model responses. ➤ Length: Qwen3.8 27B averages about 1,030 words per response, nearly four times GPT-6 Luna’s 270 ➤ Structure: Nemotron 3 Ultra averages nearly 3 tables per response, while most models rarely use one ➤ Punctuation: GLM-5.3 averages 7 em dashes per response, while Claude Opus 5.5, Sonnet 5.5 and Haiku 5.5 almost never use one ➤ Emphasis: K2 Horizon averages over 2 emoji per response, while most models almost never use one