Artificial Analysis 发布 Code2Video-AA:Gemini 4 Argon 担任评审
新基准用 114 个营销简报测模型写代码生成视频,Claude Opus 5.5 领先 93 分,GPT-6 Astra 并列第二,评审模型为 Gemini 4 Argon。
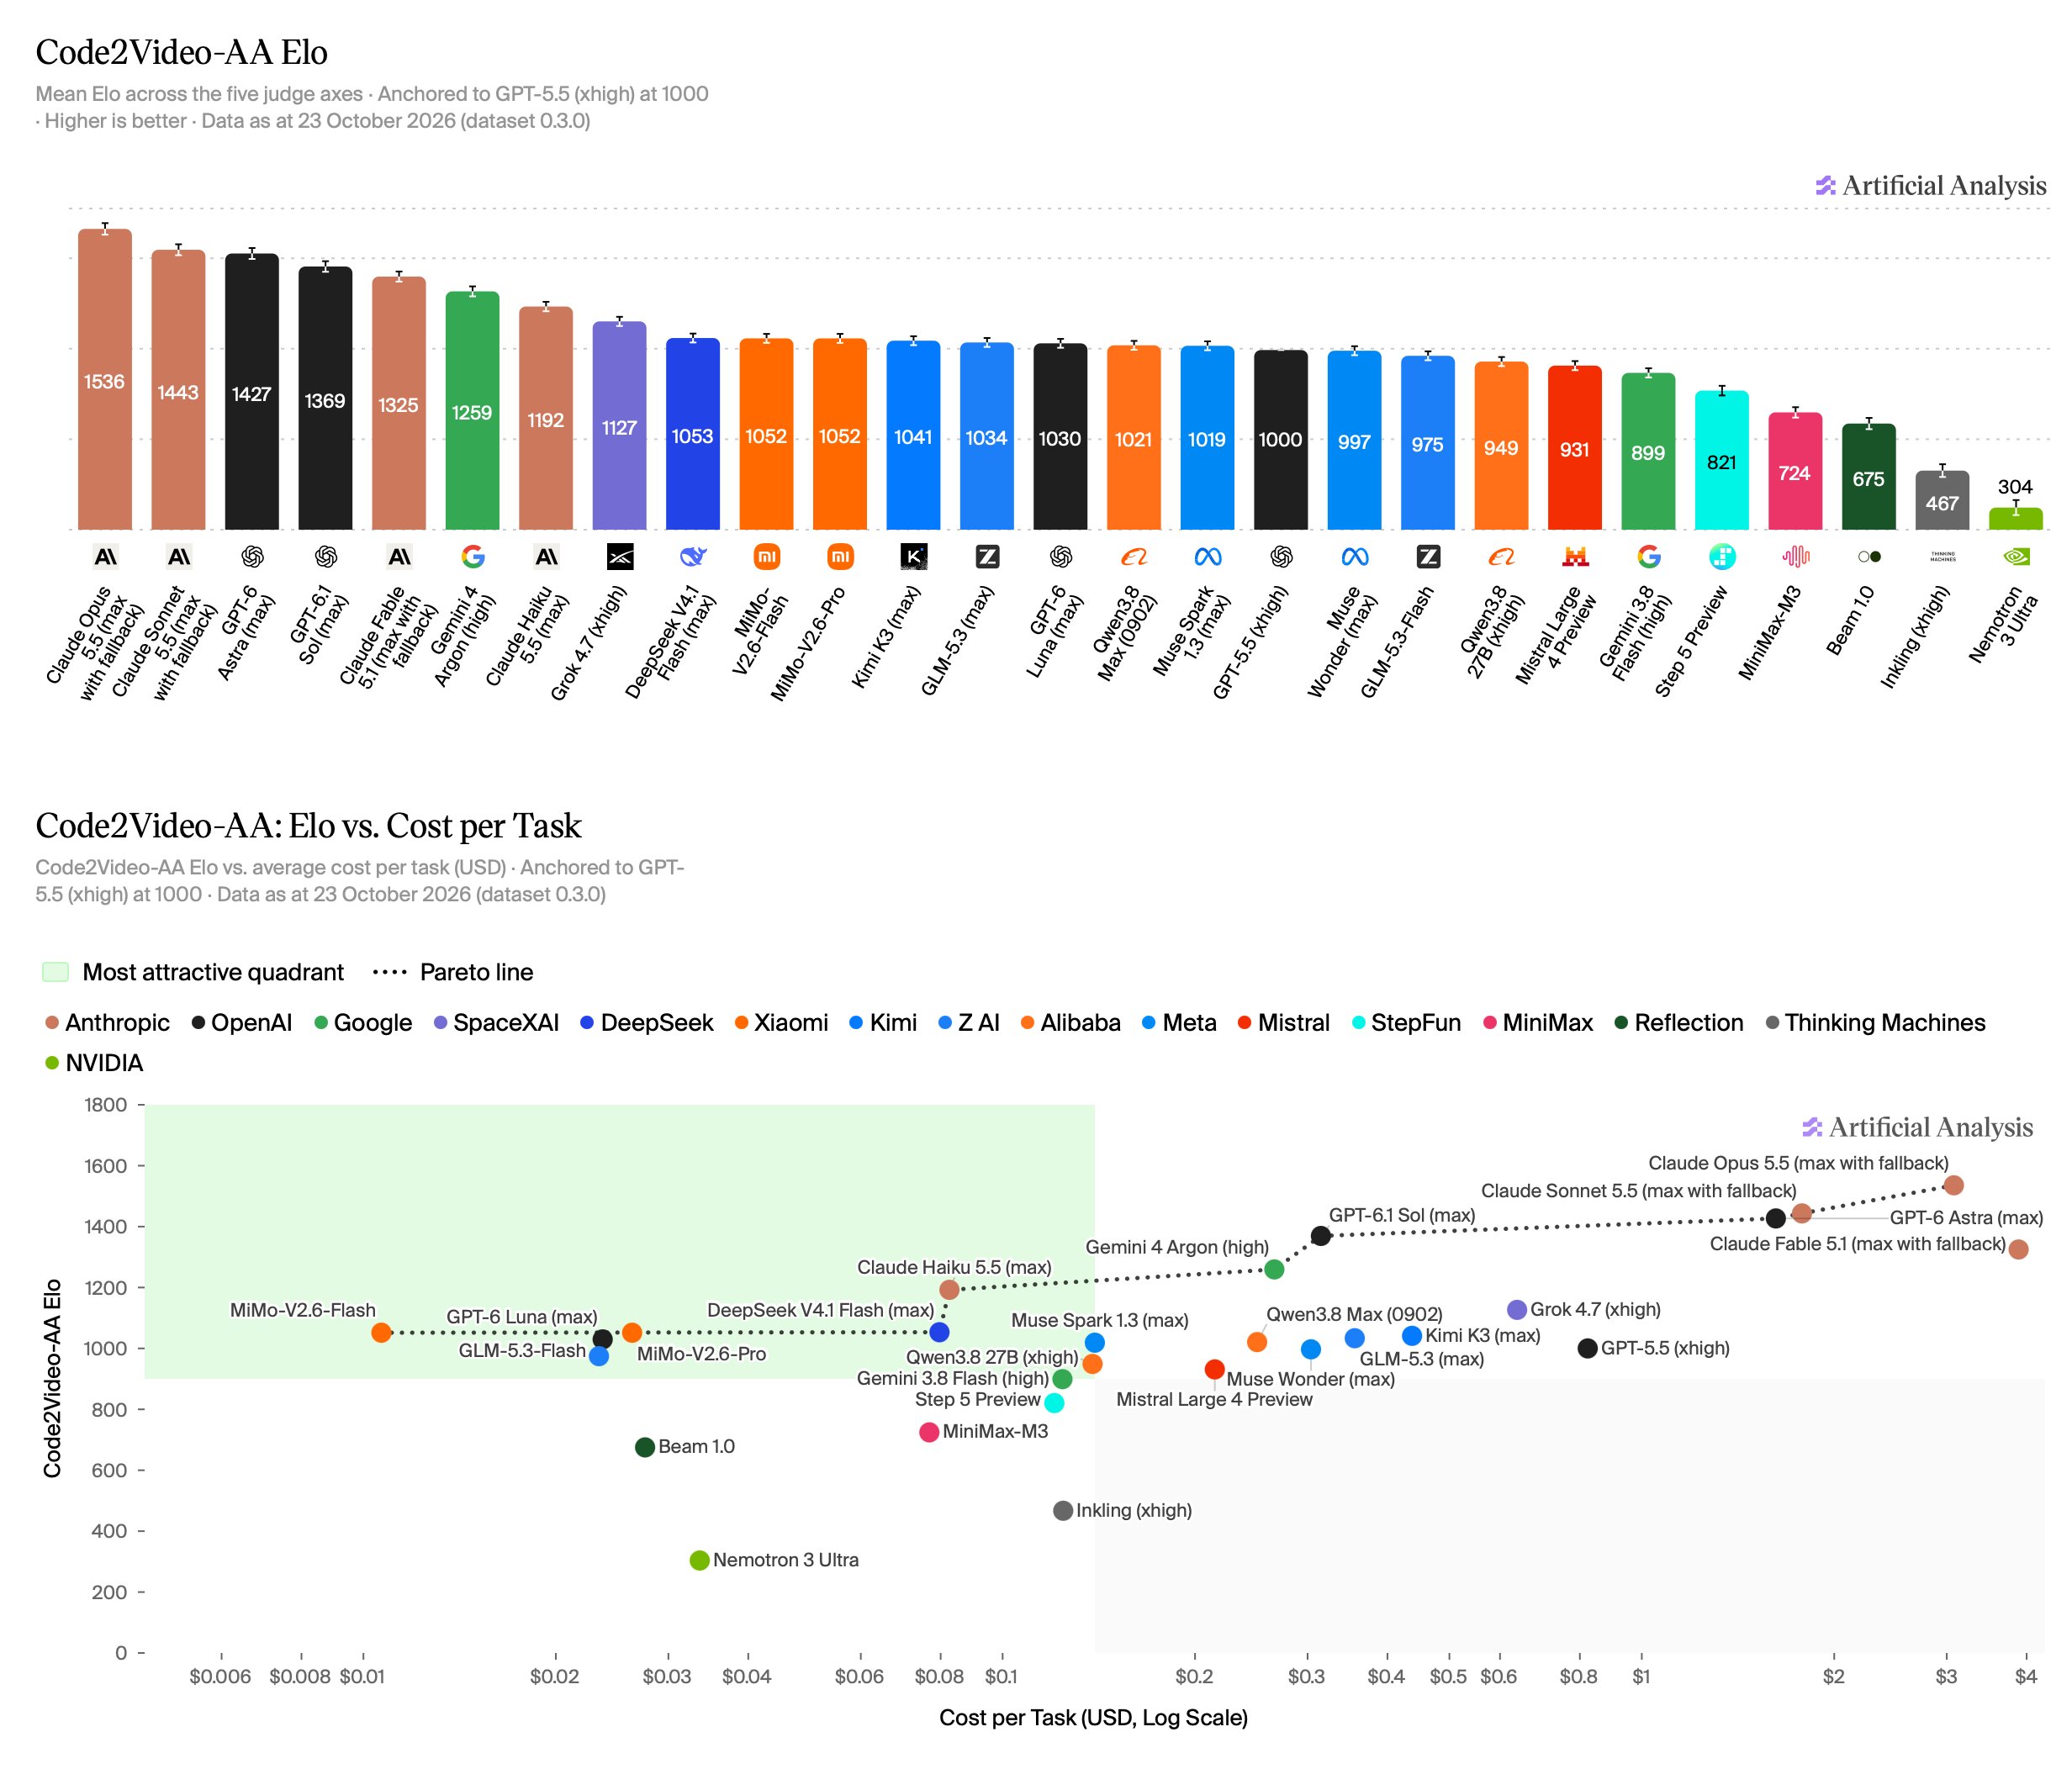
Introducing Code2Video-AA, our independent implementation of HeyGen’s Code2Video Bench, which evaluates how well models create product and brand marketing videos in code Code2Video-AA tests models across 114 design briefs, tasking them with turning each product or brand marketing brief into a @HyperFrames_ HTML composition, which we render to video. Model outputs are evaluated through pairwise comparisons with other model outputs across five axes: Engagement, Prompt Intent, Composition, Temporal Consistency, and Craft. We use the outcomes of these comparisons to calculate an Elo rating for each axis, which are then averaged to produce the headline Code2Video-AA Elo. Code2Video-AA was built in partnership with @HeyGen. Claude Opus 5.5 (max with fallback, 1536) leads Code2Video-AA by 93 points, but costs $3.08 per task, ~10x more than GPT-6.1 Sol (max, 1369), which trails by 167 points. Key findings: ➤ Claude Opus 5.5 leads on all five judge axes: Models are judged across 5 axes: Engagement, Prompt Intent, Composition, Temporal Consistency, and Craft. Claude Sonnet 5.5 (max with fallback, 1443) and GPT-6 Astra (max, 1427) are statistically tied for second in overall score ➤ Cost per task varies more than 300x, from $0.01 to $3.89: GPT-6.1 Sol (max), fourth, has a Cost per Task of $0.31, about 90% lower than Claude Opus 5.5 (max with fallback) at $3.08 ➤ Open weights models trail by at least 483 points: DeepSeek V4.1 Flash (max, 1053), MiMo-V2.6-Flash (1052) and MiMo-V2.6-Pro (1052) are the top open weights models, at $0.01 to $0.08 per task Code2Video-AA details: ➤ Models are tested on a single response without tools. We render it with HyperFrames, with no network access ➤ A judge (Gemini 4 Argon, high) compares pair of videos across five axes: engagement, prompt intent, composition, temporal consistency and craft, with the final score being calculated from a combination of each individual axis Elo ➤ Over 35,000 verdicts rank 27 models by Elo, with 95% confidence intervals More results, example videos and how Code2Video-AA works follow in the thread below