Artificial Analysis 发布 Intelligence Index v5,GPT-6 Astra 排第二
新版榜单 60% 基于私有测试集,Claude Opus 5.5 以 58 分居首,GPT-6 Astra(max)57 分紧随其后,GPT-6.1 Sol 55 分。
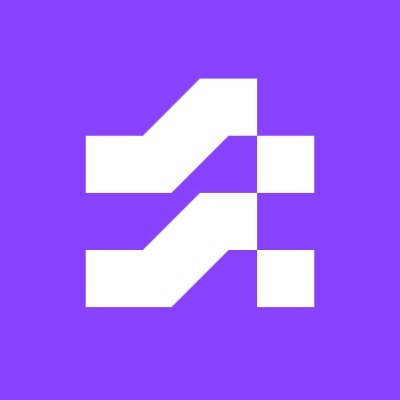
Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised ➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0 Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1 Key results: ➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50 ➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36) ➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04
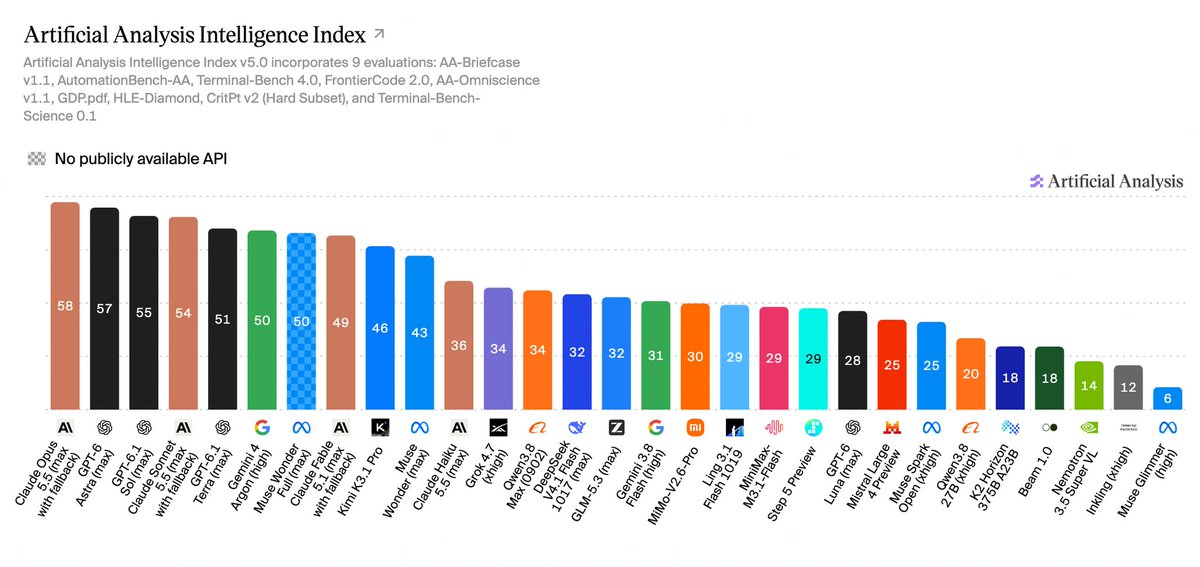
Terminal-Bench-Science tests whether agents can carry out scientific research workflows in a terminal. Experts curate and review each task, and a task passes only if every one of its tests passes. GPT-6 Astra (max) leads at 63%, followed by Claude Opus 5.5 (max) at 59% and GPT-6.1 Sol (max) at 58%. Scores drop off sharply below the leaders: the best open weights model, Kimi K3.1 Pro (weights not yet released), scores 34%, and Claude Haiku 5.5 (max) scores 20%. The best open weights model with released weights, DeepSeek V4.1 Flash 1017 (max), scores 13%, and most open weights models we benchmarked score under 10%.
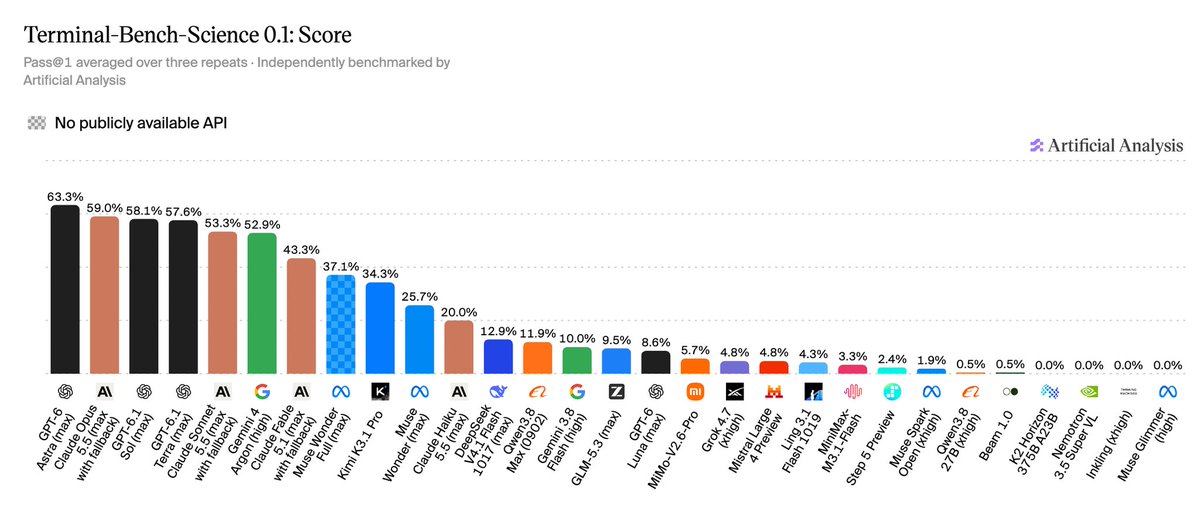
FrontierCode 2.0 is the latest update of @cognition's private coding benchmark. Launched earlier today, it comprises 132 tasks in real open-source repositories, graded on whether a maintainer would merge the agent's change. An attempt that fails any blocking check scores 0, and the tasks stay private to avoid contamination. We run every task three times in Stirrup, our agentic harness. Claude Opus 5.5 (max) leads at 46%, followed by GPT-6 Astra (max), GPT-6.1 Terra (max) and Claude Sonnet 5.5 (max), all at 42%. DeepSeek V4.1 Flash 1017 (max) is the highest-scoring open weights model at 28%, 18 points behind the leader.