aiIMAGE
RRSI:让自改进 Agent 真正泛化
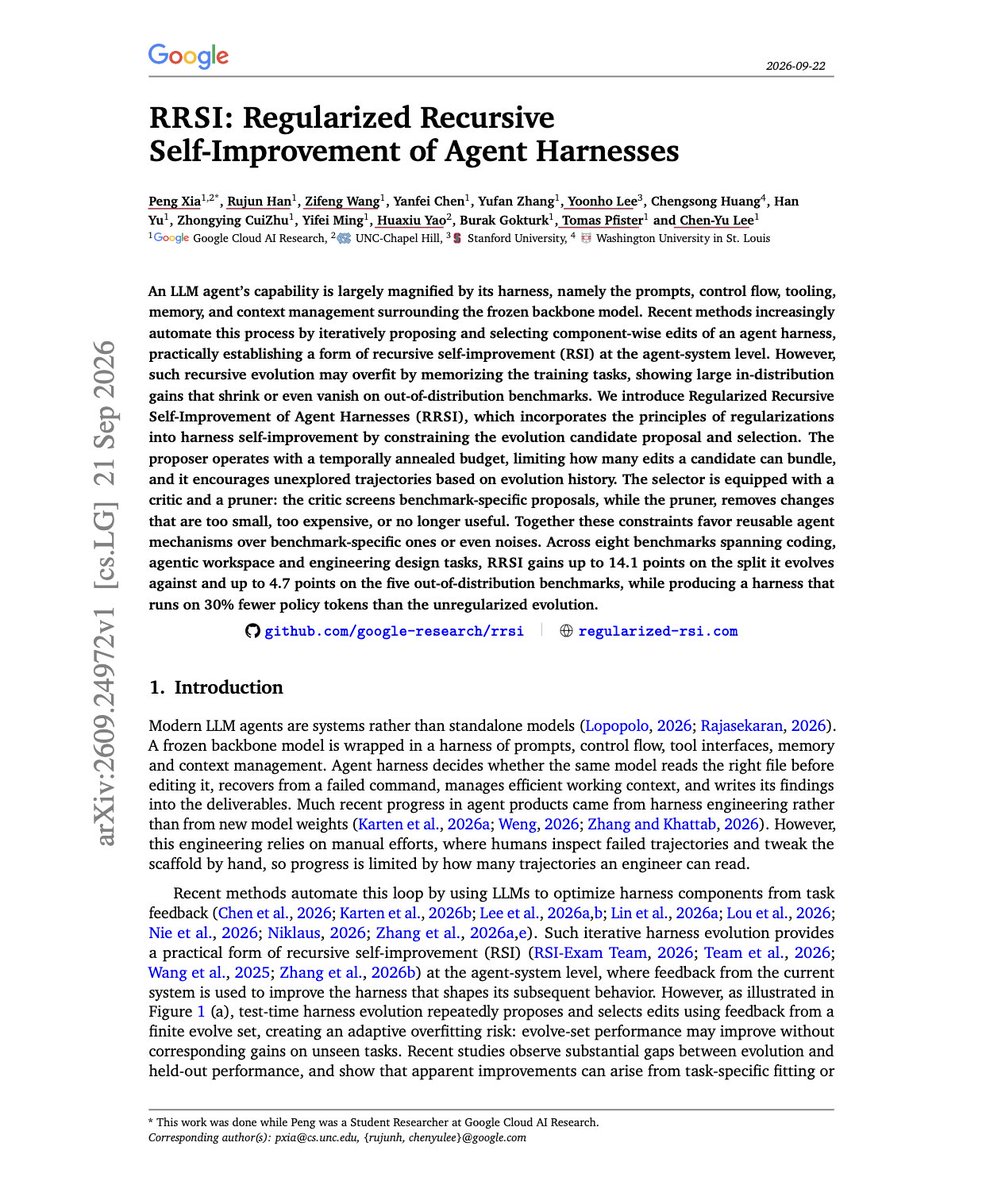
新方法给 agent 自我进化加正则约束,偏向可复用改动,在编码与工程任务上提升 OOD 表现且省 30% token。

alphaXiv
@askalphaxiv2026.09.24收录原推发布于 2026.09.23
alphaXiv @askalphaxiv原推发布于 2026.09.23
"RRSI: Regularized Recursive Self-Improvement of Agent Harnesses" RRSI makes self-improving AI agents generalize instead of just overfitting their benchmarks. So instead of letting self-improvement chase whatever boosts the benchmark, RRSI constrains the evolution process to favor changes that are actually reusable. Across coding, agentic workspace and engineering tasks, RRSI improves OOD benchmarks while using 30% fewer policy tokens than unregularized evolution. https://t.co/2fCZAddXz4
x.com/askalphaxiv/status/2102646972419375462采集于 2026.09.24 11:04