Assistant Benchmark:108 款助手实测评分卡
同一套真实任务对照测短信式 AI 助手,Muse/Instinct 等暂时领跑,并附公开用例引用。
这篇在说什么
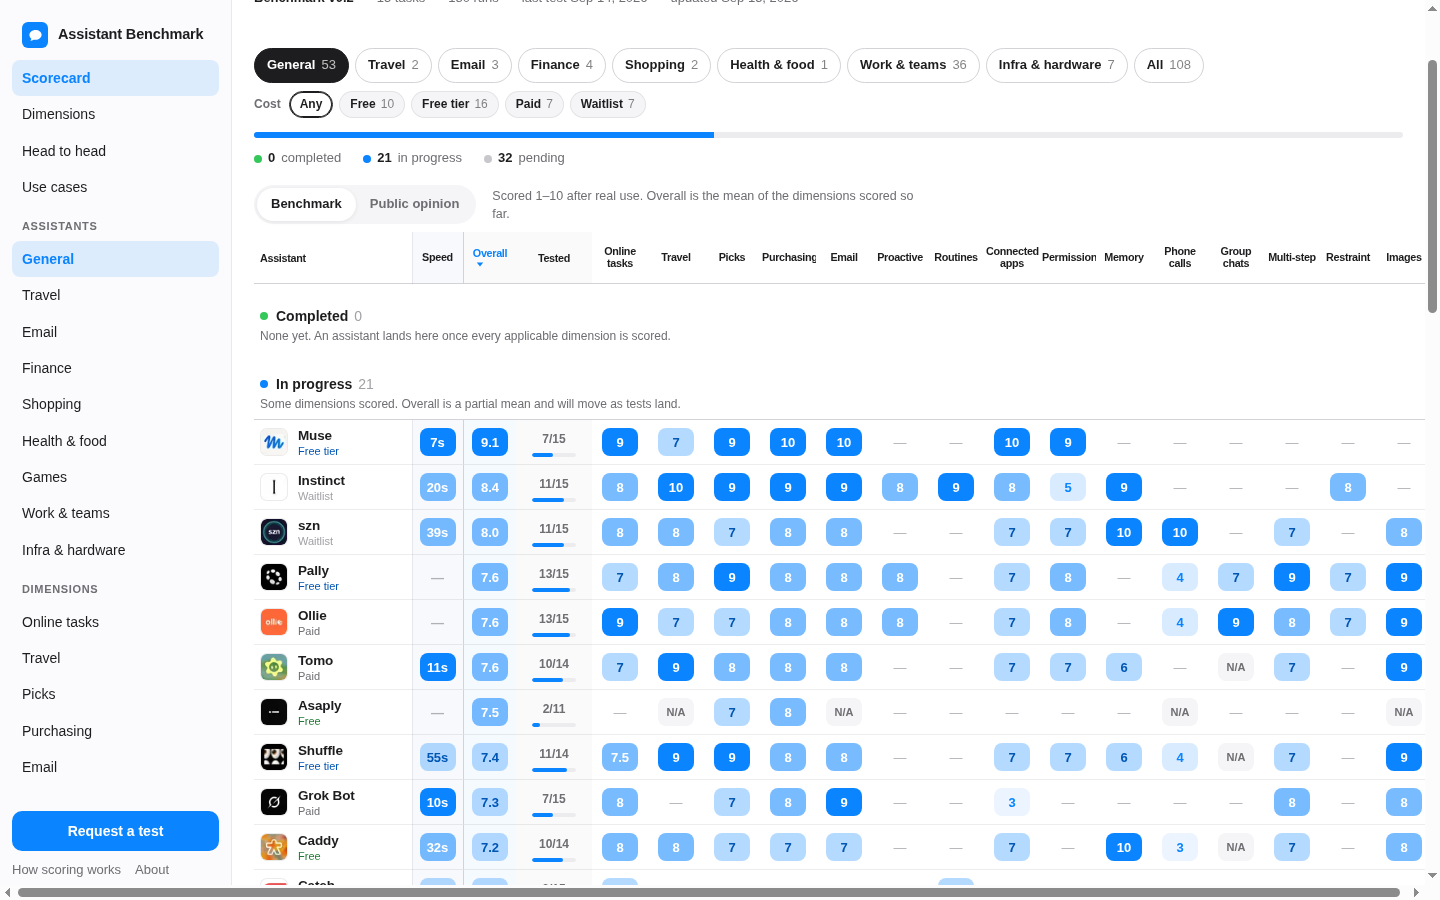
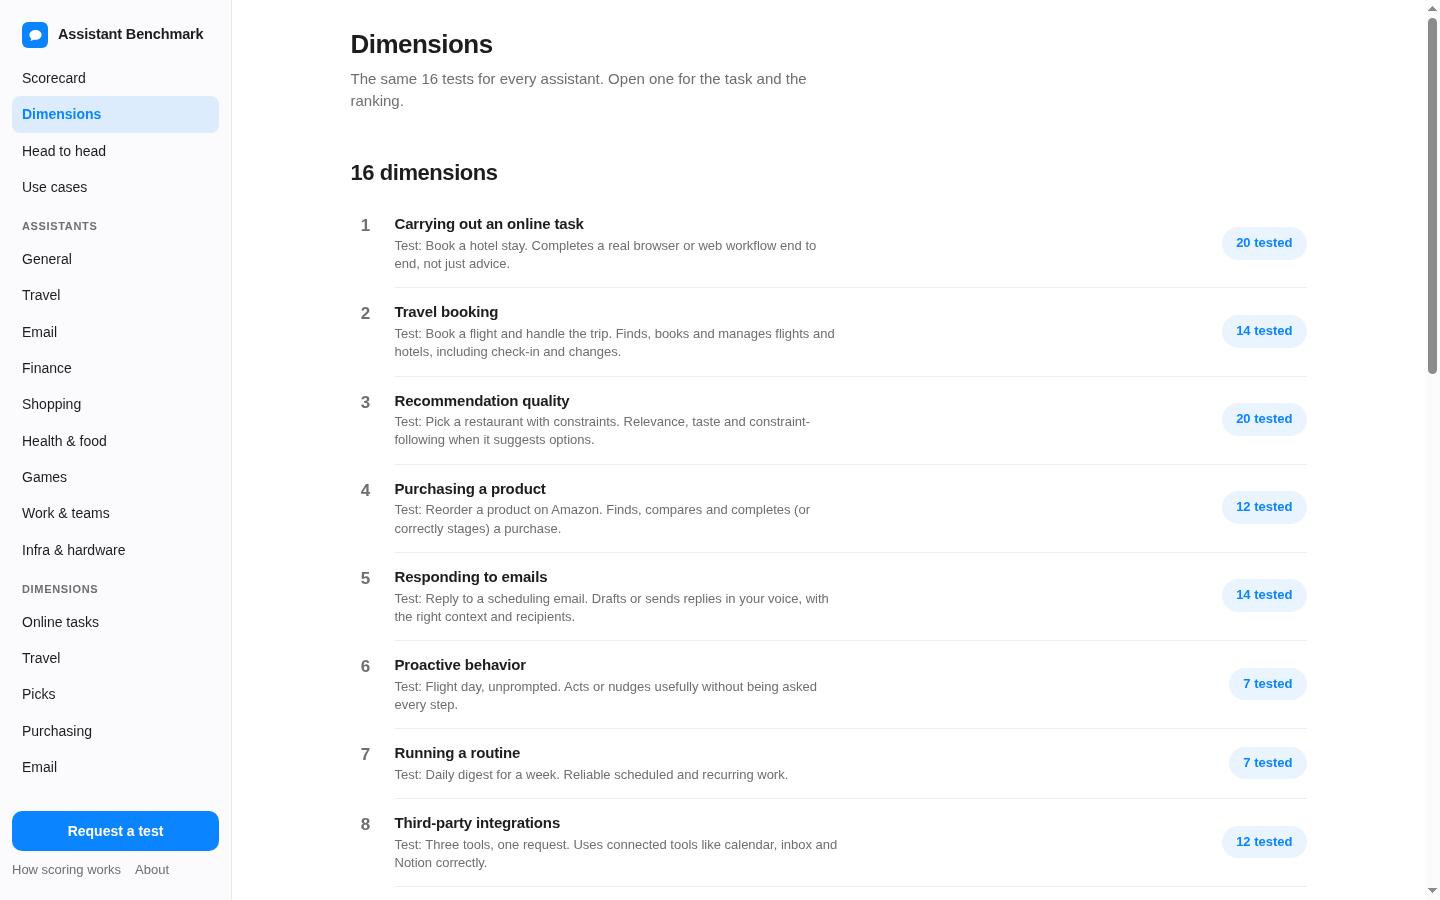
Assistant Benchmark 是一份面向「能用短信/聊天驱动生活」的 AI 助手对照表:同一套公开任务、真实账号实测、按维度打 1–10,未测就留空。v0.2 覆盖约 108 款助手、十余个维度(网购、差旅、邮件、主动提醒、权限、打电话等),并汇总大量公开用例引用。截至 2026-09-15,进行中榜单大致由 Muse、Instinct、szn、Pally/Ollie/Tomo、Grok Bot 等领跑;站点坚持无赞助、无付费插队。想挑助手或抄用例,直接看评分卡与 Use cases。
Assistant Benchmark — A free scorecard for the assistants you can text.
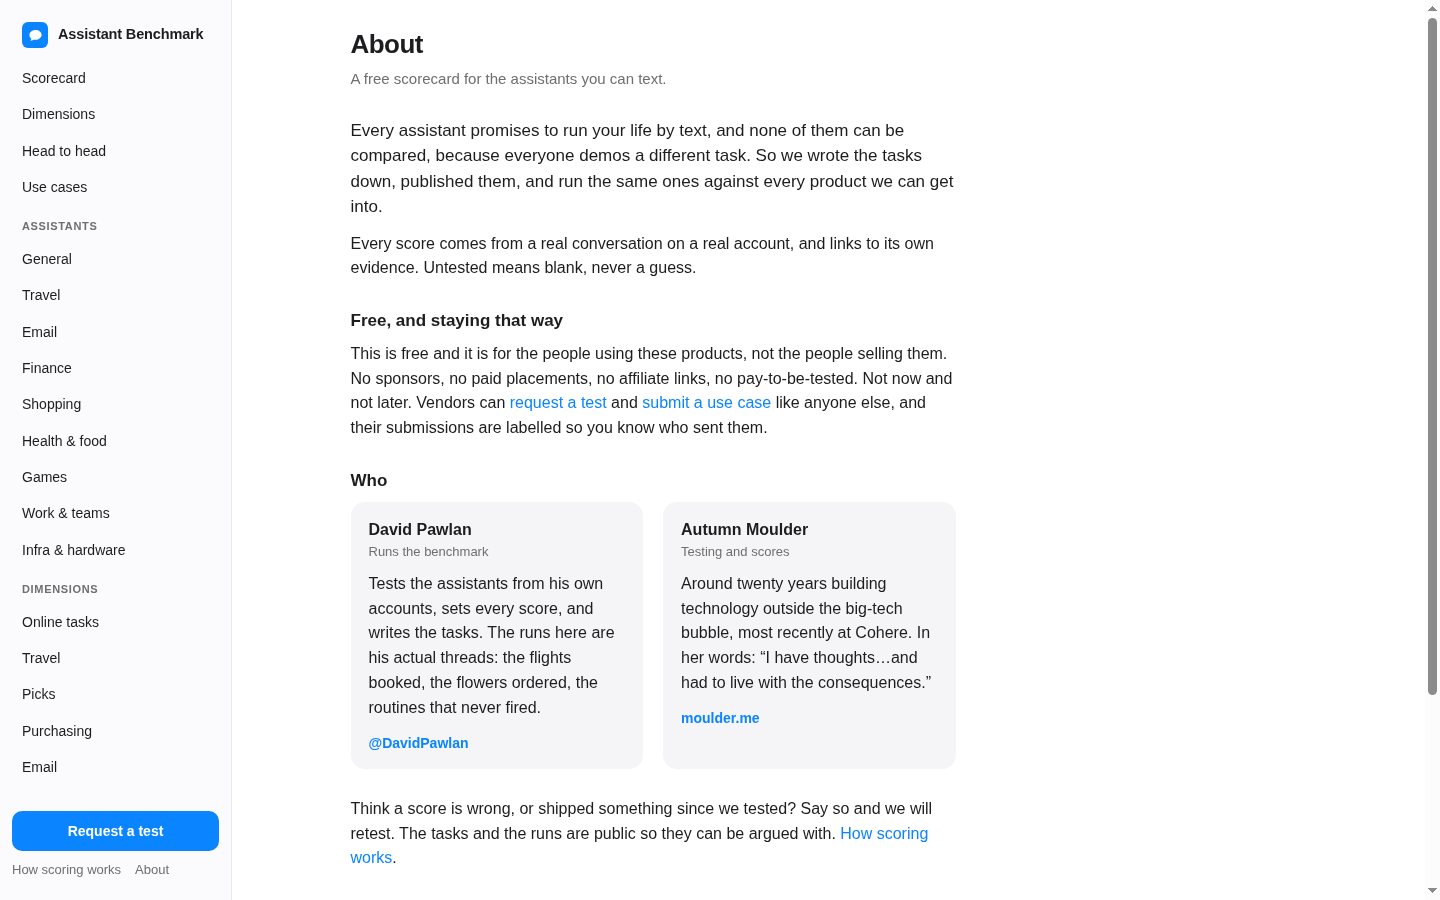
Every assistant promises to run your life by text, and none of them can be compared, because everyone demos a different task. So we wrote the tasks down, published them, and run the same ones against every product we can get into. Every score comes from a real conversation on a real account, and links to its own evidence. Untested means blank, never a guess.
Free, and staying that way: no sponsors, no paid placements, no affiliate links, no pay-to-be-tested.
Who: David Pawlan runs the benchmark and tests assistants from his own accounts. Autumn Moulder helps with testing and scores.
Benchmark v0.2 — 108 assistants, ~15–16 dimensions (online tasks, travel, picks, purchasing, email, proactive, routines, connected apps, permissions, memory, phone calls, group chats, multi-step, restraint, images), 180 runs. Last test Sep 14, 2026; updated Sep 15, 2026. Also surfaces thousands of public use-case quotes from X.
Leaders (in progress, partial means): Muse 9.1 (7/15), Instinct 8.4 (11/15), szn 8.0, Pally/Ollie/Tomo ~7.6, Grok Bot 7.3 (7/15).
Site: https://assistantbenchmark.com/