Terminal-Bench 2.0 论文与 Astra 表现
斯坦福与 Anthropic 发布终端环境 agent 基准,89 个任务暴露长程上下文漂移,平均解决率不足 45%。
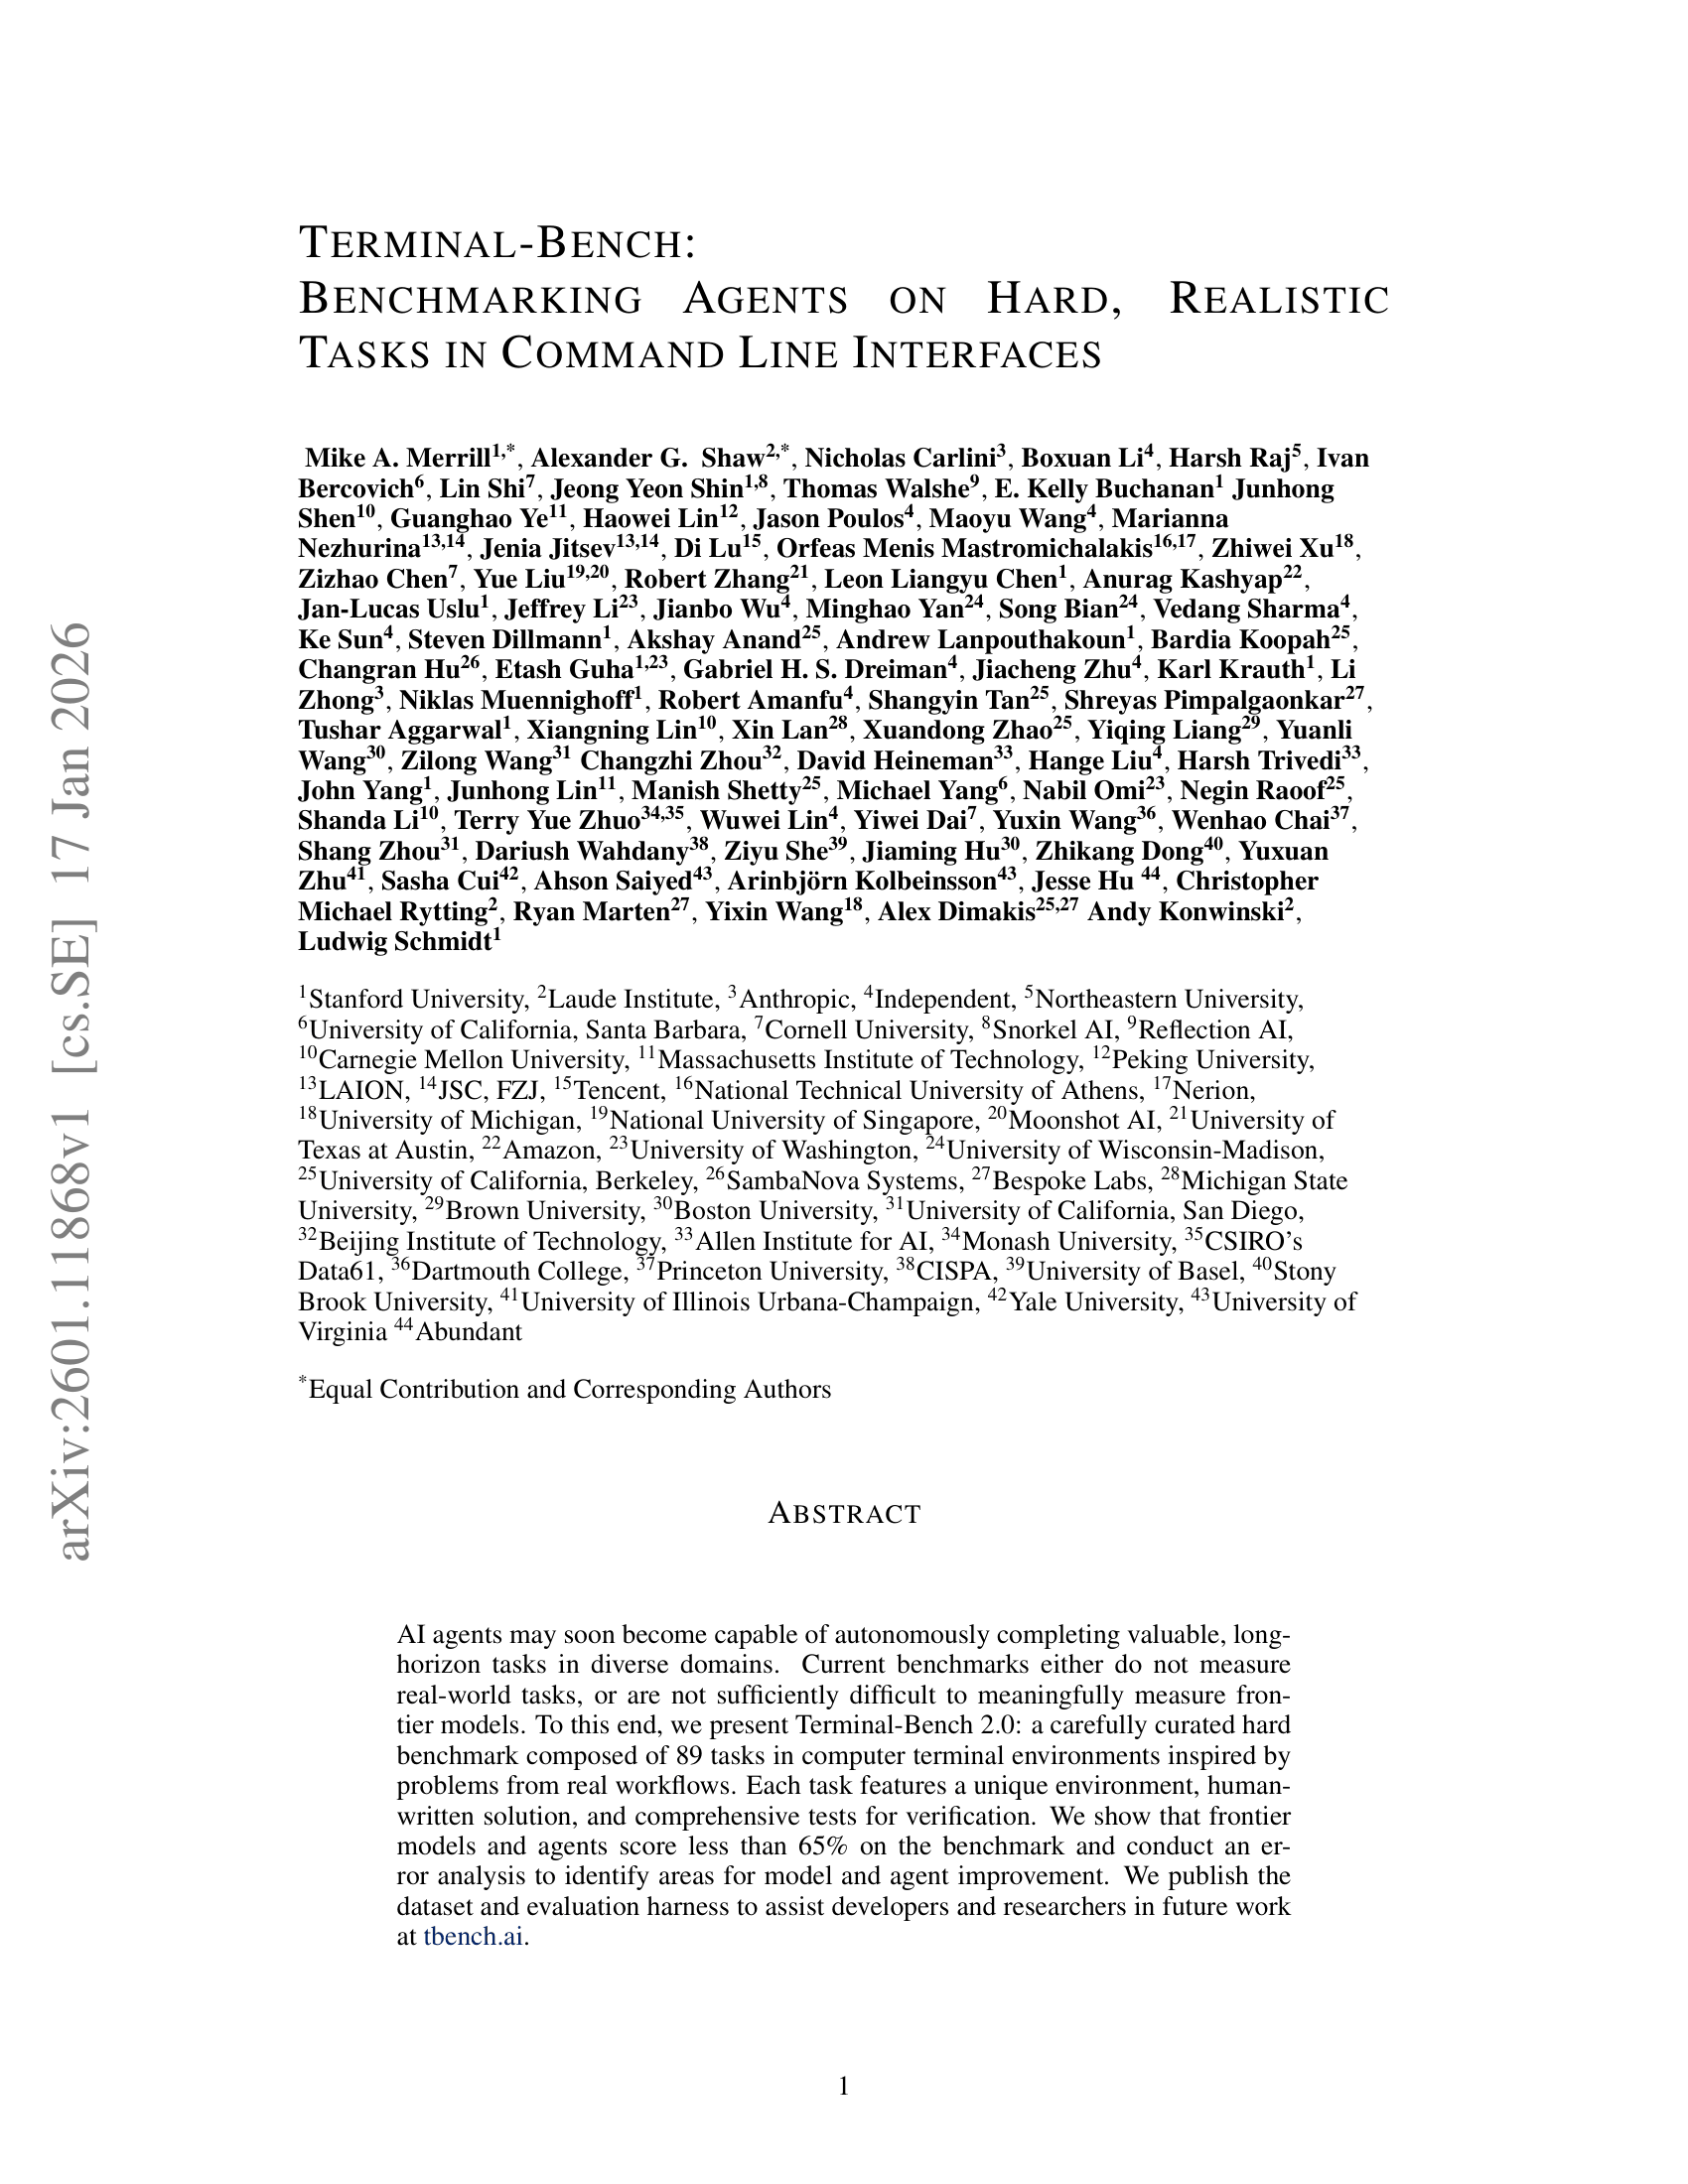
this paper is f*cking brilliant a joint team from Stanford and Anthropic released Terminal-Bench 2.0 to evaluate AI agents in real command-line terminal environments the result: 89 complex terminal tasks reveal huge performance gaps across top frontier models and agent scaffolds the crazy part is how real CLI execution environments expose agent failure modes agents execute terminal bash commands inside containerized sandboxes, but cascading tool errors and long-horizon context drift drop average resolution rates below 45% most coding benchmarks evaluate simple code completion or isolated unit test generation this benchmark tests autonomous agents inside a live interactive terminal shell read the complete paper + article about gpt-6 Astra below save it for future reference
这条是引用着另一条写的:x.com/beamnxw/status/2098087790663672123