今天新增gpt-6IMAGE
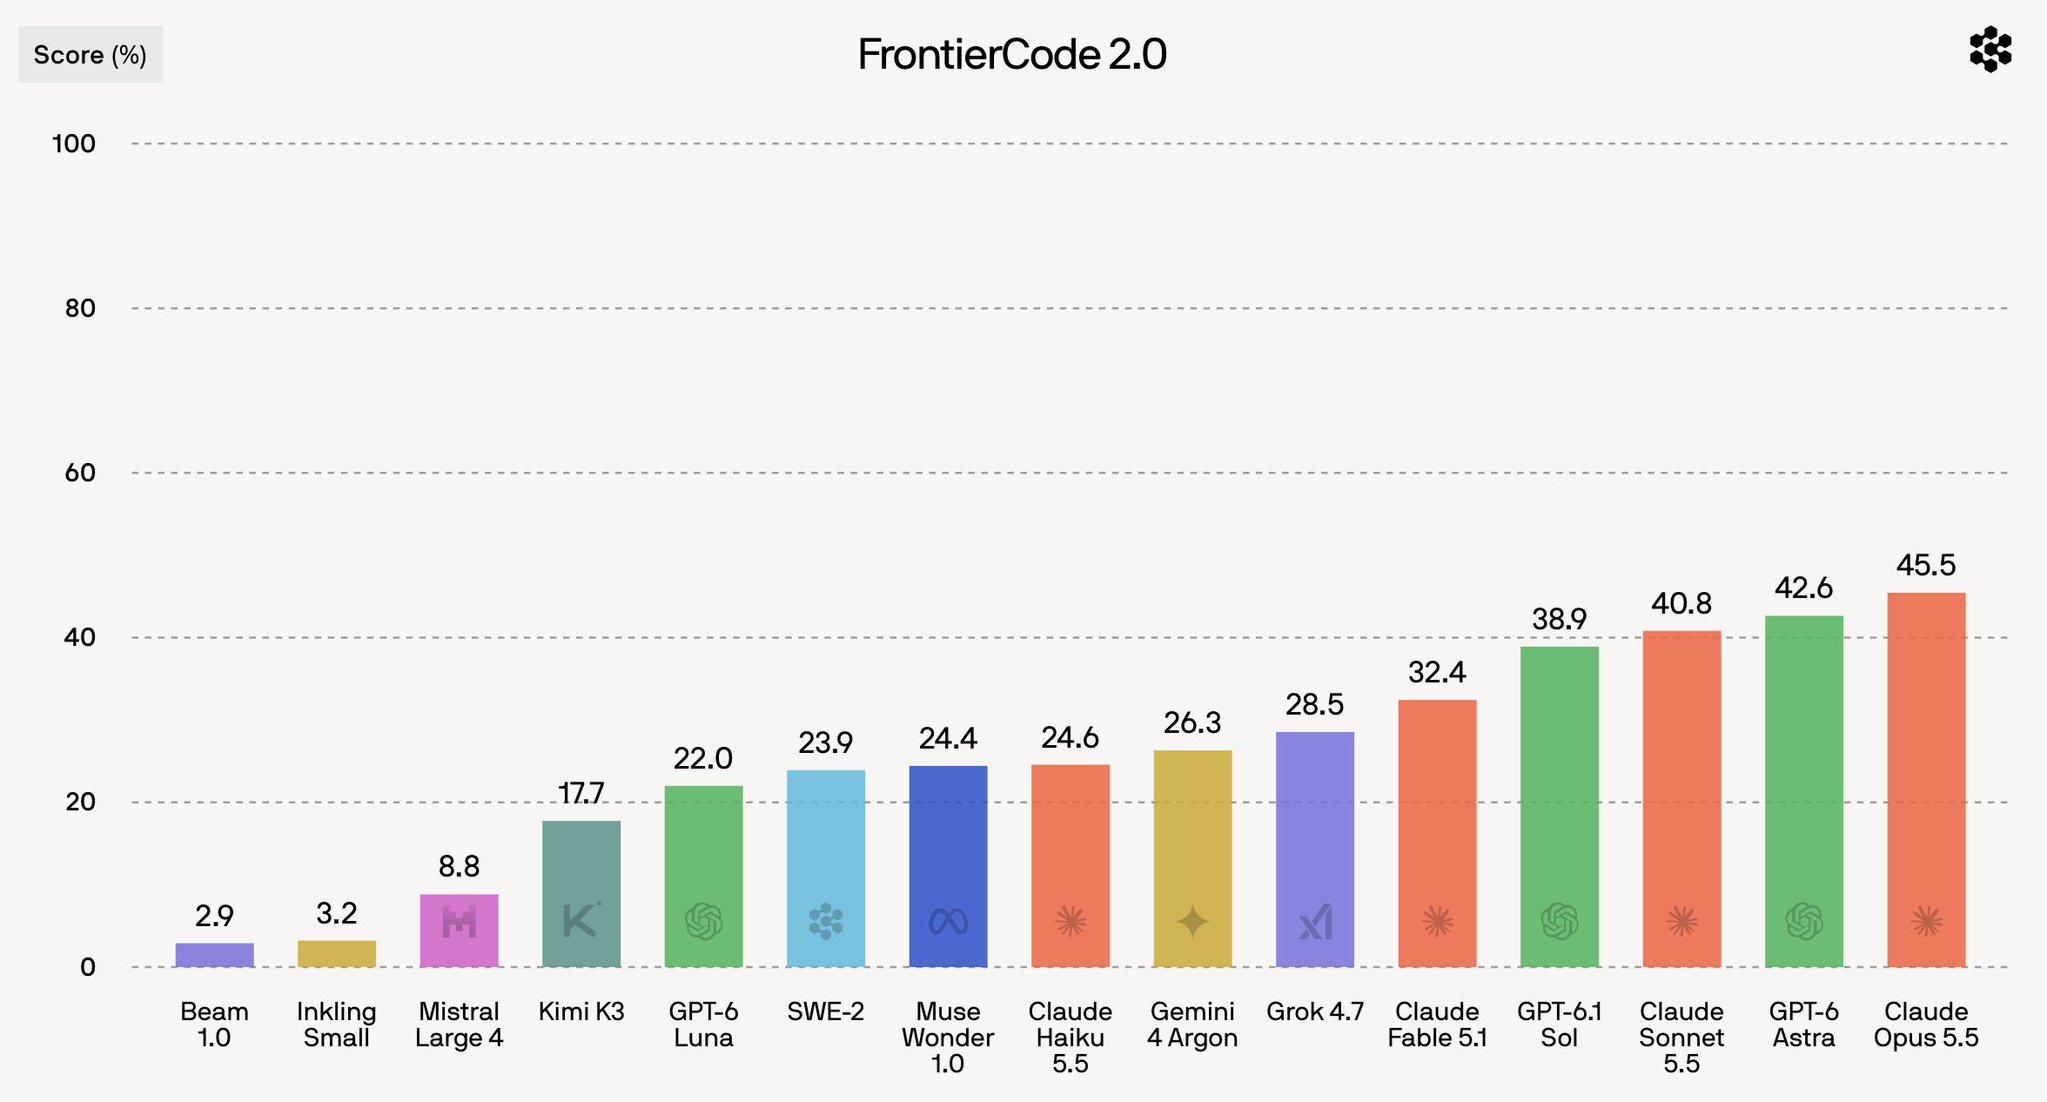
FrontierCode 2.0:Astra 42.8% 落后 Opus 5.5,推理拉满反而更差
新编码 agent 基准上 Opus 5.5 以 45.5% 领先、Astra 42.8%;同一 bug 上 Astra 低推理 5/5 通过,最高推理仅 1/5 还删了公开 API。
Choblin
@choblin298 小时前收录原推发布于 2026.10.28
Choblin @choblin29原推发布于 2026.10.28
Holy. Cognition has released FrontierCode 2.0, a tougher benchmark for AI coding agents. The results are brutal: Claude Opus 5.5 leads with just 45.5%, followed by GPT-6 Astra at 42.8%. Even crazier, MORE thinking made Astra worse. On one bug, it passed 5/5 attempts at low reasoning but just 1/5 at maximum, where it deleted a public API. Claude Opus 5.5 fixed another bug but failed ALL 25 attempts across five reasoning settings because it missed a critical cleanup requirement. Even when AI fixes the bug, it can break the code around it.
这条是引用着另一条写的:x.com/cognition/status/2115132488775524793
x.com/choblin29/status/2115142451140673703采集于 2026.10.28 10:11