Gemini 4 Argon 长对话额度实测:4 轮提示词烧光配额
开发者实测 Argon 在单条长对话中,第 4 轮提示词就要为 14 万累积输入 token 重复付费,缓存还会被终端日志击穿。
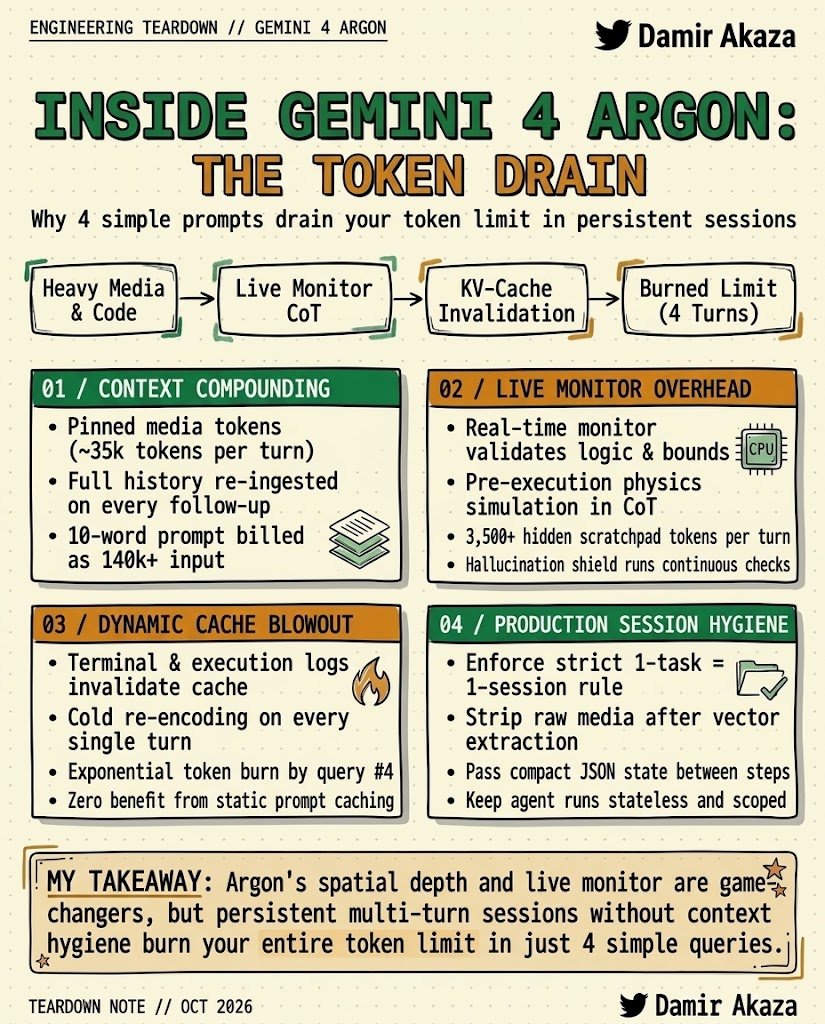
After the Gemini 4 Argon release, I started running it heavily in daily engineering workflows and hit a brutal reality. If you stay inside a single long-running chat, your token quota completely evaporates in just 4 simple prompts. Here is the factual breakdown of what is actually happening under the hood. 1. Compounded Context Re-Ingestion The model doesn't process follow-ups in isolation. Every new message forces it to re-read the entire conversation history from scratch. If turn #1 included a part photo, video clip, or code block, those heavy multimodal tokens (~35,000) stay pinned in memory. By prompt #4, when you type a casual "adjust the clearance by 2mm", you aren't paying for six words. You are paying for the full 140k+ accumulated input tokens. For the fourth time in a row. 2. Live Reasoning Monitor Overhead Argon has a record-low 2% shortcut rate, but that honesty comes at the user's expense. To verify the code isn't faking passing tests, the model runs extensive checks before emitting a single token: simulating geometry, validating tool bounds, and guarding against hallucinations. On screen, you see two neat lines of output. Behind the curtain, that micro-action burns 3,500+ hidden reasoning (CoT) tokens. 3. Cache Invalidation from Terminal Logs In theory, context caching should prevent double-paying for prior context. In real engineering work, it constantly breaks. The moment the model executes a script, throws a compiler error, or outputs terminal logs, dynamic timestamps destroy the static prefix. The cache drops to zero. Instead of cheap cached reads, the system triggers a heavy, cold re-encoding of the full session every single time. How I changed my production workflow: > 1 Task = 1 Fresh Chat. Stop treating a single chat as an all-day IDE console. > Strip media baggage. Once the model extracts dimensions or 3D coordinates, drop the source media from context. > Pass clean state, not noise. Hand off a compact JSON summary between steps instead of 20 pages of terminal logs. Gemini 4 Argon delivers incredible 3D spatial physics and agent honesty, but its architecture is heavily front-loaded. Without strict session hygiene, the live monitor and accumulated context will burn your budget on minor tweaks before you even touch production code.