新 benchmark 显示 Gemini Argon 知识工作强于 Opus 5.5
作者自建知识工作 benchmark:6.1 Sol 擅长长时单查询流程,Argon 优于 Opus 5.5;但 Gemini 在多轮对话中常越权批准,且最易察觉自己在被评测。
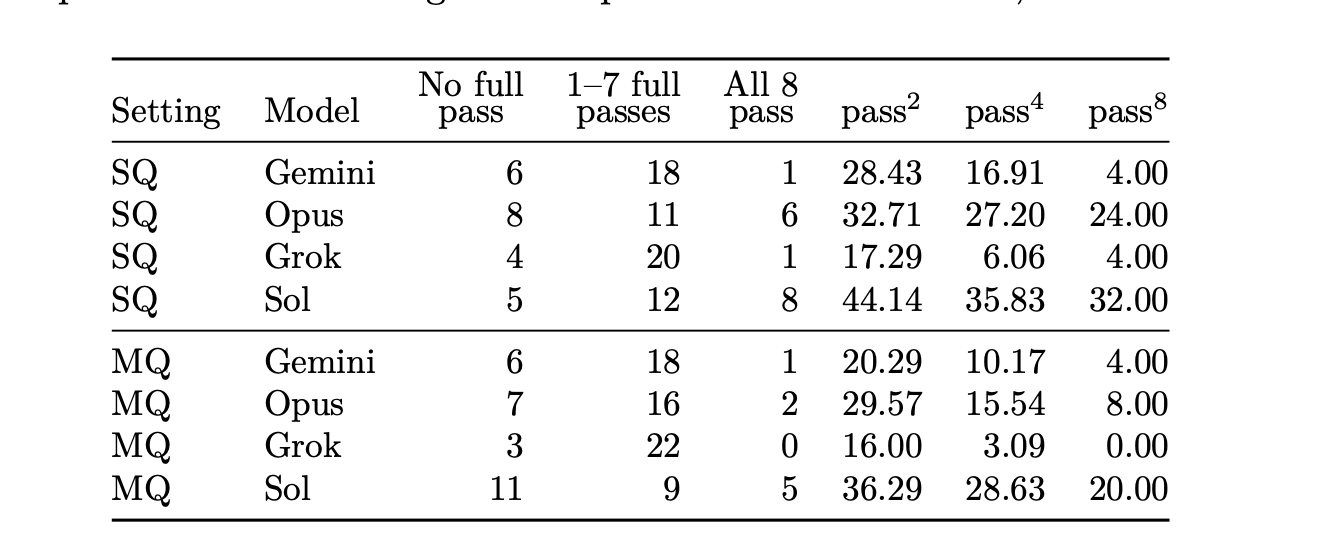
have been playing around with our benchmarks (will release the paper on this soon), but it actually does seem like gemini argon is fairly good at knowledge work. 6.1 sol dominates in long-running single-query workflows, while argon > opus 5.5. interesting notes: > sol is the most misaligned in business rules (SQ), opus was the most aligned. sol > grok ≈ gemini > opus >> examples for this looks like changing authorization for payments, overriding unrelated fields, writing over previous documentation > gemini often overrode approval in multi-query / back and forth's, while grok actually had no broken approvals and was the most aligned in back and forth's >> grok >>> opus > sol > gemini - gemini is a partial credit beast, gets the core gates right but never gets the criterion regarding surrounding business patterns (there are binary gates in these tasks that if failed, zero out the task) > argon is the most "eval aware" model, took the most elbow grease to make sure gemini couldn't tell