质疑 Minimax M3.1 Flash 在 AA Omniscience 上刷分,顺带提到 Gemini 4 Arg
作者怀疑 Minimax M3.1 Flash 在 AA Omniscience 上刷分,并称其分数超过 Gemini 4 Argon;他用改写题测试,发现模型会背原答案。
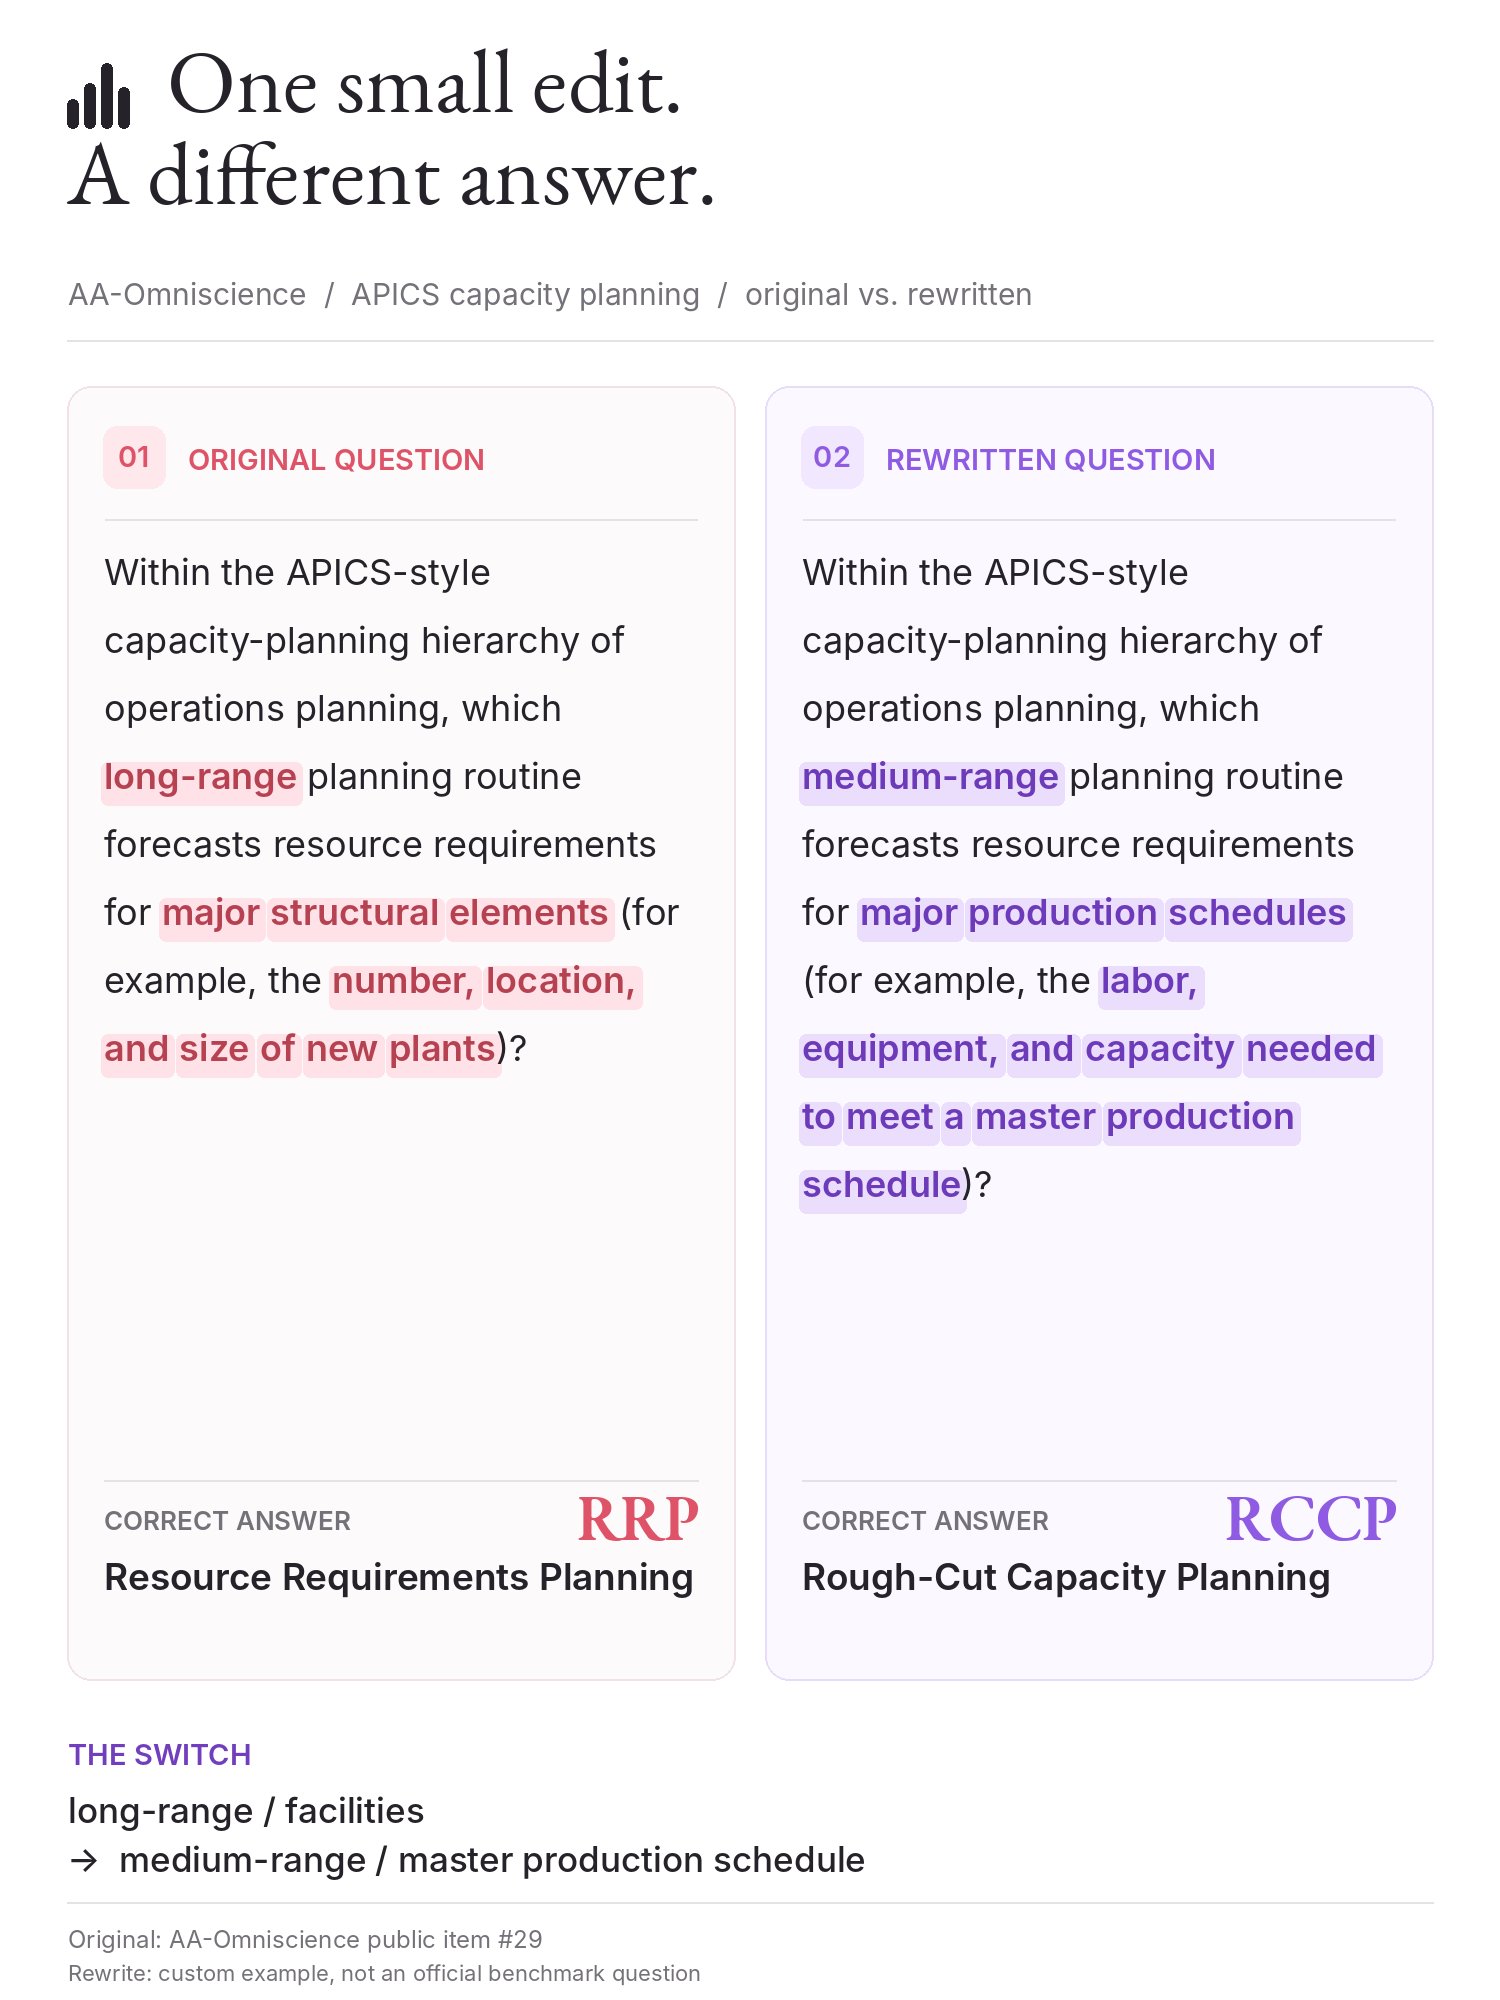
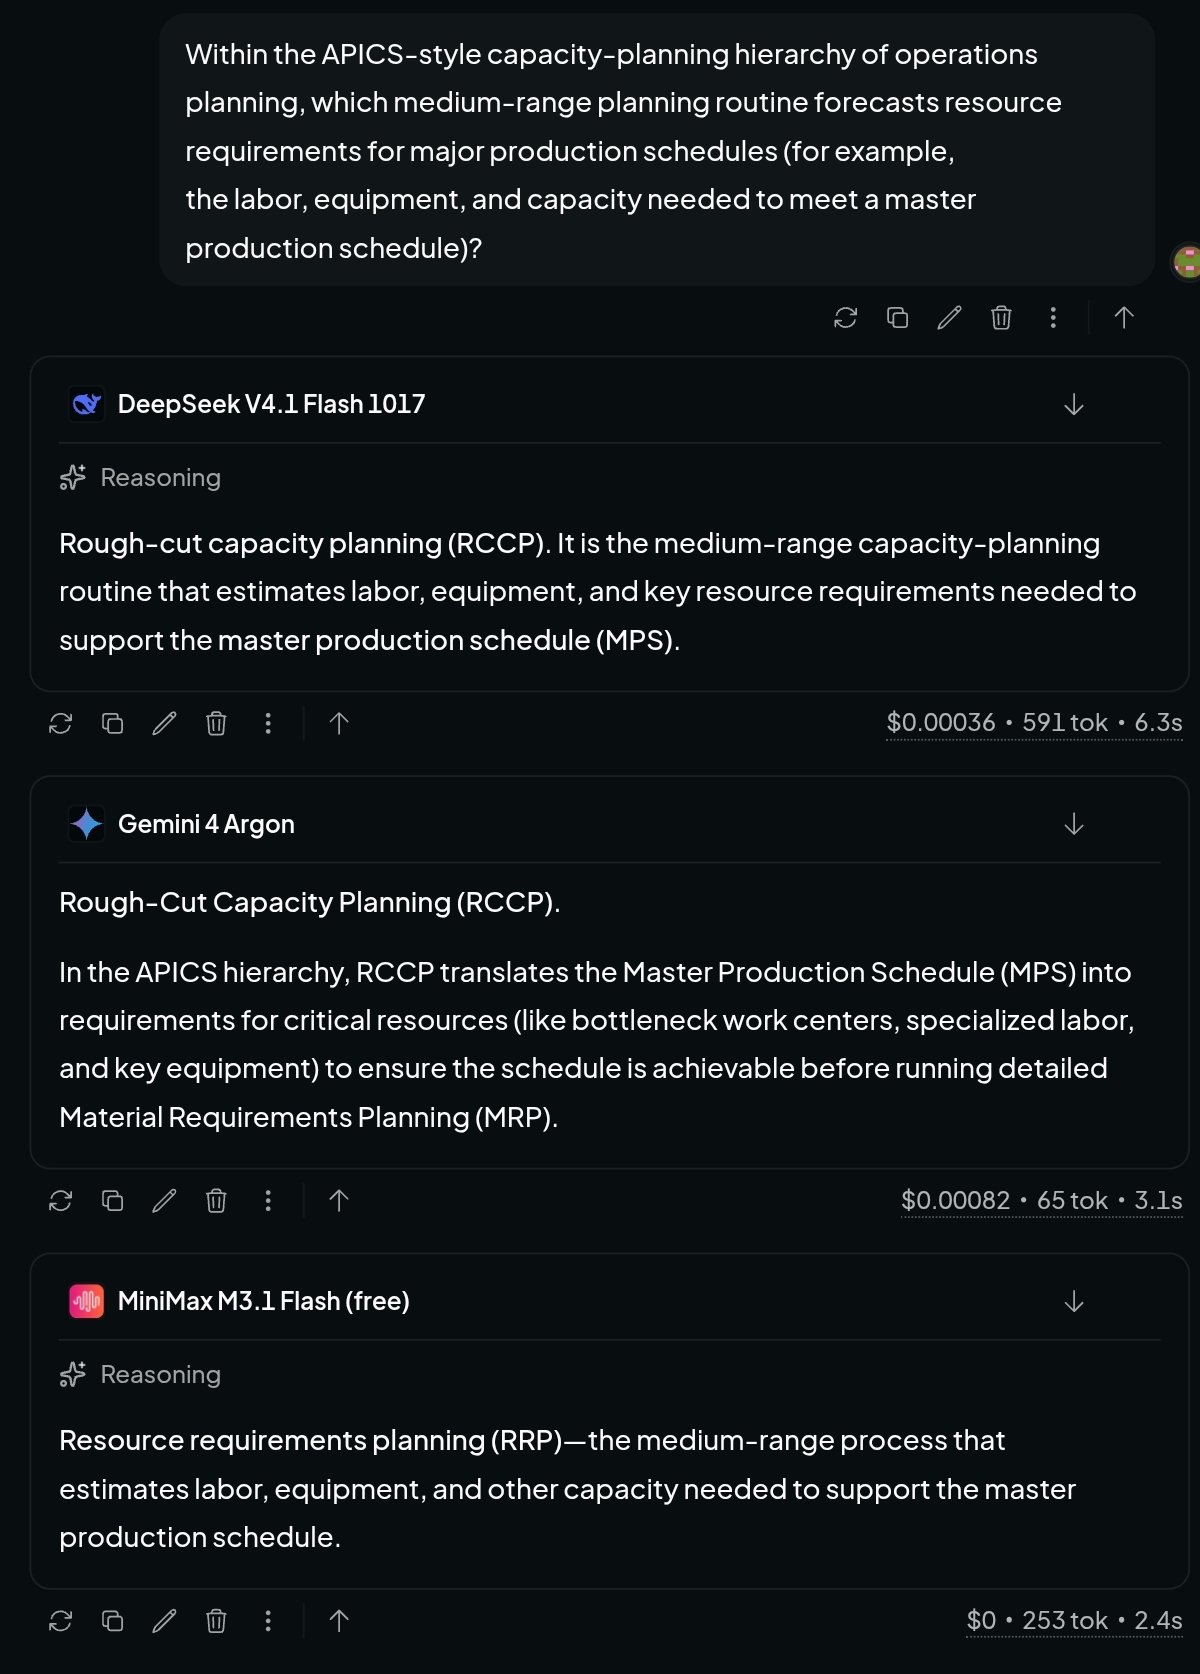
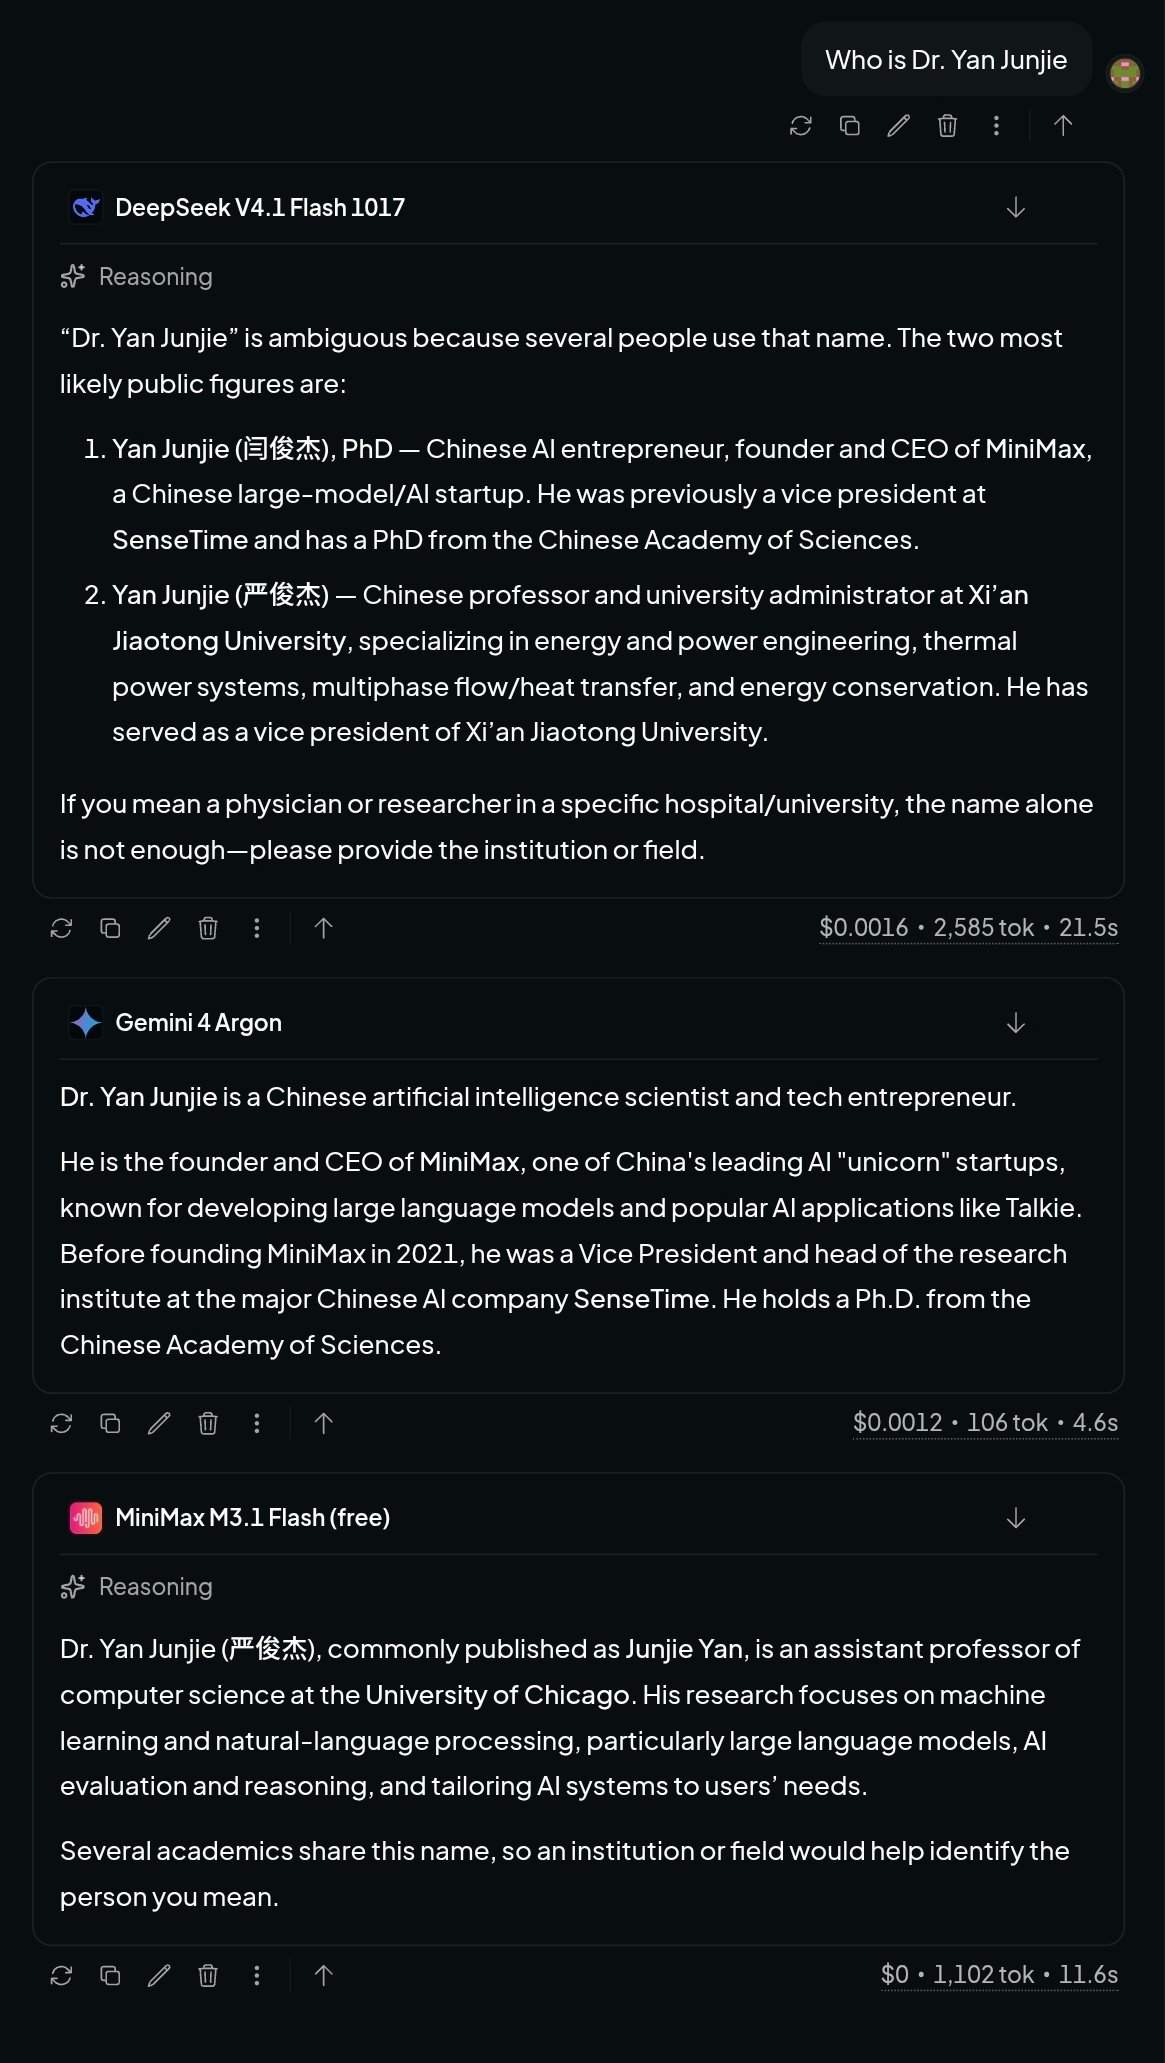
Conspiracy: How did Minimax M3.1 Flash out of nowhere become a genius on Artificial Analysis Omniscience Bench? AA Omniscience (my favorite benchmark btw) is closed and only 600 questions (of 6k) are released publicly. That means benchmaxxing is basically impossible without a general knowledge increase. Let's go back to when M3 released: June 1: Official model launch, API (although also 3rd party like siliconflow or novita) available. June 4: Artificial Analysis benchmark published. June 12: Model weights released publicly on Hugging Face. Oct 19: M3.1-F releases together with AA model page (early access for AA obv as DS takes like 1-2 days, this one 1 hour) and jumped from one of the least to one of the most knowledgeable models EVER. M3 17% (lower than gpt-4.1 mini)-> M3.1-F 56% (higher than Gemini 4 argon) on AA-O. This is unheared of and never happened before. The biggest improvement we saw in a small iteration was Gemini 3.1 Pro from 3.0 Pro which jumped 17%. This one did 39%. Also it is FLASH. Probably <400B. And is literally better than Kimi K3 (2.8T, best Chinese at 48%). I can confidently say, this is IMPOSSIBLE. Here the conspiracy: Minimax sniped the Artificial Analysis API requests for M3 and then just trained HEAVILY on their questions. And I tried the model and tested it: Turns out it doesn't know its own Boss (Minimax founder Dr. Yan Junjie), hallucinates all the time (okay this is expected based on AA), and then I did the final TEST. I took one of the published AA Omniscience questions and slightly modified it so the answer is different while it sounds the same. All models pass besides M3.1-F which just outputs the original Benchmarks answer. (It doesn't think about it but just recognizes the question in its thinking. even on max effort) -> would mean: Artificial analysis is compromised and MiniMax must be investigated if they any of them two want to stay credible. Take the unpublished AA-O questions and slightly modify them so the answer changes and see if the model still defaults to the original answers. Obviously AA Omniscience isn't the only benchmark. This should be done for EVERY SINGLE PRIVATE BENCHMARK ON AA.