Astra 写出 megakernel,刷新 RTX PRO 6000 纪录
Astra 在 Codex CLI 里花 5 小时写出一个 megakernel,Kimi-Linear Decode 跑到 PyTorch 基线的 24.80 倍,超过 Fable 5 的 24.61 倍。
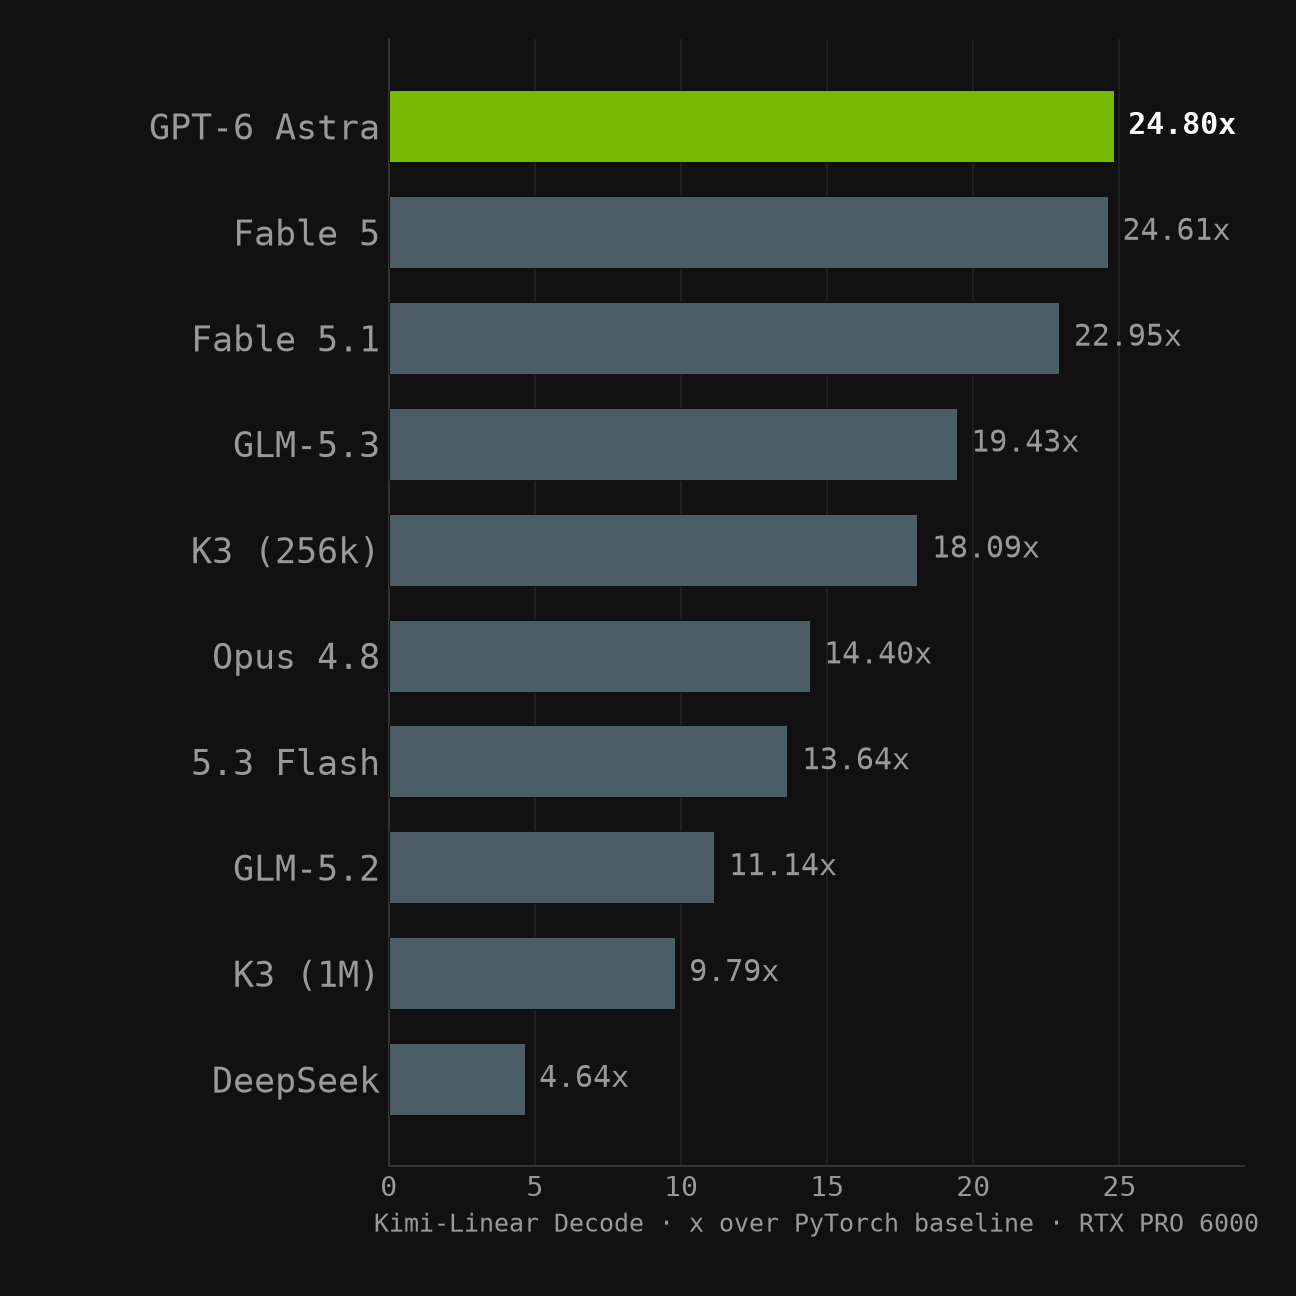
GPT-6 Astra wrote the megakernel that takes the RTX PRO 6000 Mega lead from Anthropic. It was tested on: Kimi-Linear Decode for RTX PRO 6000. 24.80x the optimized PyTorch baseline. > Claude Fable 5 at 24.61x, the July record > Claude Fable 5.1 at 22.95x > GLM-5.3 at 19.435x One cooperative launch, 376 blocks x 256 threads, 13 grid.sync() barriers. Scalar-FMA int4 GEMVs; tensor cores only for absorbed-MLA attention, with cp.async double buffering. KDA state updates, both RMSNorms and routed/shared MoE experts stay inside that launch. 23.66x / 24.95x / 25.85x at 2K / 8K / 16K context, 0.323 to 0.359 ms per token. Fable 5.1 used a hand-rolled task queue and tensor-core dequant GEMVs. Astra beats it with grid.sync() phases and scalar FMA on the bandwidth-bound batch-1 GEMVs. Cosine 1.0000 on all six check combos. It reverted two faster variants that fell to 0.983 to 0.9997. codex CLI 0.140.0 on OpenRouter, model openai/gpt-6-astra-pro, effort xhigh. 5h05m, 489,551 output tokens, $83.75. Ended on its own task_complete. https://kernelbench.com/mega