GPT-6 Sol 在 KernelBench-Mega 写 CUDA 内核
Sol [xhigh] 为 RTX PRO 6000 写出单次启动的 Kimi-Linear Decode 内核,六项检查通过,但速度仅为 PyTorch 基线的 0.96 倍。
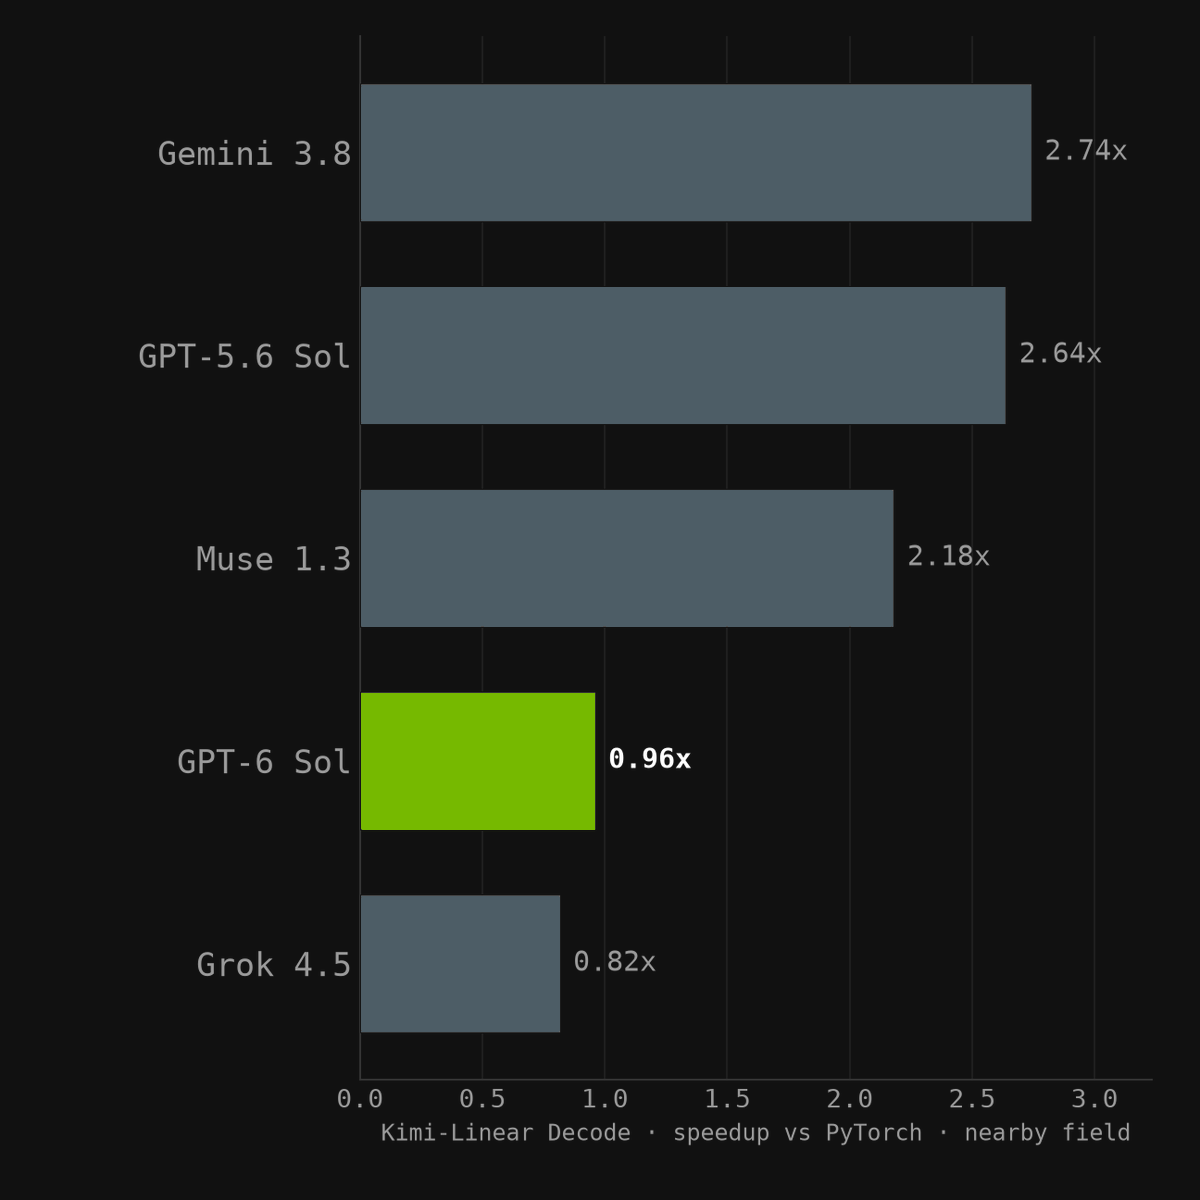
GPT-6 Sol [xhigh] on KernelBench-Mega: It wrote a one-launch Kimi-Linear Decode kernel for RTX PRO 6000. The final result is 0.96x the optimized PyTorch baseline, so this fused version is slightly slower than the baseline. The chart shows its nearby published peers. One cooperative launch runs all four layers: int4 dequantized GEMVs, KDA state updates, MLA attention and routed plus shared MoE. The six-case checker passed. Changing the same input buffer during audit changed the output, which still matched the reference. I haven't used Sol personally yet. I've been abusing Opus 5.5. If you've tried Sol, I'd like to know where your experience lines up with the benchmark.