Jev 省 LLM 账单的 6 个决策工作流
票务路由、内容审核、AI 评审、工具调用风控、模型路由、文档矛盾审计,把「从列表里选一个」的步骤交给 Jev 打分,省掉输出 token。
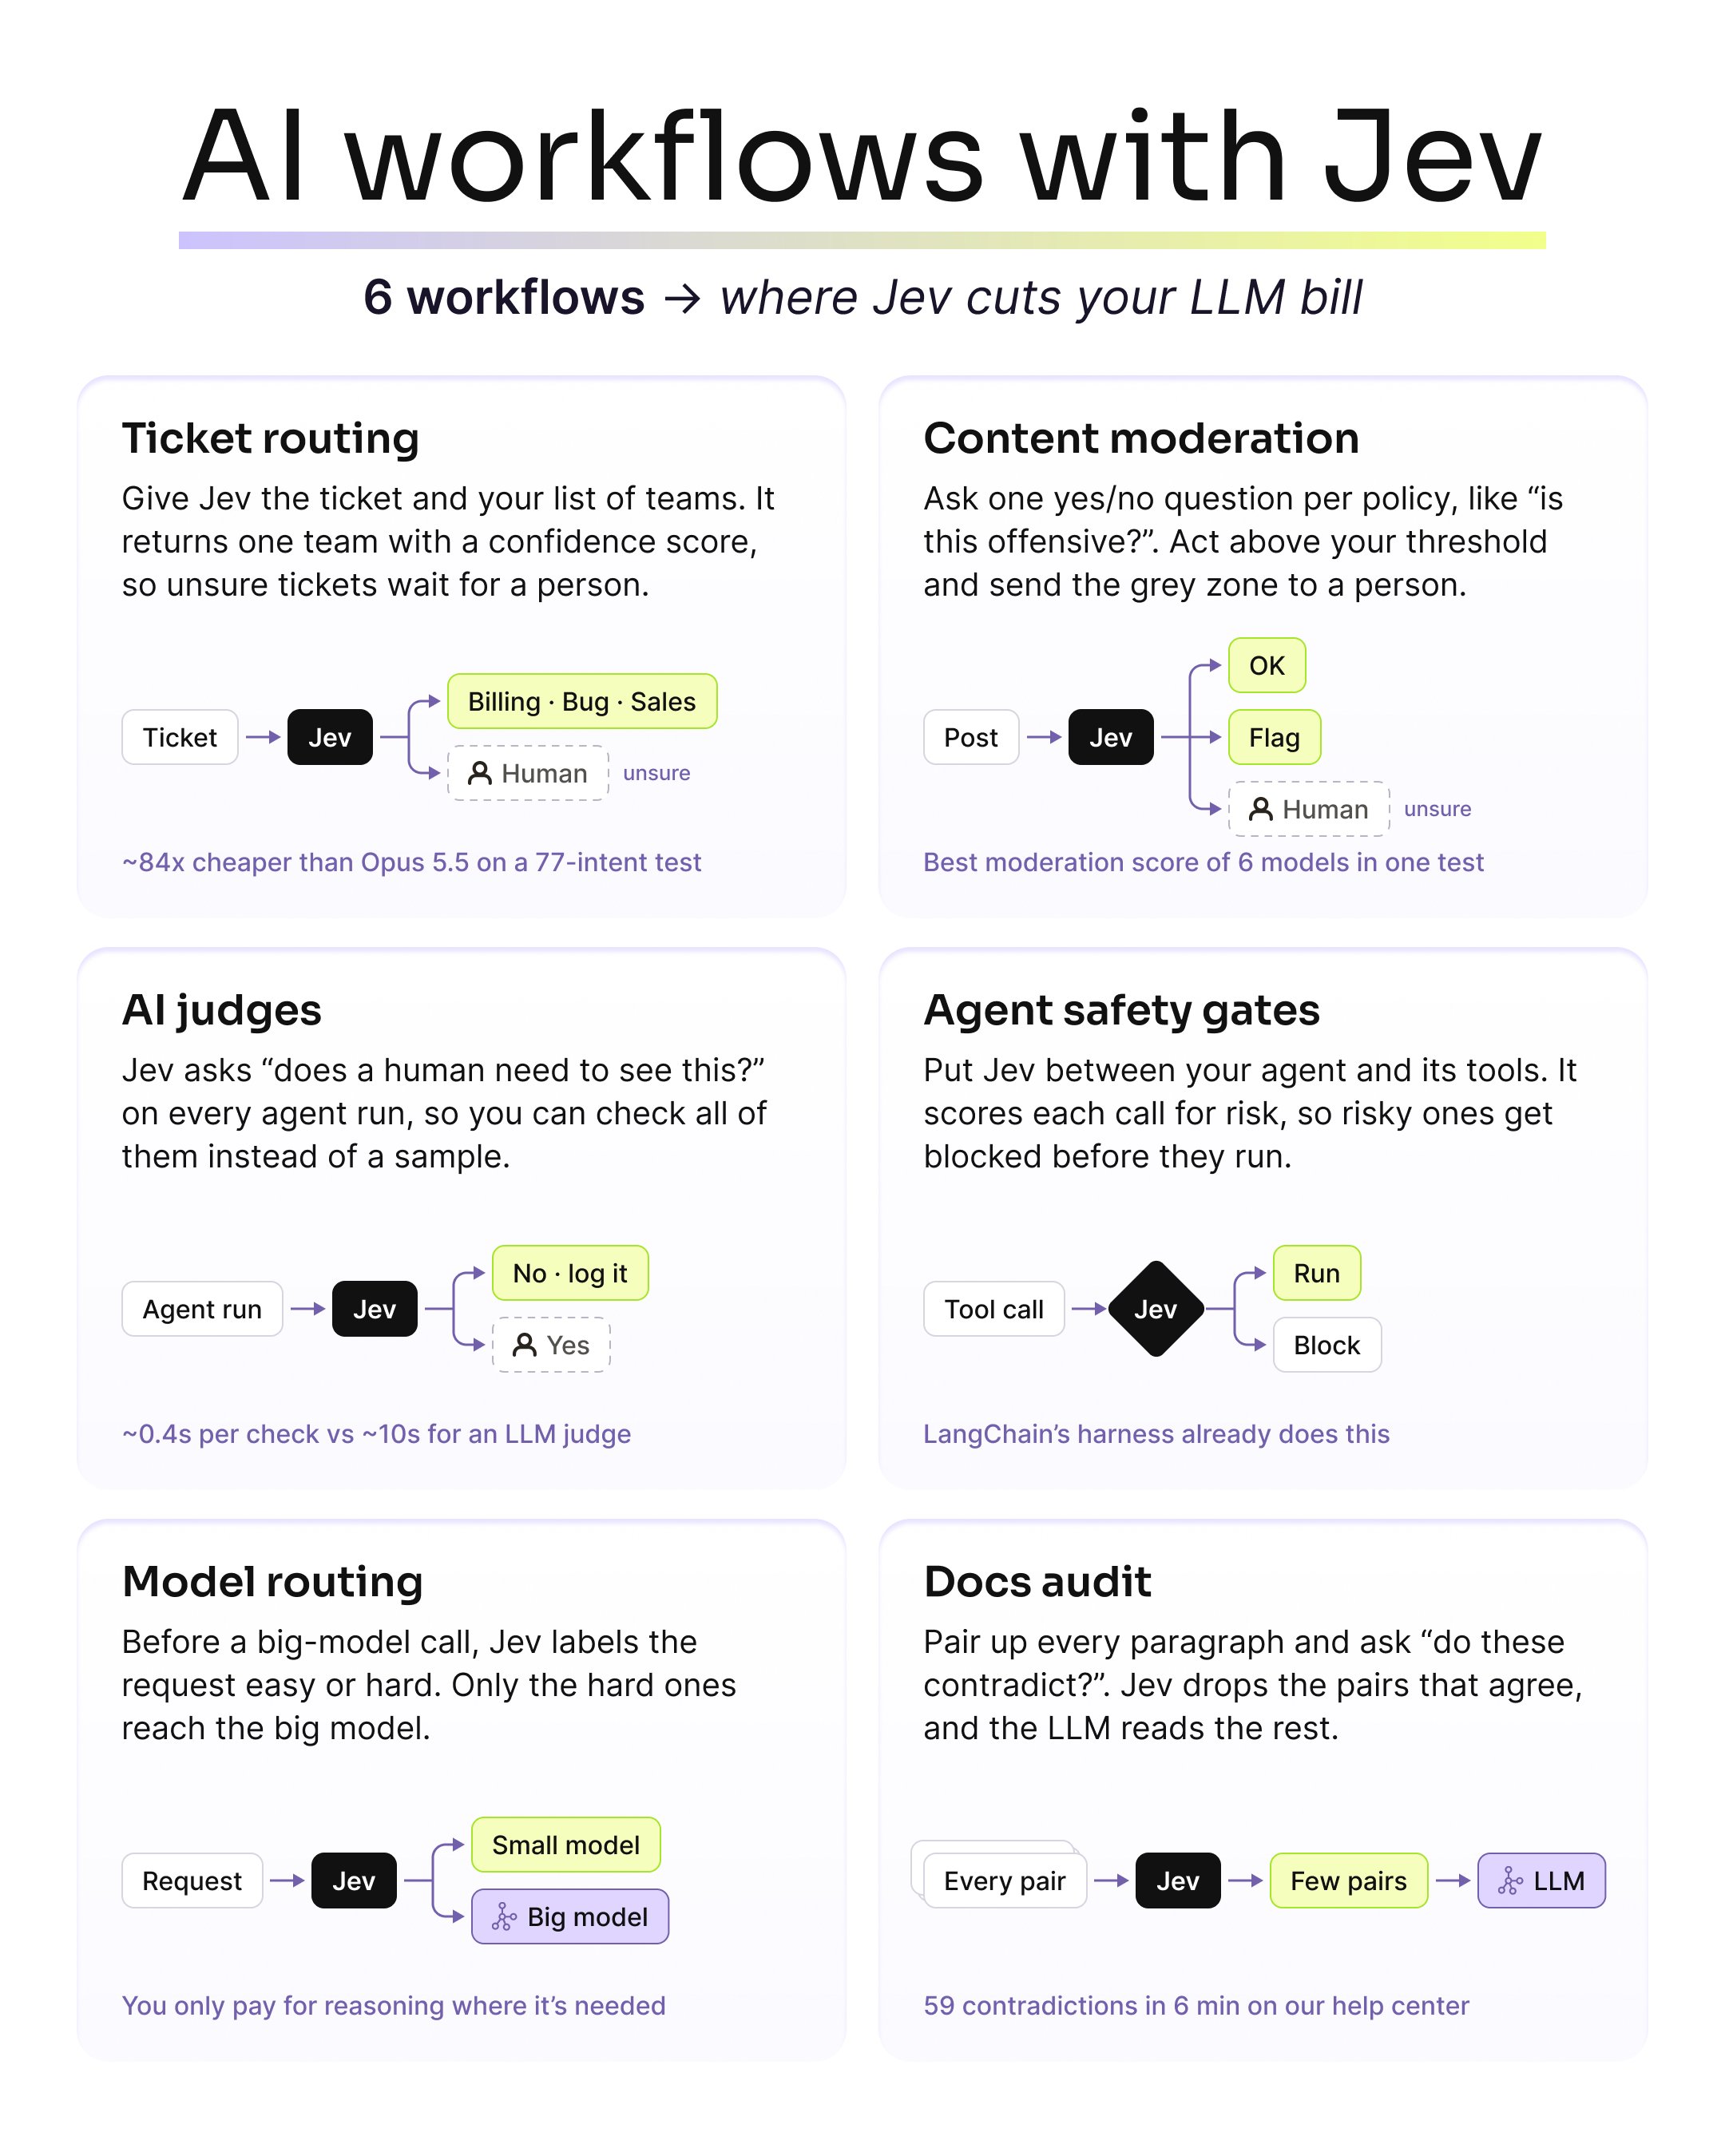
6 AI workflows where Jev cuts your LLM bill: (each one has a step that only picks an answer from a list) That step usually goes to an LLM, which writes a full answer you then have to parse. Jev, TypeSafe AI's decision model, skips the writing: it scores the allowed answers and hands back a choice, a score or a yes/no probability. No output tokens to pay for, and a decision takes about 70 to 500ms. /1 Ticket routing Pick the team from your list and let unsure tickets wait for a person. In one public test it was ~84x cheaper than Opus 5.5 across 77 intents. /2 Content moderation One yes/no question per policy, with the grey zone going to a person. It had the best moderation score of the 6 models in that same test. /3 AI judges Ask “does a human need to see this?” on every agent run instead of a sample. TypeSafe's evals with Arize put it at ~0.4s per check, against ~10s for an LLM judge. /4 Agent safety gates Score each tool call for risk before it runs. LangChain's harness already works this way. /5 Model routing Label each request easy or hard, so only the hard ones reach the big model and you pay for reasoning where it's needed. /6 Docs audit Ask “do these two paragraphs contradict?” for every pair, and let the LLM read only what's left. On our help center, that surfaced 59 contradictions in 6 minutes. We tried it ourselves too, and cost per run dropped 87% while it got twice as fast. One catch: on nuanced quality scoring it came last in that same public test. So run it side by side with your current LLM on a few hundred real cases before switching anything. Which of these still runs on an LLM in your stack? 💸