开发者IMAGE
NVIDIA Flare:面向 DGX Spark 的本地推理引擎
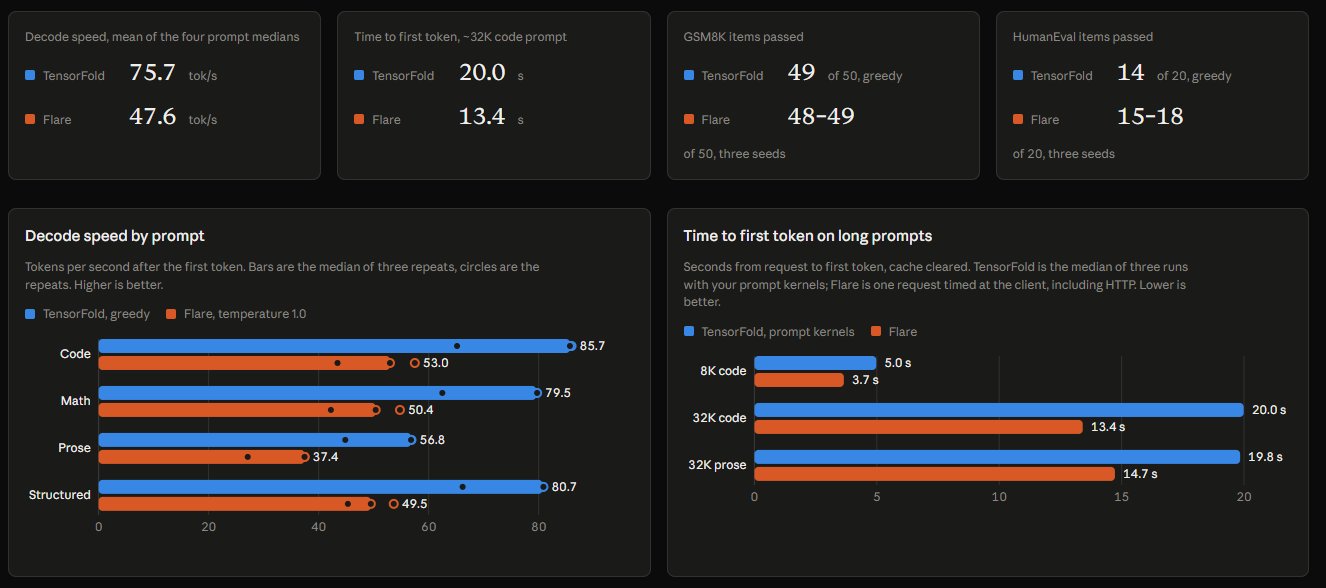
NVIDIA 推出 DGX Spark 专用本地推理引擎 Flare,实测解码 47.6 tok/s 落后 TensorFold 的 75.7,但 32k 长提示首 token 快 1.5 倍,且温度被锁定为 1.0。
filipe
@filicroval5 天前收录原推发布于 2026.10.23
filipe @filicroval原推发布于 2026.10.23
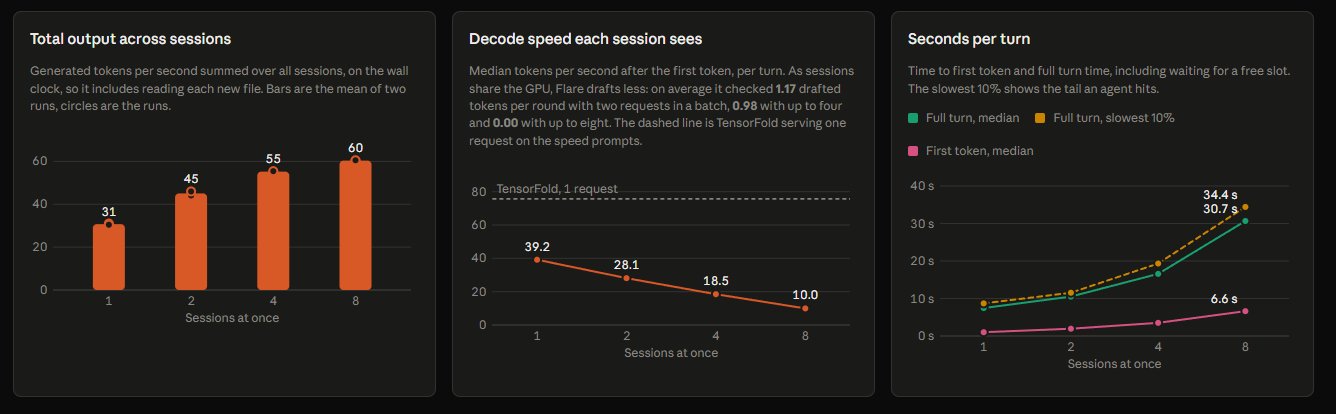
nvidia shipped flare, a local inference engine built for the dgx spark. so i ran it head to head against my tensorfold setup. same box, same model (qwen3.8-flash-next, 125b moe), same frozen prompts, hash-checked. → decode: tensorfold 75.7 tok/s. flare 47.6 (51.9 after tuning) → long prompts: flare wins, first token 1.5x faster at 32k → quality: dead tie on gsm8k + humaneval → 8 agents at once: flare only doubles total output. each agent gets 4x slower the catch: the shipped package locks temperature at 1.0. no greedy. its draft tokens miss more, so it stops guessing ahead.
x.com/filicroval/status/2113387171747070462采集于 2026.10.24 10:26