提议做多模态 Jev:给图和文本打分
作者设想把 Jev 扩展成多模态打分模型,对任意图片与文本输出契合度分数,并支持校准与是/否判断。
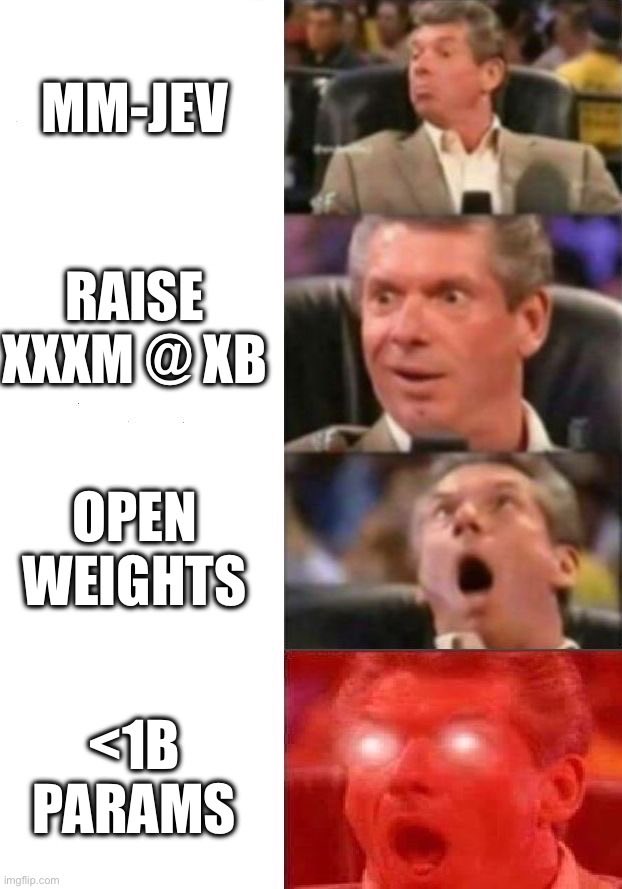
Guys hear me out: Jev, but multimodal! Imagine there was a model that you can give any image, and any set of freeform texts, and it would return you for each text, how well it fits the image. It could also do a set of yes/no (Noul) by using sigmoid in the right places. And the scores could be calibrated! I think i should be able to do this, though i might need to raise xxxM. But as one of the inventors of vision encoders but also one of their biggest haters because i know better, i can pull this off. And now imagine i would manage to open-weight it, wouldn't that be awesome? And EVEN BETTER, imagine i could do it with fewer than 1B params?! Maybe like 400m or so? I think I'm onto something here, wdyt??