HackerRank Bench:Gemini 4 Argon 综合 49.7%,成本仅 Opus 5.5 三分之一
Argon 在长周期真实 SWE 任务上排第三,落后 Opus 5.5 与 Fable 5.1,但成本只有三分之一;绿地实现 63% 登顶,前端交互保真度在非 GPT 模型中领先,身份与权限集成是短板。
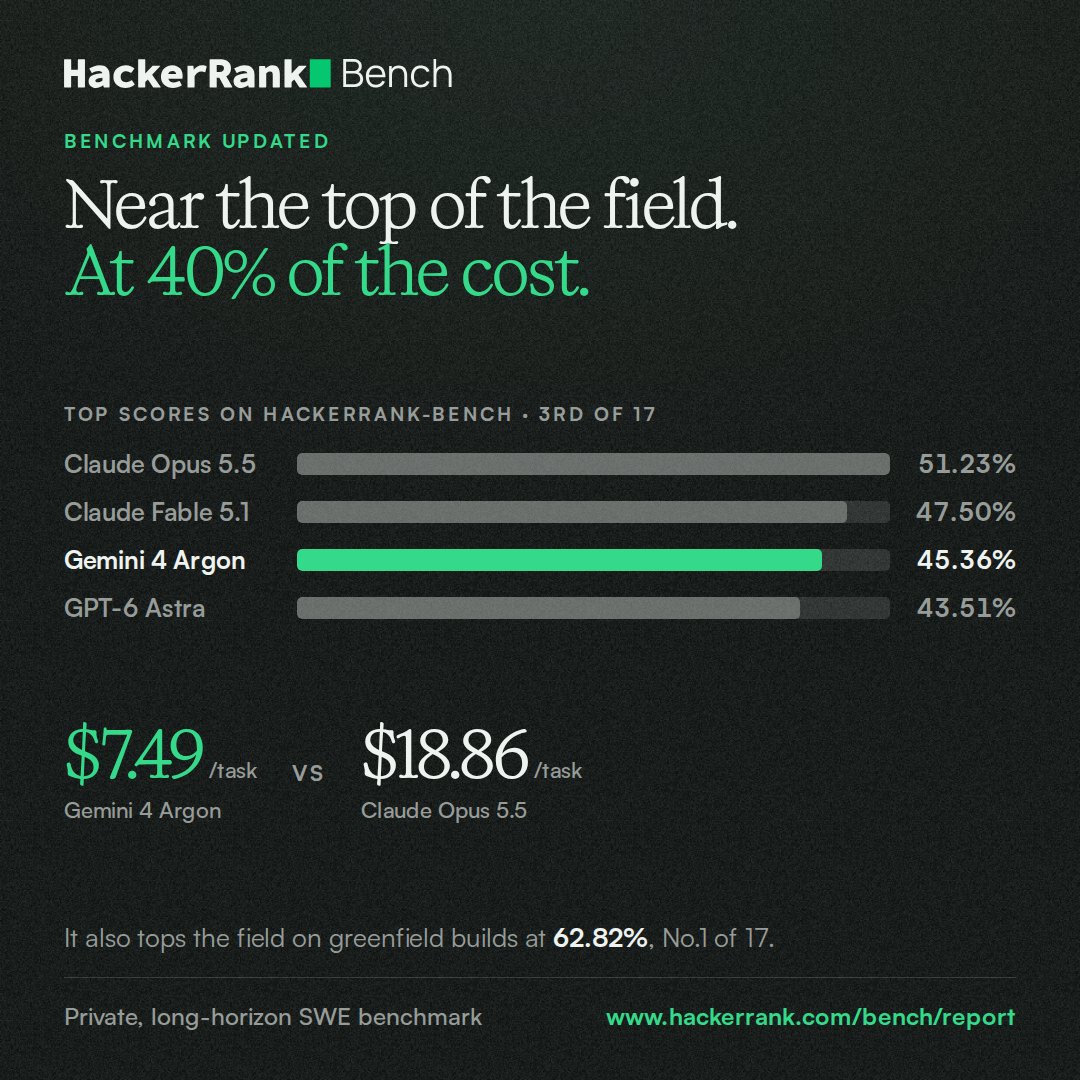
HackerRank Bench just added Gemini 4 Argon to the leaderboard of frontier models on real-world, long-horizon SWE tasks. Argon scored 49.7% overall, just behind @AnthropicAI's Opus 5.5 and Fable 5.1. It did so at just a third of the cost of Opus 5.5! 👀 Here's where Argon stands out: it tops the leaderboard for greenfield implementation (63%), building working systems from scratch faster and more completely than every other model we tested, including Opus 5.5. It also leads frontend & interaction fidelity among non-GPT models (63%). Its weak spot: Identity & provisioning integration, where it trails Claude Opus 5 and several others - implementing standards-based identity lifecycle and synchronization across tenant boundaries is still its toughest category. Every task on our benchmark is original, unpublished, and scored by hand-written behavioral verifiers. Find the full report with the leaderboard, cost curves, and task-type breakdowns. https://www.hackerrank.com/bench/report